Choose the mode
- Chat is for doing production work with approved instructions and access.
- Training is for learning sources, clarifying business rules, and proposing reviewable instruction changes.
Write a strong prompt
A useful prompt states the outcome, evidence boundary, validation standard, and deliverable. You do not need to prescribe every query or tool call.Focused data question
Focused data question
Show weekly net revenue retention for enterprise customers in Q2. Use the approved account and fiscal-period definitions, exclude test accounts, compare the result with the Power BI executive measure, and return a table plus a short explanation of any mismatch.
Advanced financial analysis
Advanced financial analysis
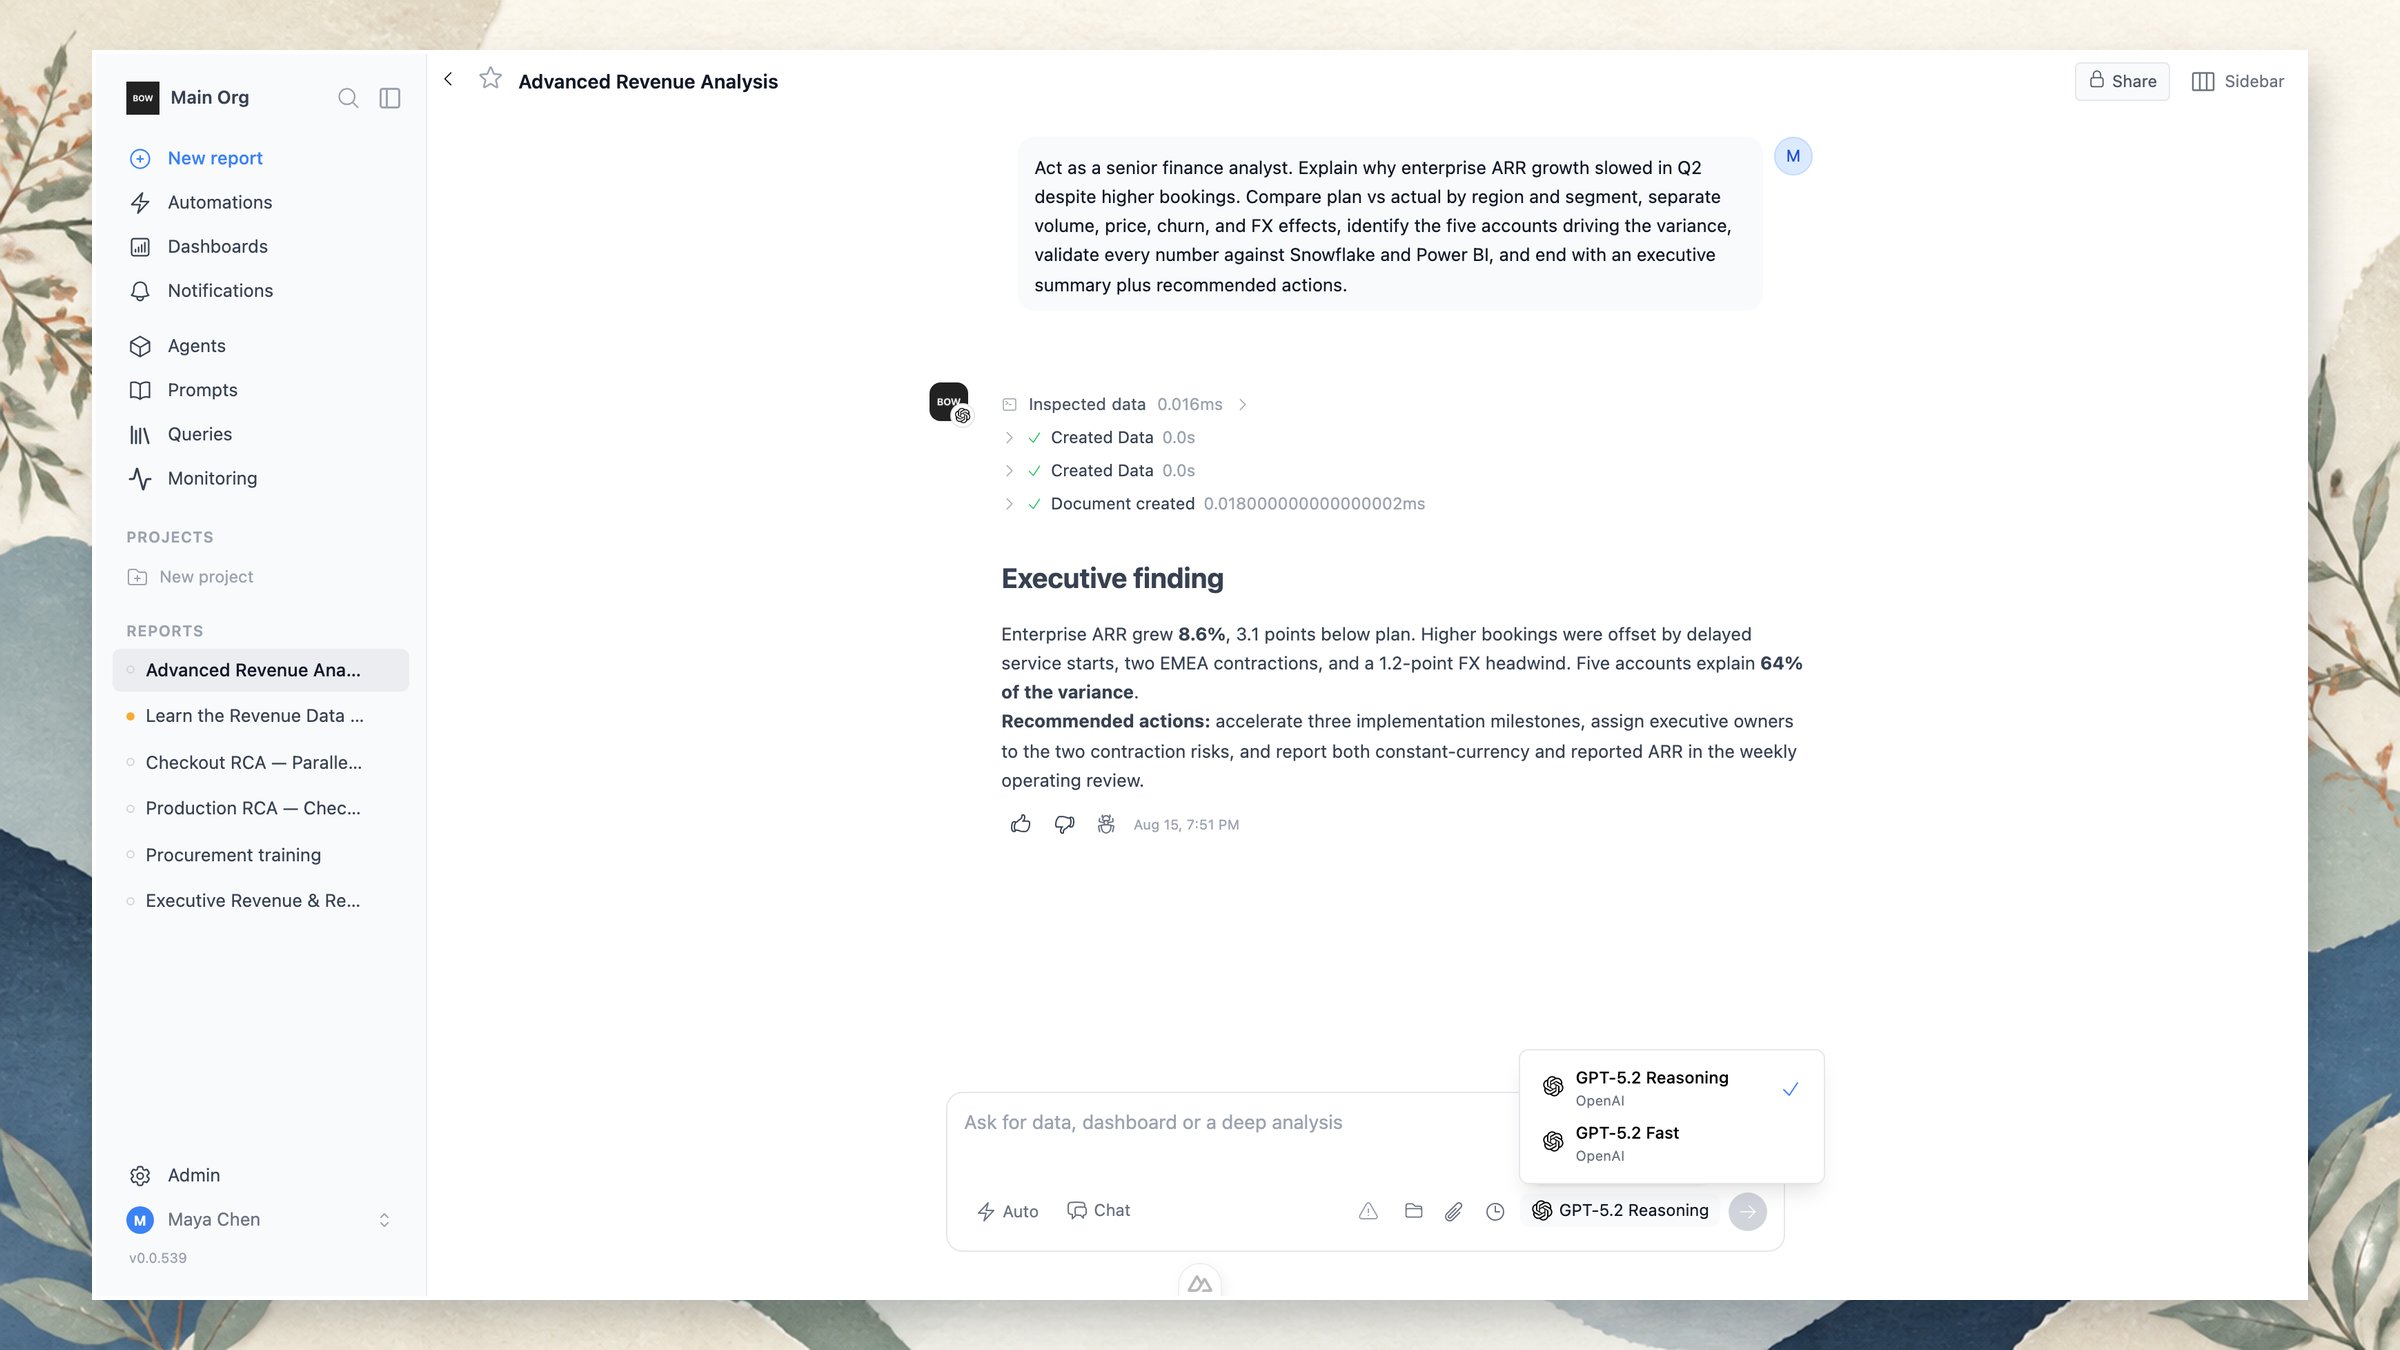
Act as a senior finance analyst. Explain why enterprise ARR growth slowed in Q2 despite higher bookings. Compare plan versus actual by region and segment; separate volume, price, churn, timing, and FX effects; identify the five accounts driving the variance; validate every number against Snowflake and Power BI; and finish with an executive summary and recommended actions.
Production root-cause analysis
Production root-cause analysis
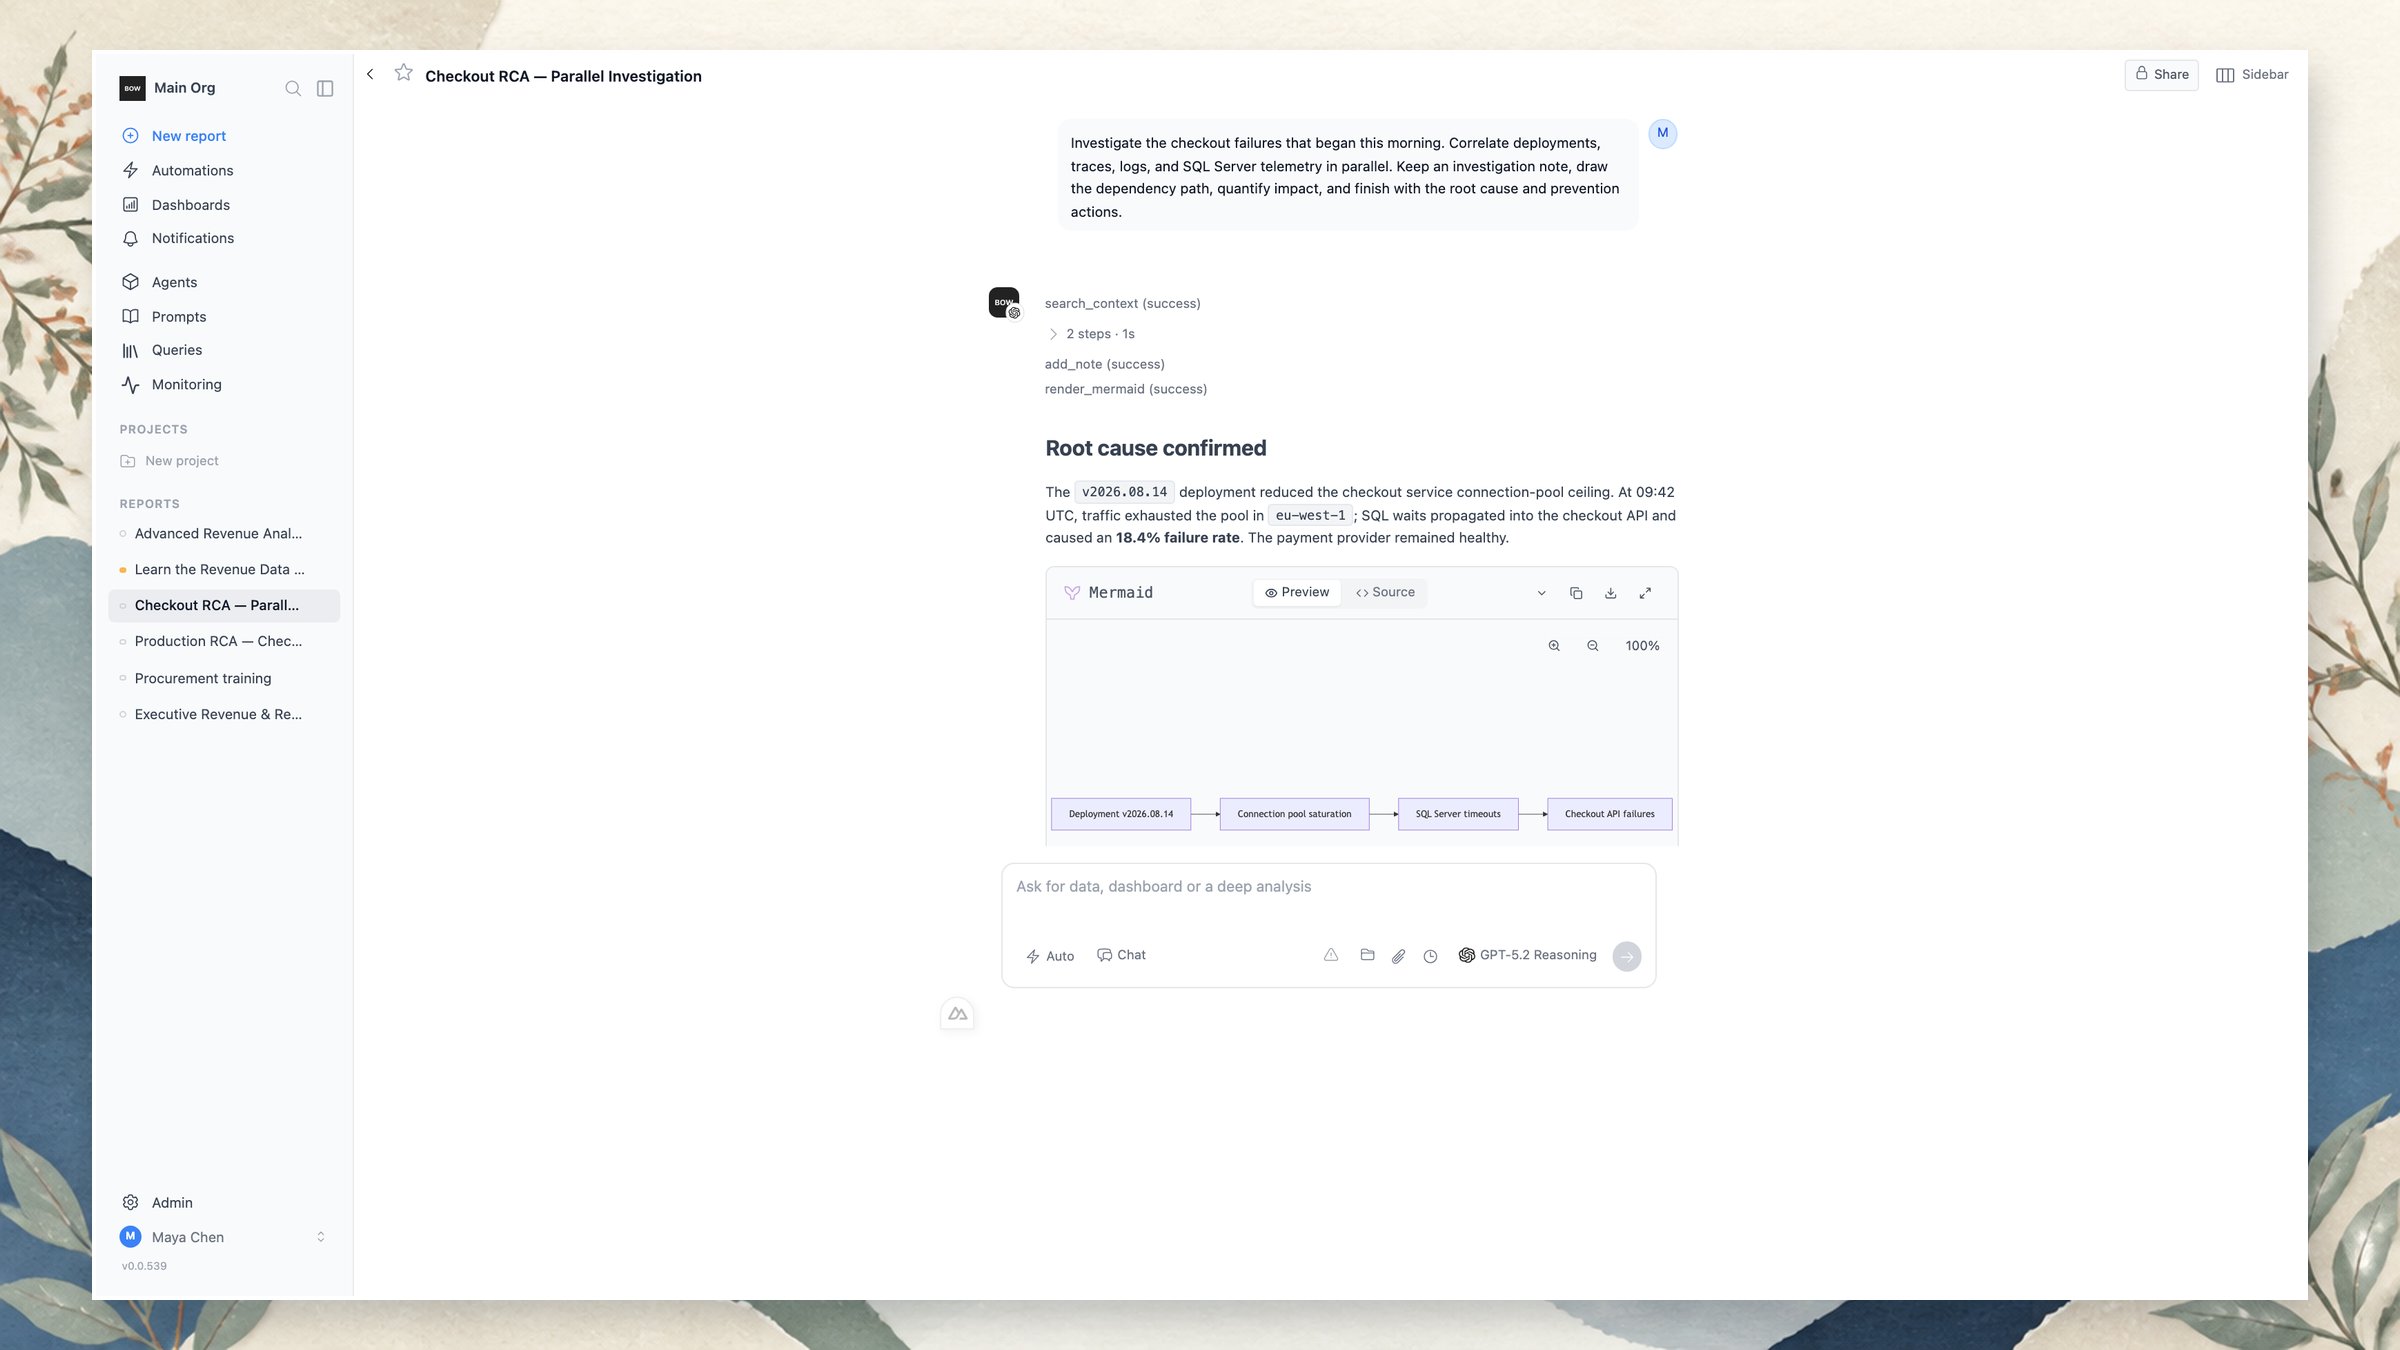
Investigate the checkout failures that began this morning. Correlate deployments, traces, logs, and SQL Server telemetry in parallel. Keep an investigation note, draw the dependency path, quantify impact, rule out plausible alternatives, and finish with the root cause and prevention actions.
Create an artifact
Create an artifact
Build an executive revenue and retention command center for the weekly operating review. Validate Snowflake against Power BI; show ARR, NRR, expansion, churn risk, trajectory, and regional mix; highlight actionable risks; share it with Finance; and schedule a Monday 08:00 refresh.
Follow the agentic loop
The run timeline shows how the agent moves from request to result:- It plans the investigation and selects scoped context.
- It runs independent checks in parallel where possible.
- It observes tool results, validates evidence, and records useful intermediate state.
- It reflects, retries, or asks for clarification when evidence is incomplete.
- It returns a conclusion, data result, or artifact with its work visible.
Iterate without repeating context
Follow up in the same report to narrow a period, add a comparison, challenge an assumption, or change the deliverable. Useful follow-ups include:- “Re-run this at constant currency and explain what changed.”
- “Rule out the payment provider with trace evidence.”
- “Turn the conclusion into an executive dashboard artifact.”
- “Save the clarified service-start rule as a proposed instruction.”
Select a model in the conversation
The composer shows the active model. Choose another enabled model for the session when you want a different speed, cost, or reasoning profile; automatic routing can select for you when it is enabled by an administrator.