# Evals and self-improvement
Source: https://docs.bagofwords.com/agents/evals
Verify agent behavior with suites and cases, then improve it through governed feedback loops.
Evals make reliability measurable. A suite groups cases that describe expected behavior for an agent or the organization. Each case supplies a prompt and expectations such as the right data use, a required answer property, or an LLM-as-judge criterion.
## Scope evals where they belong
Create **agent-scoped** suites for domain-specific behavior, such as “the Finance agent uses the approved revenue definition.” Create **global** suites for organization-wide behavior that every agent should satisfy.
Suites, cases, runs, and results live in the Agents workspace so the people responsible for an agent can inspect and improve it in context.
## Run and inspect
Run a single suite or multiple suites. Each run records its status, result summary, duration, and the underlying conversation. Use the result detail to distinguish an answer-quality issue from a missing instruction, an unavailable source, a tool failure, or an incorrect expectation.
Test behavior in the mode that matters: Chat for production behavior and Training for controlled improvement work.
## Self-improvement loop
When a case fails, use the evidence to improve the knowledge harness:
1. Inspect the failed run and its context.
2. Decide whether the missing control is an instruction, data scope, tool policy, model setting, or an eval expectation.
3. Create or review a proposed instruction change.
4. Re-run the relevant suite.
5. Promote the change only when the result is satisfactory.
Self-improvement is therefore governed improvement, not unreviewed autonomous rewriting.
# Instructions and knowledge
Source: https://docs.bagofwords.com/agents/instructions
Manage reusable, governed agent knowledge across agents, data, channels, and modes.
Instructions capture the business knowledge and operating rules that a schema alone cannot express: canonical metrics, calculation rules, preferred sources, validation checks, tool-use guidance, and domain vocabulary.
![A Training conversation with a pending AI-proposed tracked instruction change]() ## Instructions are many-to-many
An instruction is not owned by one agent. It can apply:
* Globally across the organization.
* To one or many agents.
* To selected tables or semantic objects.
* To all channels or selected channels.
* To **all modes**, **Chat only**, or **Training only**.
This lets a finance definition be reused by Finance and Executive Operations agents, while a training-only rule can be tested before affecting production Chat runs.
## Create useful instructions
Write instructions that give an agent an actionable decision rule. State the definition, its scope, and the exception it should handle. For example, specify the canonical revenue table and exclusions rather than saying only “be careful with revenue.”
Use load behavior deliberately:
* **Always** for rules that must affect every applicable run.
* **Intelligent** for relevant reference knowledge that the agent should retrieve when needed.
* **Disabled** when preserving a draft or retired rule.
## Organize and review knowledge
The Agents workspace provides global and agent-level instruction views. Use folders, labels, search, and **All Instructions** to manage knowledge across the fleet. Review the pending-changes view to see proposed edits, accept or reject specific changes, and keep the live knowledge base intentional.
Every published change belongs to an instruction build. Builds preserve the active snapshot, history, **tracked diff**, reviewer decision, and rollback path. Reviewers can inspect exactly what the AI proposes to add or remove before a suggestion becomes active.
## Git and generated suggestions
You can synchronize instructions from Git-backed documentation and model metadata, or create them manually. In Training, an agent can clarify an ambiguous rule, use the answer as evidence, and suggest a tracked instruction change. The suggestion remains a draft until a reviewer accepts it; rejected suggestions stay visible in the build history rather than silently changing production knowledge.
For verification, see [Evals and self-improvement](/agents/evals). The home page explains how instructions participate in the Knowledge Harness and the governed self-improvement loop.
# Agents
Source: https://docs.bagofwords.com/agents/overview
Build governed domain agents from scoped connections, knowledge, tools, and access controls.
An agent packages the context and capabilities needed for a business or operational domain. It is not the same thing as a connection: a connection reaches a system, while an agent scopes one or more connections into a governed assistant for work such as Finance, Sales, System Logs, or Procurement.
![Agents connected to Snowflake, Power BI, SQL Server, Oracle, and PostgreSQL]() An agent can include:
* One or many connections.
* Selected tables, semantic objects, files, directories, and tool providers.
* A description and conversation starters.
* Instructions shared with other agents or scoped specifically to this agent, a table, or an object.
* Eval suites that verify the agent’s expected behavior.
* Members, permissions, credentials, channel availability, and lifecycle status.
## Configure an agent
Open **Agents** from the main navigation and create a new agent, or select an existing one. Configure a clear domain name and description, then attach the data and tools it needs.
Keep the agent’s scope focused. An agent with a small, well-understood set of tables, files, and tools is easier to govern and usually produces better work than an agent attached to every available source.
## Scope data and tools
Use the agent tree to manage its capabilities:
* **Tables and objects** — enable only the database tables, BI objects, or semantic models the agent should use.
* **Files** — upload reference files or attach file and directory connections.
* **Tools** — add MCP or Custom API connections, enable the tools that matter, and choose their approval policies.
* **Instructions** — add or attach reusable knowledge and behavior rules.
* **Evals** — organize suites and test cases beside the agent they verify.
## Chat and Training modes
Agents can be used in **Chat** mode for production work and **Training** mode for controlled improvement workflows. Instructions can apply to all modes, Chat only, or Training only. Use this distinction to test a new behavior before making it part of regular work.
## Access and delivery
An agent can be private to selected people and groups or made available to everyone in the organization. You can also control which channels can reach it, such as the web app, scheduled work, or external channels.
Manage reusable, many-to-many knowledge and behavior rules.
Test agent behavior and turn verified failures into reviewed improvements.
# Custom queries
Source: https://docs.bagofwords.com/bow-fast/custom-queries
Write the SQL once, put it on a schedule, and choose which agents may use it
A custom query is the unit of work in BOW Fast: SQL an admin authors on a connection, materialized on a schedule into an encrypted local copy that agents query.
## Creating one
Open a connection's tables page and choose **Add custom query**. The dialog has three tabs.
### Query
Give the relation a name and write the SQL in the **source's own dialect** — this is the query BOW runs against your database.
The name is what agents will see, so `revenue_by_region` beats `q1`. It must start with a letter or underscore, use only letters, digits and underscores, and stay under 64 characters.
**Preview** runs the query bounded to 100 rows and shows the columns you will get. Your SQL is executed exactly as written rather than wrapped in a subquery, so a preview of `ORDER BY amount DESC` shows the rows you actually asked for.
Where the source can say in advance what a query will cost, the preview shows that too — BigQuery reports it exactly and for free, via a dry run — along with a projection of what the schedule you have chosen will scan per day.
**Write the description.** It is the only thing telling an agent what the relation holds. `revenue_summary` on its own does not say whether it is per order, per region, or per month — and an agent that has to guess the grain will get it wrong.
### Settings
Choose the refresh schedule — either every N minutes, or daily at a fixed time in your organization's timezone. This tab also holds manual refresh and delete.
### Row-level security
Available once the query is saved. See [Row-level security](/bow-fast/row-level-security).
## Choosing a schedule
The schedule is a cost decision, not a freshness preference. Each fire is a full run of your SQL against the source.
| Data changes | Asked about | Reasonable interval |
| --------------- | ------------------ | ------------------------------------ |
| Continuously | Many times an hour | Every 15–60 minutes |
| Through the day | A few times a day | Hourly, or daily at a fixed time |
| Nightly batch | Whenever | Daily, shortly after the batch lands |
If the answer to "how often will anyone ask this?" is "rarely", a daily refresh is almost always right. See the [break-even](/bow-fast/overview#what-it-costs).
## Activating it for an agent
A custom query belongs to the **connection**, and one copy is shared by every agent that uses it. Each agent then activates it separately, from its tables page — new agents start with it off.
That split is deliberate: a single extraction serves many agents, rather than N agents extracting the same data N times on N schedules. It also means the two actions need different permissions — authoring needs `manage_connection` on the connection, while switching an existing query on for one agent needs only `manage` on that agent.
## What the agent sees
The cached relation appears on a companion connection named `::fast`, and it speaks **DuckDB SQL** regardless of what the underlying source supports. Joins, CTEs, and window functions work against a cached rollup exactly as they would against Postgres.
The agent is told the relation is cached, is asked to prefer it over re-deriving the same figures from raw tables, and is given two timestamps:
* **as of** — when the copy was last refreshed
* **next refresh** — when it refreshes next
Those belong together. "As of 09:00" means "perfectly current" on a daily schedule and "eight hours behind" on an hourly one, and only the pair lets an agent tell someone whether a figure is worth re-checking.
## Safeguards
An admin can write `SELECT * FROM orders` against a two-billion-row table. Three independent layers stop that taking anything down:
Where the source can estimate a query without executing it, the estimate is checked at save time and before every refresh. A query projected to blow a ceiling is rejected with the reason.
Rows stream from the source in batches straight into the copy, so memory use does not grow with result size.
On a breach the partial copy is discarded and **the previous one keeps serving**, so a runaway refresh degrades to stale data rather than no data.
Defaults:
| Ceiling | Default |
| --------------------------------------- | ---------- |
| Rows in the result | 5,000,000 |
| Size of the result | 2 GB |
| Time per refresh | 30 minutes |
| Bytes scanned at the source per refresh | 100 GB |
The scan ceiling is deliberately far larger than the result ceiling. A rollup that reads 50 GB to produce 5,000 rows is the *best* kind of custom query, not one to refuse — that ceiling exists to catch a refresh that quietly costs real money every hour.
Only one refresh runs at a time per connection, and a refresh that is aborted or times out asks the source to stop the statement rather than abandoning it to run on unattended.
## Refresh status
Each custom query records the outcome of its last refresh — success, failure with the error, or in progress — along with how long it took and how many rows it produced. A failed refresh does not remove the previous copy; agents keep answering from the last good one until a refresh succeeds.
## Related
What BOW Fast is for, what it costs, and which connectors support it.
Filter one shared copy per person.
# Overview
Source: https://docs.bagofwords.com/bow-fast/overview
Prepare a database for agent analysis: a governed, materialized copy that is fast to query and filtered per person
A production database is built for the application that owns it. An agent asking questions of it is a different workload, and often an awkward guest: it explores, it retries, it asks the same thing five ways, and it has no idea which tables are expensive.
BOW Fast prepares a database for that workload. A connection admin defines the queries worth exposing, and BOW re-runs them on a schedule into an encrypted local copy that agents query instead of the source.
Write the SQL once, put it on a schedule, choose which agents may use it.
Filter one shared copy per person, against their attributes, groups, or roles.
## What preparing a database buys you
A legacy Oracle or SQL Server box no longer sees an agent's bursts. One measured six-query agent workload went from 24 statements against the source to none.
A local columnar copy answers in about 1–2 ms where the live source took tens of milliseconds, or over a second on a cloud warehouse.
Snowflake and BigQuery bill for every scan. An agent's variations read a local file instead of re-scanning gigabytes each time.
One shared copy, filtered at read time against who is asking — without reproducing the source's permission model by hand.
There is a fifth benefit that is easy to miss: **the copy speaks full SQL regardless of the source.** Agents get joins, CTEs, and window functions over a cached rollup even when the underlying system supports none of them.
## Curation is the point, not a side effect
The cached relation is not a mirror of a table. It is a query an admin chose to expose, with a name and a description they wrote.
That matters more than the speed. An agent handed 400 raw tables has to guess which ones matter and how they join; an agent handed `revenue_by_region_monthly` with a sentence explaining its grain has the business definition already encoded. The same mechanism that spares the source also narrows what the agent has to reason about.
Agents are told which relations are cached and asked to prefer them over re-deriving the same figures from raw tables.
## What it costs
A refresh is a full run of your SQL against the source. That makes BOW Fast a trade, not a free win:
**A copy refreshed more often than it is queried costs more than it saves.** An hourly refresh that nobody queries is 24 full scans a day bought for nothing. Match the interval to how often people actually ask, not to how fresh you wish the data were.
Measured against live accounts, the break-even is low — roughly **1.8 agent questions per refresh on BigQuery** and **1.0 on Snowflake**. Past that, the copy is cheaper than the source.
Latency, unlike cost, improves unconditionally. Mean time to answer one agent question, six questions per source:
| Source | Live | Cached |
| -------------------- | -------- | ------- |
| BigQuery (213M rows) | 1.37 s | 1.33 ms |
| Snowflake (60M rows) | 1.45 s | 1.43 ms |
| PostgreSQL 16 | 33.13 ms | 2.16 ms |
| SQL Server 2022 | 46.03 ms | 1.45 ms |
| Oracle Free 23ai | 20.73 ms | 1.66 ms |
The three on-prem engines ran as containers on one machine, so their live figures carry no network latency — treat them as a floor, not as what a database across a VPN will give.
## When not to use it
* The answer must be current to the second. A copy is as fresh as its last refresh, and no fresher.
* The question genuinely needs the full detail table rather than a rollup or a filtered slice.
* Nobody asks often enough to earn back the refresh. See the warning above.
## Requirements
1. **The feature is on.** BOW Fast is beta and off by default. An admin enables **Custom queries** under AI settings.
2. **The connector supports it** (see below).
3. **The connection uses shared credentials.** On a per-user connection, one materialized copy cannot represent each person's row visibility. [Row-level security](/bow-fast/row-level-security) is how you filter a shared copy instead.
4. **You have `manage_connection`** on the connection. Activating an existing cached query for a specific agent is a separate, lighter permission — `manage` on that agent.
## Supported connectors
| Connector | Status |
| -------------------- | ------------------------------- |
| PostgreSQL | Verified against a live server |
| MySQL / MariaDB | Verified against a live server |
| SQLite | Verified against a live server |
| Microsoft SQL Server | Verified against a live server |
| Oracle Database | Verified against a live server |
| Snowflake | Verified against a live account |
| Google BigQuery | Verified against a live account |
| Microsoft Fabric | Implemented, not yet verified |
| Sybase SQL Anywhere | Implemented, not yet verified |
The last two are offered but have never been run end to end against a real server. Their SQL and streaming paths are implemented and unit-tested; their cost estimation and query cancellation are not proven. Expect the safeguards to be weaker there, and test on non-critical data first.
Connectors not listed simply do not show the option.
In the product this feature is labelled **Custom queries (beta)** — that is the name of the setting you enable and the button you click. "BOW Fast" is the capability those custom queries provide.
## Security
The copy is a **DuckDB database file encrypted at rest**, with a per-artifact key stored encrypted alongside the connection. That is a boundary, not just compliance: agent-generated Python cannot read an encrypted DuckDB file with pandas, and the key never enters the sandbox.
Agents can only name relations that were put in their catalog, so an agent cannot reach a cached query it has not been given.
## Related
Why BOW Fast needs shared credentials, and what per-user auth changes.
Where an admin turns Custom queries on for the organization.
# Row-level security
Source: https://docs.bagofwords.com/bow-fast/row-level-security
Filter a shared materialized copy per person, against their profile attributes, groups, or roles
A materialized copy is built once, with the connection's shared credential. It therefore holds every row that credential could see — which is exactly what makes it fast, and exactly what makes it dangerous to hand to everyone.
Row-level security makes that copy safe to share, by filtering it at read time against who is asking.
This is what lets a single prepared copy serve a whole organization. Without it, the alternative to a shared copy is one copy per audience — N extractions on N schedules, against the source you were trying to protect.
## How a policy is defined
A policy binds a **column in the cached relation** to an **identity source**:
| Identity source | Matches against |
| --------------------- | -------------------------------------------------------- |
| `profile.` | A synced profile attribute, such as department or office |
| `user.email` | The person's email address |
| `groups` | Their group memberships |
| `roles` | Their roles in Bag of words |
A relation with a `department` column bound to `profile.department` shows each person only the rows for their own department. Someone in two groups sees the union of both.
On top of that, **grants** widen access for specific principals — per group and per role — and a "sees everything" grant exists for the people who need the whole picture.
## Two properties worth knowing
**Enforcement is structural, not a rewritten query.** Agent-generated SQL is arbitrary; subqueries, CTEs, unions and lateral joins give a dozen ways to lose an appended predicate. Instead, each request gets a private catalog containing only the rows that person may read, and the raw copy is detached before any agent SQL runs. There is no unfiltered copy left for a query to reach.
**An unresolved identity sees nothing.** If someone carries no value for the attribute a policy binds to — never signed in through the identity provider, or a background job with no user at all — the default is zero rows rather than all of them. This can be inverted per relation, but it starts closed, because the failure mode of the opposite default is handing over the whole table.
## Testing before you save
**Preview as** runs the policy against a member you choose and shows exactly the rows they would get — before the policy is saved. Use it on someone in a narrow department and someone with a wide grant; the two results together tell you whether the binding is doing what you meant.
**Preview as** here tests an RLS *policy* on the cached copy. It is not the same as a dashboard's [**View as**](/using-bow/dashboards#preview-as-another-viewer), which previews a shared, personalized artifact as another viewer. Both answer "what would this person see?", but one tests a policy and the other tests a dashboard.
## Auditing
Policy changes are recorded in the audit log with both the old and the new rule, so a widening is visible after the fact and attributable.
## Current limits
Phase 1 supports **attribute mode**: a column, an identity source, and per-principal grants. The operator is set membership, which covers equality as the single-value case.
Not yet available:
* SQL-expression policies
* A conformance check that diffs the filtered copy against the source's own answer under the user's credential
* Per-group materialization
RLS filters the **cached copy**. It does not read the source's own row-level security — if your database already enforces per-user visibility, the copy was built with the shared credential and knows nothing about those rules. Model them here, or use a per-user connection and query live.
## Related
Creating the relation a policy applies to.
Shared credentials versus per-user sign-in, and when each is right.
# Email
Source: https://docs.bagofwords.com/channels/email
Give the analyst its own mailbox — send answers by email and (optionally) receive questions
The Email integration gives the Bag of words analyst **its own mailbox** (e.g., `analyst@acme.com`) — like a teammate with an inbox. BOW connects **outbound** to that one mailbox: it **sends** via SMTP and, optionally, **reads** incoming mail via IMAP. It never exposes an inbound port and never logs in as your end users.
* **Outbound only** — the analyst sends answers, scheduled reports, and notifications by email.
* **Inbound enabled** — the mailbox becomes a full channel: users email the analyst a question and get an answer back, with the conversation saved as a BOW report.
This is a **channel**, not a data source. If you instead want the agent to search and read a user's *own* mailbox as data, see the [Gmail and Outlook Mail connectors](/data-sources/connectors/mail). The two are configured separately and can be used together.
## Authentication options
Basic Auth (passwords) is being phased out by Microsoft and Google, so BOW authenticates to cloud mailboxes with **OAuth over IMAP/SMTP (XOAUTH2)**. Pick the method matching your environment:
| Your environment | Auth method in BOW |
| ---------------------------------------------------------------------- | -------------------------------------- |
| On-prem Exchange, or any mailbox that still allows IMAP/SMTP passwords | **Username & password** |
| Microsoft 365 / Exchange Online | **Microsoft 365 (OAuth app-only)** |
| Google Workspace | **Google Workspace (service account)** |
The mailbox credential is separate from your SSO sign-in config — same tenant, but a distinct, least-privilege credential. Don't reuse the Entra/Google app you configured for user login.
Everything is configured at **Settings → Integrations → Email** in BOW.
***
## Option A: Microsoft 365
**You need:** Entra admin (app registration + consent) and Exchange admin (mailbox grant). \~10 minutes.
### Step 1: Create the mailbox
In the Microsoft 365 admin center, create the address. A **shared mailbox** (`analyst@acme.com`) is ideal — it's free (no license), has no interactive sign-in, and app-only access works on it.
### Step 2: Register an Entra application
1. Go to **Microsoft Entra admin center → Identity → Applications → App registrations → New registration**.
2. Name it (e.g., "BOW Analyst Mailbox"), choose **Accounts in this organizational directory only**, and click **Register**.
3. From the app's **Overview**, copy the **Directory (tenant) ID** and **Application (client) ID**.
### Step 3: Add the mail permissions (Exchange Online, not Graph)
1. In the app → **API permissions → Add a permission → APIs my organization uses** → search **Office 365 Exchange Online**.
2. Choose **Application permissions** and add:
* `SMTP.SendAsApp` — to send mail
* `IMAP.AccessAsApp` — to read mail (only needed for inbound)
3. Click **Grant admin consent** (required — there's no user to consent for app-only access).
### Step 4: Create a client secret
**Certificates & secrets → New client secret** → copy the **Value** immediately.
### Step 5: Scope the app to this one mailbox
By default the app could access any mailbox — this restricts it to just the analyst's. In **Exchange Online PowerShell** (`Connect-ExchangeOnline`):
```powershell theme={null}
# Register the app's service principal in Exchange.
# ObjectId is the *Enterprise application* object id, NOT the App registration object id.
New-ServicePrincipal -AppId -ObjectId -DisplayName "BOW Analyst Mailbox"
# Grant read access to only this mailbox.
Add-MailboxPermission -Identity analyst@acme.com -User -AccessRights FullAccess
# Allow sending as this mailbox.
Add-RecipientPermission -Identity analyst@acme.com -Trustee -AccessRights SendAs
```
### Step 6: Connect in BOW
In **Settings → Integrations → Email**, choose **Microsoft 365**, and enter the mailbox address, **Tenant ID**, **Client ID**, and **Client Secret**. Toggle **inbound** on if the analyst should receive questions by email. SMTP/IMAP hosts default to Office 365 automatically.
***
## Option B: Google Workspace
**You need:** Google Workspace super admin. \~10 minutes.
1. Create the mailbox user (e.g., `analyst@acme.com`) in the Google Admin console, and make sure IMAP is allowed for it.
2. In a Google Cloud project, create a **service account** and a **JSON key**.
3. Enable **domain-wide delegation** for the service account: in the Google Admin console (**Security → Access and data control → API controls → Domain-wide delegation**), add the service account's client ID with the scope `https://mail.google.com/`.
4. In **Settings → Integrations → Email** in BOW, choose **Google Workspace**, enter the mailbox address, and paste the **service account JSON**. Toggle **inbound** on if desired. SMTP/IMAP hosts default to Gmail automatically.
***
## Option C: Username & password
For on-prem Exchange or providers that still allow IMAP/SMTP passwords (or app passwords):
1. In **Settings → Integrations → Email**, choose **Username & password**.
2. Enter the **SMTP host/port/username/password** (and security mode — STARTTLS, SSL, or none).
3. For inbound, enter the **IMAP host/port/credentials** and toggle inbound on.
***
## How it's used
* **Outbound**: the analyst sends answers, notifications, and scheduled report deliveries from the mailbox, as `From: Bag of words Analyst ` (the display name is configurable).
* **Inbound** (if enabled): users email the analyst directly. BOW polls the inbox, matches the sender to a BOW account by email address, runs the question with that user's permissions, and replies in the same email thread. Each thread maps to a BOW report, same as chat channels.
# Google Chat
Source: https://docs.bagofwords.com/channels/google-chat
Chat with the analyst from Google Chat — outbound-only Pub/Sub connection, no public URL required
The Google Chat integration lets users in your Google Workspace domain DM the Bag of words analyst directly from Google Chat. It uses **Google Cloud Pub/Sub**: Google publishes chat events to a topic in your GCP project, and BOW **pulls** them over an outbound connection.
Because BOW pulls events outbound, **your server never needs to be reachable from the internet** — no public URL, no inbound firewall rules. This makes Google Chat a good fit for locked-down enterprise deployments.
## Capabilities
* **Direct messages** — users DM the analyst app one-on-one in Google Chat.
* **Threaded replies** — answers land in a thread on the user's message; replying continues the same conversation and report.
* **Auto-linking by email** — Google vouches for the sender's email, so users whose email matches a BOW account are linked automatically on first message.
* **Status feedback** — the bot posts a 👀 *"Working on it…"* message while processing and removes it when the answer is ready.
* **Report links** — every conversation is saved as a BOW report, with a link posted in the thread.
***
## How to integrate
You'll need admin access to BOW, a Google Cloud project, and permission to configure a Chat app for your Workspace domain.
Use a **dedicated Google Cloud project** for this integration. In particular, never enable the *"Make this Chat app available as a Google Workspace add-on"* option — switching a Chat app to add-on mode is effectively irreversible and will break Pub/Sub event delivery for the project.
### Step 1: Create a project and enable the APIs
1. In the [Google Cloud Console](https://console.cloud.google.com), create a new project (e.g., `bow-chat`).
2. Enable two APIs for the project (**APIs & Services → Enable APIs**):
* **Google Chat API**
* **Cloud Pub/Sub API**
### Step 2: Create the Pub/Sub topic
1. Go to **Pub/Sub → Topics → Create Topic** and name it (e.g., `bow-chat-events`).
2. On the topic's **Permissions** tab, click **Add Principal** and grant:
* **Principal**: `chat-api-push@system.gserviceaccount.com` (Google's Chat service account)
* **Role**: **Pub/Sub Publisher**
If your organization enforces the **Domain Restricted Sharing** policy, this grant will fail with "IAM policy update failed" because the principal is outside your domain. A project admin can override the `iam.allowedPolicyMemberDomains` policy at the **project** level (set it to *Allow all*), apply the grant, and optionally restore the policy — the check happens at write time only.
### Step 3: Create the subscription
1. Go to **Pub/Sub → Subscriptions → Create Subscription**.
2. Name it (e.g., `bow-chat-events-sub`), select the topic from Step 2, and keep **Delivery type: Pull**.
3. Note the full subscription name — you'll paste it into BOW:
```text theme={null}
projects/YOUR-PROJECT-ID/subscriptions/bow-chat-events-sub
```
### Step 4: Create a service account for BOW
1. Go to **IAM & Admin → Service Accounts → Create Service Account** (e.g., `bow-chat-sa`).
2. Grant it the **Pub/Sub Subscriber** role (on the project, or just on the subscription).
3. Open the service account → **Keys → Add Key → Create new key → JSON**, and download the key file.
### Step 5: Configure the Chat app
1. Go to **APIs & Services → Google Chat API → Configuration**.
2. Fill in the app identity:
* **App name** (e.g., "BOW"), **Avatar URL**, and **Description**
3. Under **Interactive features**:
* Toggle interactive features **On**
* Enable **Receive 1:1 messages**
4. Under **Connection settings**, select **Cloud Pub/Sub** and enter the **topic** name from Step 2 (`projects/YOUR-PROJECT-ID/topics/bow-chat-events`).
5. Under **Visibility**, make the app available to your domain (or specific people/groups).
6. Set **App status** to **Live** and click **Save**.
### Step 6: Connect in BOW
1. In BOW, go to **Settings → Integrations** and open the **Google Chat** integration.
2. Paste the full **subscription name** from Step 3 and the **service account JSON** key from Step 4.
3. Click **Connect**. BOW validates the credentials by performing a real pull against the subscription before saving.
***
## How to use
1. In Google Chat, start a DM with the app (search for its name under **Apps**).
2. Send a question. If your email matches a BOW account you're linked automatically; the bot confirms once.
3. The bot posts 👀 *"Working on it…"* in the thread, then replies with the answer and a link to the full report, removing the working marker when done.
4. Reply in the thread to continue the conversation — follow-ups extend the same report.
Google Chat messages are capped at \~4,000 characters; longer answers are split across messages. Charts and data files are summarized in the thread with a link to the full report in BOW, since Google Chat apps can't upload files with app credentials.
## Troubleshooting
* **"bow is not responding"** — check the topic's **Metrics** tab for publish requests. If Google isn't publishing at all, check **Cloud Logging** for `ChatAppLogEntry` errors, and verify the app is **not** in Workspace add-on mode (see the warning above — if it is, create a fresh project).
* **Nothing arrives in BOW** — verify `chat-api-push@system.gserviceaccount.com` has **Publisher on the topic** (not Subscriber on the subscription), and that the BOW service account has **Subscriber** on the subscription.
# OAuth Apps
Source: https://docs.bagofwords.com/channels/oauth-apps
Let your own applications sign users in to BOW and call the BOW API with OAuth 2.1 and PKCE
Use Bag of Words as the identity and data backend for your own application. Each person signs in to BOW, your app receives a short-lived user token, and every API request continues to use that person's organization membership and permissions.
BOW supports the OAuth 2.1 Authorization Code flow with PKCE `S256`. Use the `app` scope for reports, completions, artifacts, and the rest of the BOW API.
OAuth handles both local BOW accounts and configured single sign-on providers. Your application always redirects to BOW; BOW handles the user's local or Microsoft Entra ID sign-in and returns them to your registered callback.
## Recommended architecture
For production web applications, use a backend-for-frontend:
```text theme={null}
Browser → Your application backend → BOW API
↑
OAuth tokens stay here
```
The browser starts sign-in through your backend. The backend stores the PKCE verifier and OAuth tokens in the user's encrypted session, calls BOW with the access token, and streams the BOW response back to the browser.
This architecture needs no BOW CORS configuration because backend-to-backend requests are not subject to browser CORS.
A browser-only application can also use PKCE as a public client. If its JavaScript calls BOW directly from another origin, the BOW deployment must explicitly allow that origin with `BOW_CORS_ALLOWED_ORIGINS`. Never use `*`; list exact origins instead. See [Embed BOW Chat](/guides/embed#browser-only-apps-and-cors).
## Register an OAuth app
You need the `manage_settings` permission.
1. In BOW, open **Settings → Channels → OAuth Apps**.
2. Select **Register app**.
3. Enter a recognizable app name.
4. Select **BOW app** for API access. Select **MCP tools** only when the same client also connects to BOW's MCP endpoint.
5. Add every allowed redirect URI, one exact URI per line.
6. Enable **Trusted** only for an internal application operated by your organization.
7. Register the app and copy its client ID. Store the one-time client secret if your backend will use it.
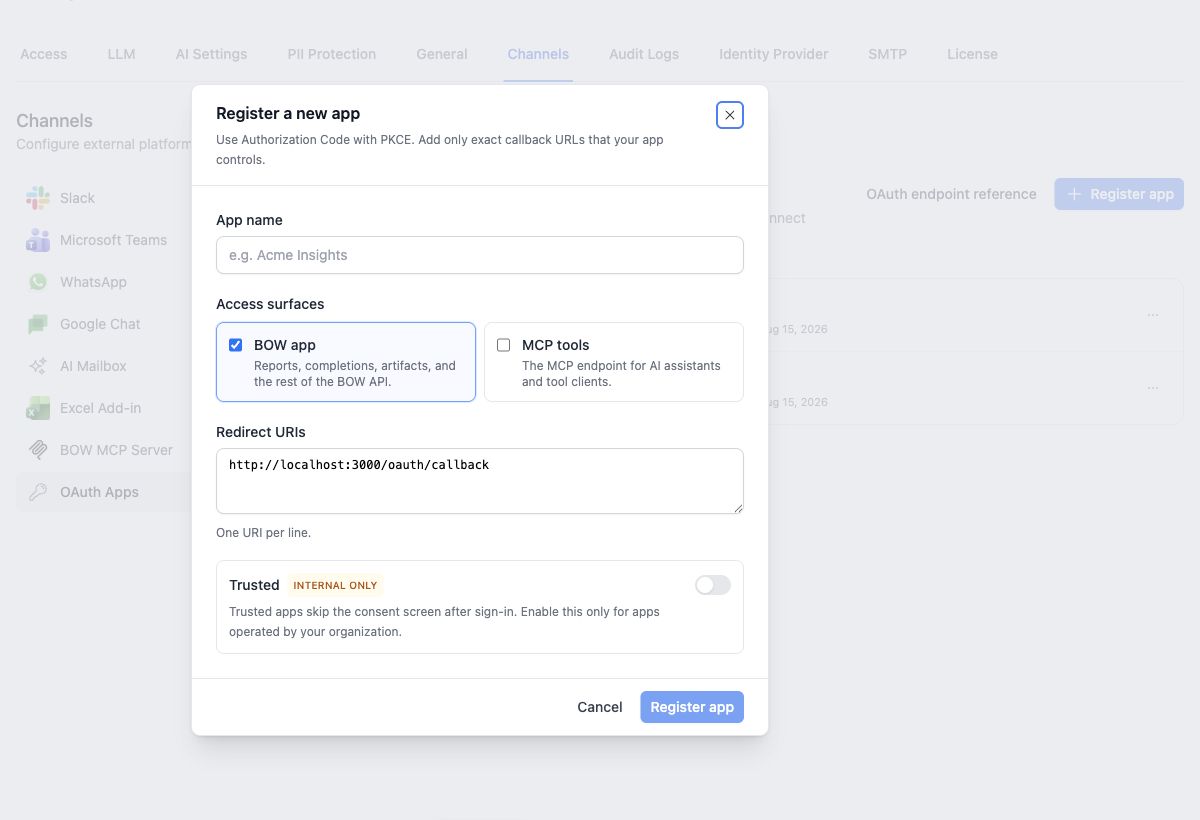
Redirect URIs must match exactly, including scheme, hostname, port, path, and trailing slash.
A public PKCE client does not need the client secret. A backend application should store it server-side and include it at the token endpoint.
## Access surfaces
| Scope | Access |
| ----- | ------------------------------------------------------------------------ |
| `app` | Reports, completions, artifacts, and the rest of the BOW application API |
| `mcp` | The BOW MCP endpoint for AI assistants and MCP clients |
Scopes separate the two surfaces; they do not replace BOW permissions. An `app` token can perform only the actions its user can already perform in that organization. An `app`-only token cannot call MCP, and an `mcp`-only token cannot call the application API.
Changing an app's access surfaces revokes its existing authorization codes, access tokens, and refresh tokens.
## Sign-in and consent
Send the browser to BOW's authorization endpoint:
```http theme={null}
GET {BOW_URL}/api/oauth/authorize
?response_type=code
&client_id={CLIENT_ID}
&redirect_uri={URL_ENCODED_CALLBACK}
&scope=app
&state={RANDOM_STATE}
&code_challenge={PKCE_CHALLENGE}
&code_challenge_method=S256
```
If the user does not have a BOW session, BOW shows its sign-in page. The user can sign in with a local account or any configured provider, including Microsoft Entra ID. To configure Entra for the BOW deployment, see [Microsoft Entra ID sign-in](/install#for-microsoft-entra-id-azure-ad).
After sign-in:
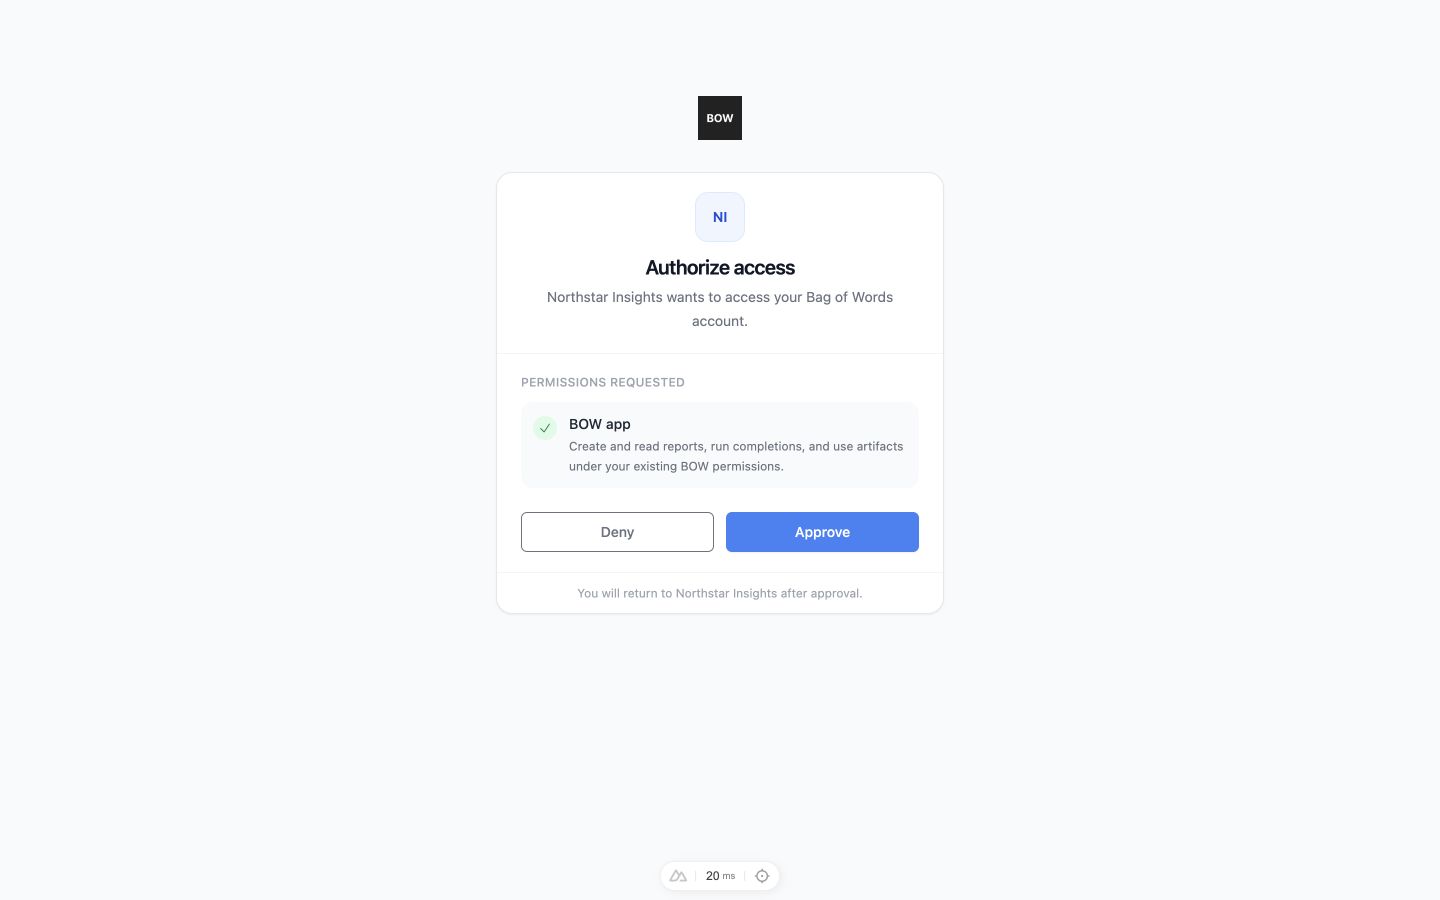
* A regular app shows the BOW consent screen.
* A **Trusted** app is approved automatically and returns immediately to its callback. Trusted skips consent, not authentication.
* If the user selects **Deny**, BOW returns `error=access_denied` and the original `state` to the callback. No authorization code or token is created.
Always generate and validate `state` to protect the redirect flow.
`code_challenge` is the **unpadded** base64url SHA-256 of your verifier. In Python, `base64.urlsafe_b64encode` pads by default — strip it with `.rstrip(b"=")`, or the flow fails later at the token endpoint with `invalid_grant`. See [Set up OAuth](/guides/embed#set-up-oauth) for the full snippet in both languages.
## Exchange the authorization code
At the callback, verify `state`, then exchange the short-lived code with the original PKCE verifier:
```ts TypeScript theme={null}
const body = new URLSearchParams({
grant_type: "authorization_code",
client_id: CLIENT_ID,
code,
redirect_uri: CALLBACK_URL,
code_verifier,
});
// Backend clients can also send:
// body.set("client_secret", CLIENT_SECRET);
const response = await fetch(`${BOW_URL}/api/oauth/token`, {
method: "POST",
headers: { "Content-Type": "application/x-www-form-urlencoded" },
body,
});
if (!response.ok) throw new Error(`Token exchange failed: ${response.status}`);
const tokens = await response.json();
```
```python Python theme={null}
import httpx
data = {
"grant_type": "authorization_code",
"client_id": CLIENT_ID,
"code": code,
"redirect_uri": CALLBACK_URL,
"code_verifier": code_verifier,
}
# Backend clients can also send:
# data["client_secret"] = CLIENT_SECRET
response = httpx.post(f"{BOW_URL}/api/oauth/token", data=data)
response.raise_for_status()
tokens = response.json()
```
The response contains:
```json theme={null}
{
"access_token": "bow_oauth_...",
"token_type": "Bearer",
"expires_in": 28800,
"refresh_token": "bow_rt_...",
"scope": "app"
}
```
Authorization codes expire after five minutes and can be used once. App access tokens expire after eight hours.
## Call the BOW API
Send the access token as a bearer token:
```http theme={null}
POST /api/reports
Authorization: Bearer bow_oauth_...
Content-Type: application/json
```
Do not send `X-Organization-Id` to choose another organization. The organization is pinned to the OAuth app and token. BOW also rechecks the user's membership on every request; removing the user from the organization stops the token immediately.
See [Embed BOW Chat](/guides/embed) for report creation, streaming completions, tool events, artifacts, resume, and cancellation examples.
## Refresh the session
Use the refresh token before or after the access token expires:
```ts TypeScript theme={null}
const body = new URLSearchParams({
grant_type: "refresh_token",
client_id: CLIENT_ID,
refresh_token,
});
// Backend clients can also send:
// body.set("client_secret", CLIENT_SECRET);
const response = await fetch(`${BOW_URL}/api/oauth/token`, {
method: "POST",
headers: { "Content-Type": "application/x-www-form-urlencoded" },
body,
});
const nextTokens = await response.json();
```
```python Python theme={null}
import httpx
data = {
"grant_type": "refresh_token",
"client_id": CLIENT_ID,
"refresh_token": refresh_token,
}
# Backend clients can also send:
# data["client_secret"] = CLIENT_SECRET
response = httpx.post(f"{BOW_URL}/api/oauth/token", data=data)
next_tokens = response.json()
```
Refresh tokens last up to one year and rotate on every successful refresh. Replace the stored refresh token atomically; the previous token cannot be reused.
## Discovery endpoints
Use discovery instead of hard-coding endpoint paths when practical:
| Metadata | URL |
| -------------------------- | ---------------------------------------------------- |
| Authorization server | `{BOW_URL}/.well-known/oauth-authorization-server` |
| BOW API protected resource | `{BOW_URL}/.well-known/oauth-protected-resource/api` |
| MCP protected resource | `{BOW_URL}/.well-known/oauth-protected-resource` |
The authorization server metadata advertises the authorize and token endpoints, supported scopes, PKCE method, and grant types.
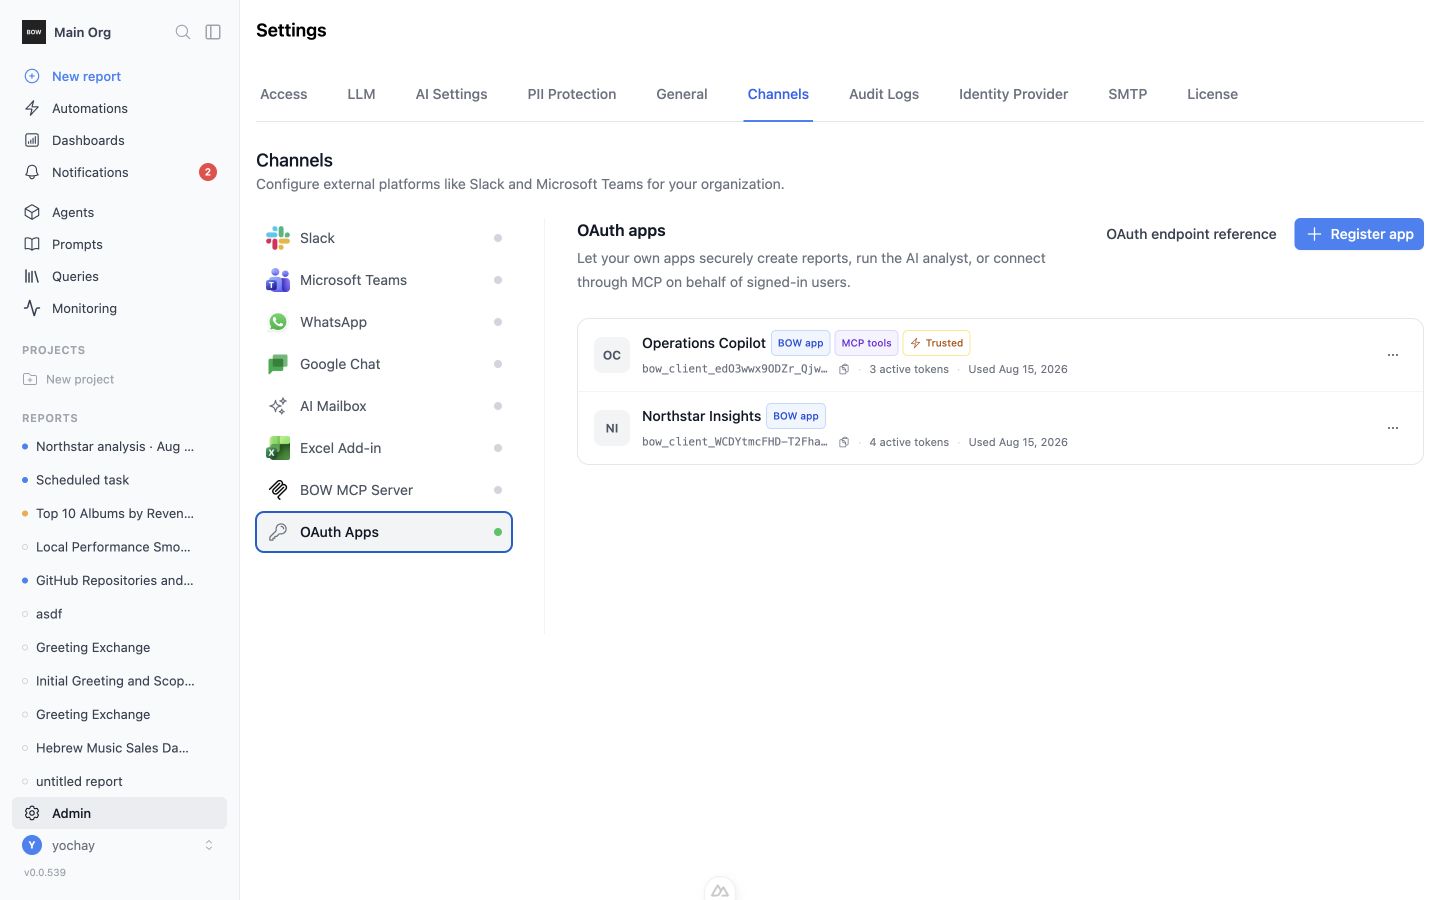
## Manage and revoke access
OAuth Apps shows each client ID, access surfaces, trusted status, active token count, and last-used time. Use its actions menu to:
* edit the name, scopes, trust setting, or redirect URIs
* rotate the client secret
* delete the app and revoke its codes and tokens
Treat **Trusted** as an organization-wide security decision. A trusted app receives access without an individual consent click after sign-in, so enable it only for software operated and reviewed by your organization.
# Channels Overview
Source: https://docs.bagofwords.com/channels/overview
Bring the Bag of words analyst to messaging tools and connect your own applications with OAuth
Channels connect the Bag of words analyst to the messaging tools your team already uses. Once a channel is integrated, users can ask data questions in plain language — from a Slack DM, a Teams channel, a Google Chat space, a WhatsApp message, or an email — and get answers with real data, without opening the BOW app.
Socket Mode by default — no public URL needed. Includes the Slack Agent experience.
Azure Bot–based integration for 1:1 chats and channel @mentions.
Pub/Sub-based — outbound-only, enterprise-friendly, no public URL needed.
Meta WhatsApp Business Cloud API integration.
Give the analyst its own mailbox — send answers and (optionally) receive questions.
Connect Claude, Cursor, or any MCP client to your data via the BOW MCP server.
Let your own applications sign users in to BOW and call the BOW API on their behalf.
## How channels work
All chat channels share the same core model:
* **Account linking** — every platform user maps to a BOW account, so all queries run with that user's permissions. On platforms that vouch for the user's email (Slack, Teams, Google Chat), accounts are **auto-linked by email** when it matches an existing BOW user (this can be disabled per integration). Otherwise, the bot sends a one-time verification link on first contact.
* **Thread = conversation** — each thread maps to a single BOW report. Replies in a thread continue the same conversation and context; a new message starts a new one. Every conversation is saved as a report in BOW, with a link posted back into the chat.
* **Permission-aware data access** — in public channels, only public agents (data sources) are queried, since answers are visible to everyone. In DMs, the user's private agents are available too.
* **Status feedback** — the bot signals progress while it works (for example 👀 → ✅ reactions on Slack, or a "Working on it…" message on Google Chat).
* **Per-agent channel availability** — each agent (data source) can be enabled or disabled per channel from its settings, so you control which data is reachable from which surface.
## Connectivity at a glance
Channels differ in how events reach your BOW server — which matters if your deployment sits behind a firewall with no public URL.
| Channel | How events arrive | Public URL required? |
| ---------------------------- | ---------------------------------------- | -------------------- |
| Slack (Socket Mode, default) | Outbound WebSocket to Slack | No |
| Slack (HTTP webhook) | Slack posts to your webhook | Yes |
| Google Chat | Outbound Pub/Sub pull from Google Cloud | No |
| Microsoft Teams | Azure Bot posts to your webhook | Yes |
| WhatsApp | Meta posts to your webhook | Yes |
| Email | Outbound SMTP/IMAP to your mail provider | No |
All channels and OAuth apps are configured by an admin under **Settings → Channels** in BOW.
# Slack
Source: https://docs.bagofwords.com/channels/slack
Let users ask data questions via Slack DMs and channel mentions — no public URL required with Socket Mode
The Slack integration installs a bot into your Slack workspace so users can chat with the Bag of words analyst directly from Slack — in DMs or by @mentioning the bot in channels. Each Slack user is linked to their BOW account, so every query runs with that user's permissions (see the [Channels Overview](/channels/overview) for the shared model).
## Capabilities
* **Direct messages and channel @mentions** — DM the bot one-on-one, or @mention it in a public channel.
* **The Slack Agent experience** — BOW registers as a Slack Agent: users get **suggested prompts** (sourced from your agents' conversation starters), a native **"is thinking…"** status while the bot works, and threaded agent conversations in the bot's Messages tab.
* **Threaded conversations** — every reply lands in a thread, and each thread maps to a single BOW report. Replying in a thread continues the same conversation.
* **Visual feedback** — 👀 means processing, ✅ means done.
* **Rich responses** — text, charts, and data files (CSV) delivered directly in Slack.
* **Permission-aware** — channel mentions query only public agents; DMs also include the user's private agents.
## Connection modes
| Mode | How it works | Requirements |
| -------------------------------------- | -------------------------------------------------------------------- | ------------------------------------------- |
| **Socket Mode** (default, recommended) | BOW opens an outbound WebSocket to Slack and receives events over it | No public URL, no signing secret |
| **HTTP webhook** | Slack posts events to your BOW server's webhook URL | Publicly reachable BOW URL + signing secret |
Socket Mode is the default for new setups — it works behind firewalls and VPNs since nothing needs to reach your server from the internet. Existing webhook-based integrations keep working unchanged.
***
## How to integrate (Socket Mode)
You'll need admin access to BOW and permission to create apps in your Slack workspace.
### Step 1: Create a Slack App
1. Go to the [Slack API dashboard](https://api.slack.com/apps) and click **Create New App** → **From scratch**.
2. Enter an **App Name** (e.g., "BOW") and pick your workspace, then click **Create App**.
### Step 2: Add Bot Token Scopes
In **OAuth & Permissions → Bot Token Scopes**, add:
* `app_mentions:read` — see channel messages that @mention the bot
* `assistant:write` — power the Agent experience (suggested prompts, status)
* `chat:write` — send messages
* `files:read`, `files:write` — receive and send files
* `im:history`, `im:read`, `im:write` — direct messages
* `reactions:read`, `reactions:write` — 👀 / ✅ status reactions
* `users:read`, `users:read.email` — map Slack users to BOW accounts by email
### Step 3: Enable the Agent experience
1. In your app's settings, go to **Agents & AI Apps** (under *Features*) and toggle it **On**.
2. This lets the bot appear as an Agent in Slack — with suggested prompts and a native thinking status in its Messages tab.
Third-party Agents are available on all paid Slack plans. On the free plan the bot still works as a regular app — you just won't get suggested prompts or the thinking status.
### Step 4: Enable Socket Mode and get the App-Level Token
1. Go to **Socket Mode** (under *Settings*) and toggle **Enable Socket Mode** on.
2. You'll be prompted to create an **App-Level Token** — name it (e.g., "socket"), give it the `connections:write` scope, and click **Generate**.
3. Copy the token that starts with `xapp-`. This is your **App Token**.
### Step 5: Subscribe to events
1. Go to **Event Subscriptions** and toggle it **On**. With Socket Mode enabled there is no Request URL to configure.
2. Under **Subscribe to bot events**, add:
* `message.im` — direct messages to the bot
* `app_mention` — @mentions in channels
* `app_home_opened` — lets BOW show suggested prompts when a user opens the bot
3. Click **Save Changes**.
### Step 6: Install the app and get the Bot Token
1. Go to **OAuth & Permissions** and click **Install to Workspace**, then authorize it.
2. Copy the **Bot User OAuth Token** that starts with `xoxb-`. This is your **Bot Token**.
### Step 7: Connect in BOW
1. In BOW, go to **Settings → Integrations** and open the **Slack** integration.
2. Select **Socket Mode** as the connection mode (the default).
3. Paste the **Bot Token** (`xoxb-...`) and the **App Token** (`xapp-...`), then click **Connect**.
4. BOW validates both tokens and opens the socket connection. The integration shows as connected.
***
## Alternative: HTTP webhook mode
If you prefer Slack to deliver events over HTTPS (your BOW server must be publicly reachable):
1. Skip Step 4 above (leave Socket Mode off).
2. In **Event Subscriptions**, set the **Request URL** to:
```text theme={null}
https://YOUR-BOW-URL.com/api/settings/integrations/slack/webhook
```
Slack will verify the URL and show a green checkmark.
3. Copy the **Signing Secret** from **Basic Information → App Credentials**.
4. In the BOW Slack modal, select **HTTP webhook** as the connection mode and paste the **Bot Token** and **Signing Secret**.
***
## How to use
### Account linking
If a user's Slack email matches their BOW account email, they are **linked automatically** on first contact — the bot confirms with a short message. Otherwise, the bot replies with a one-time verification link. (Auto-linking can be disabled in the integration settings.)
### Direct messages
1. Open the bot from the **Apps** section in Slack. With the Agent experience enabled you'll see suggested prompts at the top of the Messages tab — click one, or type your own question.
2. The bot adds 👀, shows an "is thinking…" status, and replies in a thread with the answer (text, charts, and data files), swapping 👀 for ✅ when done.
3. Reply in the thread to continue the same conversation — follow-ups extend the same report.
### Channel @mentions
1. In any public channel, @mention the bot with your question (e.g., "@BOW what were last month's sales?").
2. The bot responds in a thread on your message. Reply in the thread to continue.
When using channel mentions, only public agents are queried since responses are visible to everyone in the channel. For access to private agents, use DMs instead.
# Microsoft Teams
Source: https://docs.bagofwords.com/channels/teams
Let users ask data questions directly via Teams DMs and channel mentions
The Teams integration installs a bot into your Microsoft Teams tenant, allowing users to interact with BOW directly from Teams. Each Teams user is linked to their BOW account so all interactions run with the right permissions (see the [Channels Overview](/channels/overview) for the shared model).
Once linked, users can interact with the bot through Direct Messages (1:1 chats) or by @mentioning the bot in team channels. When a user sends a message to the bot, it processes the query, creates a report in BOW, and returns the result.
## Capabilities
* **Direct messaging** — interact with the bot in a 1:1 personal chat.
* **Channel @mentions** — mention the bot in any team channel to ask questions visible to the whole channel.
* **Threaded conversations** — each @mention in a channel starts a thread; replies within it continue the same conversation and report.
* **Rich responses** — text and markdown tables directly in Teams.
* **Permission-aware** — channel mentions query only public agents; DMs also include the user's private agents.
***
## How to integrate
This process requires:
* **Admin access to BOW** (to manage integrations)
* **Access to the Azure Portal** (to register a bot)
* **Admin access to Microsoft Teams** (to sideload the app)
Teams delivers events to BOW over HTTPS, so your BOW server must be reachable at a public URL.
### Step 1: Register a Bot in Azure
1. Go to the [Azure Portal](https://portal.azure.com).
2. Search for **Azure Bot** and click **Create**.
3. Fill in the required fields:
* **Bot handle**: A unique name for your bot (e.g., `bow-bot`)
* **Subscription**: Select your Azure subscription
* **Resource group**: Create new or select existing
* **Type of App**: Select **Multi Tenant**
* **Creation type**: Select **Create new Microsoft App ID**
4. Click **Review + Create**, then **Create**.
5. Once the resource is created, go to the bot resource.
### Step 2: Get the App ID and Client Secret
1. In the Azure Bot resource, go to **Configuration**.
2. Copy the **Microsoft App ID** — this is your bot's App ID.
3. Click **Manage Password** (next to the App ID) to go to the App Registration's **Certificates & secrets** page.
4. Click **New client secret**, give it a description, and click **Add**.
5. Copy the **Value** of the secret immediately (it won't be shown again). This is your **Client Secret**.
### Step 3: Configure the Messaging Endpoint
1. In the Azure Bot resource, go to **Configuration**.
2. Set the **Messaging endpoint** to your BOW application's webhook URL:
```text theme={null}
https://YOUR-BOW-URL.com/api/settings/integrations/teams/webhook
```
3. Click **Apply**.
### Step 4: Enable the Teams Channel
1. In the Azure Bot resource, go to **Channels**.
2. Click on **Microsoft Teams** to enable it.
3. Accept the terms and click **Apply**.
### Step 5: Connect in BOW
1. In BOW, navigate to **Settings > Integrations**.
2. Click **Integrate** (or **Settings**) for the Microsoft Teams integration.
3. A modal will appear. Enter the following:
* **App ID**: The Microsoft App ID from Step 2
* **Client Secret**: The client secret value from Step 2
* **Tenant ID**: Your Microsoft 365 tenant ID (found in [Azure Active Directory > Overview](https://portal.azure.com/#view/Microsoft_AAD_IAM/ActiveDirectoryMenuBlade/~/Overview))
4. Click **Connect**. If successful, the modal will close and the UI will show that Teams is connected.
### Step 6: Create the Teams App Manifest
Create a folder with three files:
**manifest.json**
```json theme={null}
{
"$schema": "https://developer.microsoft.com/en-us/json-schemas/teams/v1.16/MicrosoftTeams.schema.json",
"manifestVersion": "1.16",
"version": "1.0.0",
"id": "YOUR-APP-ID-HERE",
"packageName": "com.yourcompany.bot",
"accentColor": "#4F46E5",
"developer": {
"name": "Your Company",
"websiteUrl": "https://your-domain.com",
"privacyUrl": "https://your-domain.com/privacy",
"termsOfUseUrl": "https://your-domain.com/terms"
},
"name": {
"short": "BOW Bot",
"full": "Bag of Words Bot"
},
"description": {
"short": "Ask questions about your data",
"full": "Ask questions about your data via Teams"
},
"icons": {
"color": "color.png",
"outline": "outline.png"
},
"bots": [
{
"botId": "YOUR-APP-ID-HERE",
"scopes": ["personal", "team", "groupChat"],
"supportsFiles": false,
"isNotificationOnly": false
}
],
"permissions": ["identity", "messageTeamMembers"],
"validDomains": ["YOUR-BOW-DOMAIN.com"]
}
```
Replace `YOUR-APP-ID-HERE` with the Microsoft App ID from Step 2, and `YOUR-BOW-DOMAIN.com` with your BOW instance domain.
**color.png** — A 192x192 full-color icon for your bot.
**outline.png** — A 32x32 transparent outline icon for your bot.
### Step 7: Install the Bot in Teams
1. Zip the three files together:
```bash theme={null}
cd your-manifest-folder
zip -r ../bot.zip *
```
2. Open Microsoft Teams.
3. Go to **Apps** (in the left sidebar) → **Manage your apps** → **Upload an app**.
4. Select **Upload a custom app** and choose the `bot.zip` file.
5. Click **Add** to install the bot.
If you see an error about a duplicate App ID, go to **Apps → Manage your apps**, find the existing app, and click **Update** to upload the new version instead.
***
## How to use
### Account linking
If a user's Teams email matches their BOW account email, they are linked automatically on first contact. Otherwise the bot responds with a verification card — click **Verify Account** and log in to BOW to link the accounts. This is a one-time step.
### Chat with the bot
**Option A: Direct Messages (1:1 Chat)**
1. Open a 1:1 chat with the bot in Teams.
2. Send your query or command.
3. The bot will reply with a link to the new report, followed by the response with text and data.
4. Continue the conversation by sending more messages — follow-up messages will extend the same report.
**Option B: Channel @Mentions**
1. In any team channel, @mention the bot followed by your question (e.g., "@BOW Bot what were last month's sales?").
2. The bot will respond in a thread on your message.
3. Reply in the thread (with @mention) to continue the conversation.
In channels, the bot only receives messages where it is @mentioned — this is a Teams platform requirement. In 1:1 chats, no @mention is needed.
When using channel mentions, only public agents are queried since responses are visible to everyone. For access to private agents, use DMs instead.
# WhatsApp
Source: https://docs.bagofwords.com/channels/whatsapp
Let users ask data questions over WhatsApp via the Meta WhatsApp Business Cloud API
The WhatsApp integration connects BOW to a WhatsApp Business phone number through Meta's **WhatsApp Business Cloud API**. Users message your business number and get analyst answers right in WhatsApp.
Meta delivers incoming messages to BOW over HTTPS webhooks, so your BOW server must be reachable at a **public URL**. If your deployment can't expose one, consider [Slack Socket Mode](/channels/slack) or [Google Chat](/channels/google-chat), which connect outbound-only.
## Capabilities
* **Direct messaging** — users chat 1:1 with your business number.
* **Conversation continuity** — consecutive messages from the same user continue the same BOW report until the conversation goes stale (configurable).
* **Rich responses** — text answers with data, plus links to the full report in BOW.
***
## Prerequisites
* A **Meta Business Portfolio** and a **Meta developer app** with the **WhatsApp** product added ([developers.facebook.com](https://developers.facebook.com))
* A **WhatsApp Business Account (WABA)** with a registered phone number
* Admin access to BOW, and a publicly reachable BOW URL
## How to integrate
### Step 1: Collect your WhatsApp credentials
From your Meta app's **WhatsApp → API Setup** page, collect:
1. **Access token** — for production use, create a **System User** in Meta Business Settings and generate a permanent token with the `whatsapp_business_messaging` and `whatsapp_business_management` permissions. (The temporary token on the API Setup page expires in 24 hours — fine for testing only.)
2. **Phone number ID** — the ID of the business phone number (not the number itself).
3. **WhatsApp Business Account ID (WABA ID)**.
### Step 2: Get the App Secret and choose a Verify Token
1. **App Secret**: in your Meta app, go to **App Settings → Basic** and copy the **App Secret**. BOW uses it to verify webhook signatures (`X-Hub-Signature-256`).
2. **Verify Token**: invent any random string (e.g., a UUID). You'll enter the same value in both BOW and the Meta webhook configuration.
### Step 3: Connect in BOW
1. In BOW, go to **Settings → Integrations** and open the **WhatsApp** integration.
2. Enter the **Access Token**, **Phone Number ID**, **WABA ID**, **App Secret**, and your chosen **Verify Token**.
3. Click **Connect**. BOW validates the token against the phone number before saving.
### Step 4: Configure the webhook in Meta
1. In your Meta app, go to **WhatsApp → Configuration → Webhook** and click **Edit**.
2. Set the **Callback URL** to:
```text theme={null}
https://YOUR-BOW-URL.com/api/settings/integrations/whatsapp/webhook
```
3. Enter the same **Verify Token** you used in Step 3 and click **Verify and save** — Meta calls your BOW server to confirm.
4. Under **Webhook fields**, subscribe to **`messages`**.
***
## How to use
1. Users send a WhatsApp message to your business number.
2. On first contact, the bot links the WhatsApp number to a BOW account (via a verification link if it can't be matched automatically).
3. The bot replies with the answer and a link to the full report in BOW.
4. Follow-up messages continue the same conversation until it goes stale — the staleness window (default: hours) is configurable in the integration settings.
WhatsApp enforces a **24-hour customer service window**: the bot can only send free-form replies within 24 hours of the user's last message. If the window has closed, the user just needs to send a new message to reopen it.
# Authentication and Access
Source: https://docs.bagofwords.com/data-sources/authentication
Shared credentials vs per-user sign-in, OAuth, Kerberos SSO, and what requires Enterprise
Every connection authenticates in one of two ways. The choice determines whose permissions the agent's queries run under, and it is the single most important security decision when adding a data source.
This page is about how a **connection** reaches a data source. For how people sign in **to Bag of words** — auth modes, OIDC and Entra ID, Google, and LDAP — see [Sign-in and SSO](/sign-in-and-sso).
## The two auth policies
One credential set, configured once by an admin. Everyone who can use the data source queries through it. The default.
Each user supplies their own credentials or signs in with their own account. Queries run with that person's permissions in the source system.
Per-user authentication is what you want when the source system already models who may see what — a Power BI tenant, a SharePoint site, a warehouse with row-level security. Instead of reproducing those rules inside Bag of words, you let the source enforce them.
You choose the policy with the **Require user authentication** toggle when creating or editing a connection. When it is on, you also choose which sign-in methods users may use — for most connectors that list is filled in for you.
**Integrations are always per-user.** MCP connections that use OAuth, and personal sources like OneDrive, Google Drive, and mailboxes, are per-user by definition — each user's own account is the catalog.
## What requires Enterprise
Per-user authentication is **included for file and tool connections** — MCP servers, custom APIs, OneDrive, Google Drive, SharePoint, mailboxes. There is no license check on those.
Per-user authentication on **database-style connections** — anything the agent sees as tables, such as PostgreSQL, Snowflake, SQL Server, or Power BI — requires an Enterprise license. Turning the toggle on without one returns:
```text theme={null}
Per-user authentication for this connector requires an enterprise license.
```
Separately, a number of connectors are Enterprise-only in their entirety, regardless of auth policy — Power BI, Power BI Report Server, Tableau, Qlik Sense, Qlik Sense on-prem, Sisense, Oracle BI, Analysis Services, Infor OLAP, Splunk, Zabbix, Timbr, Sybase, QVD, SharePoint, OneDrive, Google Drive, Gmail, and Outlook Mail. They appear in the catalog with a lock until a license key is set. See [License Key](/enterprise/license).
## Sign-in methods
Which methods a connector offers is set by the connector itself; each connector page lists its own. The recurring ones:
| Method | How it works | Typical connectors |
| ----------------------------- | --------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------- |
| Username and password | Credentials stored encrypted, used for every query | Most databases |
| Key pair / certificate | A private key instead of a password | Snowflake, Salesforce |
| Service account | A machine identity (JSON key, client secret, PAT) | BigQuery, Power BI, Databricks, Tableau |
| OAuth (per-user) | Each user signs in with their own account; BOW stores and refreshes their token | Power BI, Fabric, Snowflake, SharePoint, OneDrive, Google Drive, ServiceNow, Monday, SAP Datasphere, MCP |
| Kerberos | The service's own ticket, from a keytab on the host | SQL Server |
| Kerberos delegated (per-user) | The service impersonates the caller via constrained delegation — no stored secret | SQL Server |
| API key / token | A single header token | Splunk, Zabbix, PostHog, Timbr, MCP, Custom API |
| None | The environment supplies access (mounted share, instance IAM role) | Files and Directories, S3, SQLite |
## How users sign in
For a per-user connection, each person connects once:
1. Open the data source (or try to use it in a chat).
2. If it uses OAuth, you are sent straight to the provider's consent screen and back. If it uses credentials, a dialog asks for them, with a **Test** button before saving.
3. Credentials are encrypted at rest and tied to your account; OAuth tokens refresh automatically.
Until a user connects, queries against that data source fail with a clear prompt rather than silently falling back to someone else's access:
```text theme={null}
Connect required: this connection runs queries with your own credentials.
```
Users can re-test, replace, or remove their credentials at any time, and refresh their own schema view — a per-user connection shows each person only the tables or files their own account can reach.
## Query identity
On connections that support per-user OAuth, an admin can choose which identity **their own** queries use:
* **Self** — the admin's own account, like everyone else. The default.
* **Service account** — the shared credentials stored on the connection.
This exists so admins can curate a catalog, run indexing, and verify a connection works without needing personal access to every object. It applies to admins and connection owners only; regular users always query as themselves.
Background work that has no user — scheduled indexing, catalog refresh, warm-up — uses the connection's stored credentials. This is why a per-user connection can still keep a shared catalog current.
## Per-viewer dashboards
A per-user connection is also what powers **personalized dashboards**. When a dashboard is shared with **Viewer** run identity, each viewer's queries run under their own credentials — so a source that enforces row-level security filters per person, and one shared artifact shows each viewer only their own rows. See [personalizing a dashboard](/using-bow/dashboards#personalize-a-dashboard-per-viewer) and [identity parameters](/using-bow/parameterized-queries#where-a-value-comes-from).
## Access control on top of authentication
Authentication decides *whose* permissions apply. Two other layers decide who can reach the data source at all:
* **Members** — who in your organization can use this data source, set on the data source's settings tab.
* **Tool policies** — for MCP and Custom API connections, each tool is `allow`, `ask`, or `deny`, resolved per user. See [MCP connections](/data-sources/mcp).
## Related
Constrained delegation with protocol transition, step by step.
Delegated OAuth against a Power BI tenant.
# Connecting a Data Source
Source: https://docs.bagofwords.com/data-sources/connecting
The setup flow: connect, choose tables, add context, and control access
Connecting a data source takes a few minutes. Making it *good* — so the agent answers accurately — is the part worth spending time on: the tables you enable, the description you write, and the instructions you attach are what separate a useful agent from one that guesses.
## Add the connection
1. Go to **Agents**, open the agent you want to extend, and add a connection from its data sources area.
2. Pick the connector. Use the category chips or search; Enterprise-only connectors show a lock if you have no license.
3. Fill in the connection fields and credentials. Every connector's fields are documented on its own page — see the [catalog](/data-sources/overview).
4. Decide whether this connection uses shared credentials or [per-user authentication](/data-sources/authentication).
5. **Test** the connection, then save. Bag of words validates the credentials before storing them, so a saved connection is a working one.
Nothing is copied. Bag of words queries your data where it lives, every time, using the credentials you configured.
## Choose which tables the agent sees
Once connected, Bag of words reads the schema and lists what it found. Enable the tables (or files, or tools) the agent should use.
![Select Tables]() Enabling everything is usually a mistake. A focused set of well-understood tables produces better queries than a complete catalog the agent has to guess its way through. You can reload the list whenever your schema changes, and enable more later.
Start with the tables that answer your most common questions. Add more as real usage shows what's missing.
## Describe what the data means
The schema tells the agent what exists; the description tells it what things *mean*. This is the highest-leverage text you will write.
**Description** — the business domain, the key entities, and how they relate:
```text theme={null}
This data source is a database for a movie rental business. It tracks movies (films),
actors, customers, rentals, payments, and stores. Key tables include:
• film: details about each movie
• actor: information about actors
• customer: customer contact and account info
• rental: records of movie rentals by customers
• payment: payments made by customers
• store: store locations and staff
Movies are linked to actors (film_actor), categories (film_category), and inventory
(inventory). Customers are linked to rentals and payments. Staff manage stores and
transactions.
```
![Data Source Overview]() **Conversation starters** — prompts that appear as chips on the home page and in chat channels, guiding people toward analyses that work well:
* "Top Renting Actors"
* "Most Popular Film Categories"
* "Inactive Customers"
* "Store Performance Comparison"
Both can be edited at any time.
## Add instructions and import context from Git
Instructions encode business logic the schema can't express — how revenue is defined, which rows to exclude, which of two similar tables is canonical. You can write them by hand, or import them from a Git repository so your existing definitions stay the source of truth:
* **dbt** — model descriptions, column documentation, and relationships
* **LookML** — Looker models and their business logic
* **Tableau** — data models and calculated fields
* **Markdown** — any documentation file in the repo, such as `AGENTS.md`
* **Code** — SQL and Python files
Point Bag of words at the repo and it syncs automatically. See [Instructions](/using-bow/instructions) for how they are managed, versioned, and scoped, and [Git Workflow](/guides/git) for the repository setup.
![Context]() ## Control access
On the data source's settings tab:
* **Members** — who can use this data source, and at what permission level.
* **User authentication** — require each person to connect with their own credentials instead of sharing one set. See [Authentication and access](/data-sources/authentication).
* **Channel availability** — which chat channels this data source is reachable from. A source can be available in the web app but hidden from Slack, for example. See [Channels](/channels/overview).
## Keep the catalog fresh
Schemas drift. Reload the table list after a migration, and re-run indexing when you add objects. On Enterprise, connections can re-index on a schedule instead — either every N hours or at a fixed time of day — so the agent's picture of your data stays current without anyone remembering to refresh it.
## Best practices
* **Write a rich description.** More context about your domain means better queries.
* **Enable only relevant tables.** Don't make the agent sort through unused ones.
* **Name connections clearly.** "Production DB" beats "postgres-1".
* **Add instructions for business logic.** Definitions, filters, and calculation rules belong here, not in every user's prompt.
* **Create conversation starters.** They teach people what the agent is good at.
* **Use per-user auth for sensitive sources.** Let the source system enforce its own permissions.
# Microsoft Analysis Services
Source: https://docs.bagofwords.com/data-sources/connectors/analysis-services
Connect SSAS Multidimensional and Tabular models and query them with MDX or DAX over XMLA
Bag of words connects to **SQL Server Analysis Services (SSAS)** over **XMLA**, discovers every catalog and cube the account can see, and runs **MDX** or **DAX** against them. Both SSAS model types are supported: Multidimensional (MDX) and Tabular (DAX or MDX).
The Microsoft Analysis Services connector is part of the **Enterprise Edition**.
## How it works
XMLA is a SOAP-over-HTTP protocol. Bag of words posts to the endpoint URL you configure, authenticating with **HTTP Basic** on every request — XMLA is stateless, so there is no logon round-trip.
1. Lists catalogs (databases) with a `DBSCHEMA_CATALOGS` Discover.
2. Lists the cubes/models in each catalog (`MDSCHEMA_CUBES`).
3. Reads each cube's hierarchies (`MDSCHEMA_HIERARCHIES`) and measures (`MDSCHEMA_MEASURES`).
4. Runs MDX or DAX statements at query time with an XMLA `Execute` (`Format=Tabular`).
Each cube is exposed to the agent as a schema table named `Catalog/Cube` (for example `AdventureWorks/Sales`). Its columns are the cube's dimension hierarchies (`dtype="dimension"`) and measures (`dtype="measure"`); the unique name needed to write a query is carried in each column's `metadata.unique_name`.
**Model-type detection.** For each catalog, Bag of words probes the Tabular metadata DMV `SELECT * FROM $SYSTEM.TMSCHEMA_MODEL`. If it succeeds, the catalog is recorded as `TABULAR` (DAX and MDX both work); if it fails, the catalog is treated as `MULTIDIMENSIONAL`, which is always safe because MDX runs on both. Sending DAX at a Multidimensional target is rejected before the request leaves Bag of words, with an explicit "use MDX instead" error rather than a cryptic server fault.
## Before you start
* The SSAS **XMLA endpoint must be published over HTTP(S)**. SSAS's native protocol is TCP (port 2383 by default) and Bag of words does not speak it — the only supported transport is XMLA over HTTP, which means the **`msmdpump.dll` IIS pump** (see Step 1).
* The Bag of words backend host must be able to reach that URL. There is no path discovery and no redirect following: whatever URL works in `curl` is the URL to paste into the form, verbatim.
* The pump's IIS application must accept **Basic authentication** — that is the only scheme the connector sends.
* An SSAS account with read access to the databases you want to query.
* If the endpoint uses a certificate signed by an internal CA that the backend host does not trust, either install the CA or turn off **Verify SSL**.
## Step 1 — Publish the msmdpump HTTP pump in IIS
This is the step that most SSAS connections fail on. `msmdpump.dll` is an ISAPI extension that ships with Analysis Services and forwards XMLA requests received over HTTP to the SSAS instance. It is **not** enabled by default — an administrator has to publish it on a Windows server running IIS (usually the SSAS server itself). Microsoft documents the full procedure as *Configure HTTP Access to Analysis Services*.
The pump ships with SSAS under the instance's OLAP folder, in `bin\isapi`. Copy that folder's contents (including `msmdpump.dll` and `msmdpump.ini`) to a directory you will serve from IIS, for example `C:\inetpub\wwwroot\olap`.
Edit `msmdpump.ini` and set the server name to the Analysis Services instance the pump should forward to (for example `localhost` or `SERVER\INSTANCE`). A pump pointed at the wrong instance answers requests but shows no catalogs.
In IIS Manager, create an application (for example `/olap`) whose physical path is that directory, running in an application pool with **No Managed Code**. Allow the `msmdpump.dll` ISAPI extension under **ISAPI and CGI Restrictions** — a blocked extension is the usual cause of an HTTP 404 on an otherwise correct URL.
On the application's **Authentication** settings, enable **Basic Authentication**. The connector authenticates with HTTP Basic only; a pump that accepts Windows/Kerberos authentication exclusively rejects it with HTTP 401.
Basic authentication sends credentials on every request. Publish the pump over **HTTPS**, not plain HTTP.
The account you will use must have read access to the SSAS databases. Without it the connection succeeds but reports zero catalogs.
The endpoint URL is then the full path to the DLL:
```text theme={null}
https:///olap/msmdpump.dll
```
Quick liveness check: a working XMLA endpoint is **POST-only**, so a plain `GET` on it returns **HTTP 405**. A `404` means the URL path is wrong (or the ISAPI extension is blocked), never a broken client.
## Connect in Bag of words
Go to **Data Sources → Add data source → Microsoft Analysis Services** and fill in the form.
| Field | Required | Default | Notes |
| :------------ | :------- | :-------- | :------------------------------------------------------------------------------------------------------------------ |
| `host` | Yes | — | Full URL of the XMLA endpoint, typically the IIS pump: `https://server/olap/msmdpump.dll`. Used exactly as entered. |
| `catalog` | No | *(empty)* | Optional database/catalog to scope discovery to. Leave blank to list every accessible catalog. |
| `verify_ssl` | No | `true` | Verify the TLS certificate when calling the XMLA endpoint. |
| `timeout_sec` | No | `60` | HTTP timeout for XMLA calls, in seconds. |
**Test Connection** authenticates, runs a catalog Discover, and reports how many catalogs were found. Zero catalogs is reported as a success with the note *"No databases visible to this user — check permissions."*
## Authentication modes
| Mode | Scope | Fields |
| :---------------------- | :------------------ | :-------------------------------------------------------------------- |
| **Username / Password** | System and per-user | `username` — SSAS user for the XMLA endpoint (Basic auth); `password` |
This is the only mode. It can be used two ways:
* **System (shared)** — one admin-supplied SSAS account discovers and queries for everyone.
* **Per-user** — each user supplies their own SSAS credentials, so SSAS role membership and cell/dimension security apply to that person's queries.
Per-user authentication on database-style connectors requires an Enterprise license. See [Authentication](/data-sources/authentication).
## Querying
The agent writes MDX or DAX itself, picking the language from the model type recorded during discovery:
* **Multidimensional** cubes — MDX only.
* **Tabular** models — DAX preferred, MDX also accepted.
Cubes are addressed as `Catalog/Cube`, and members and measures are referenced by the unique names captured in the schema.
## Troubleshooting
The host answered but no XMLA service lives at that path. Check the path portion of the endpoint URL (it must end in `msmdpump.dll`), that the IIS application exists, and that the `msmdpump.dll` ISAPI extension is allowed.
The endpoint was reached but the logon failed. Either the username/password is wrong, or the IIS application does not have **Basic Authentication** enabled — the connector sends Basic and nothing else.
The account has no read access to any SSAS database, or `msmdpump.ini` points at a different instance than you expect. Grant the account read on the databases and re-test.
The backend host cannot resolve the name in the URL. Use a resolvable FQDN or an IP address.
Nothing answered on the port. Check firewall rules between the Bag of words backend and the IIS server, and the port in the URL. Raising `timeout_sec` helps only when the server is slow, not when it is unreachable.
The target catalog was detected as Multidimensional. This is a guard, not a failure of the connection — the same question can be answered with MDX. If the catalog really is Tabular, confirm the account can read `$SYSTEM.TMSCHEMA_MODEL`, which is how the model type is detected.
# Google BigQuery
Source: https://docs.bagofwords.com/data-sources/connectors/bigquery
Connect BigQuery datasets so the agent can read their schemas and run SQL, with per-query cost caps
Bag of words connects to **Google BigQuery** with a GCP service account, reads the tables and columns in the datasets you point it at (including table and column descriptions), and runs standard SQL query jobs. Each user can also sign in with their own Google account, so queries run under their own BigQuery permissions.
## How it works
Bag of words uses the BigQuery client library against one `project_id`. During indexing it reads `INFORMATION_SCHEMA.COLUMNS` and `INFORMATION_SCHEMA.TABLE_OPTIONS` in each dataset, so table and column **descriptions** you have set in BigQuery are picked up and given to the agent. If that enriched read fails on your configuration, it falls back to a plain table/column listing.
Tables are exposed to the agent as `dataset.table`. Queries run as BigQuery query jobs, with the cost controls below applied to every job.
## Before you start
* A **Google Cloud project** with BigQuery enabled and at least one dataset.
* Permission to create a **service account** and a key for it in that project (`roles/iam.serviceAccountKeyAdmin`, or ask a project admin).
* For per-user sign-in only: permission to create an **OAuth 2.0 client** under **APIs & Services → Credentials**, and a configured OAuth consent screen.
* Network access from the Bag of words host to `bigquery.googleapis.com`.
## Step 1 — Create the service account
This identity is the shared credential — it indexes the datasets and, unless you require per-user sign-in, runs everyone's queries.
In the [Google Cloud Console](https://console.cloud.google.com) → **IAM & Admin → Service Accounts → Create service account**. Name it something like `bow-bigquery`.
Grant, at project level or on the specific datasets:
* **BigQuery Data Viewer** (`roles/bigquery.dataViewer`) — read table data and metadata.
* **BigQuery Job User** (`roles/bigquery.jobUser`) — create the query jobs.
Bag of words only issues reads, so a viewer-level data role is sufficient and recommended.
On the service account → **Keys → Add key → Create new key → JSON**. The file downloads once.
The JSON key is a long-lived credential for the whole service account. Store it in your secret manager, paste it into Bag of words, and delete the downloaded file.
## Step 2 — Create an OAuth client (per-user sign-in only)
Skip this step if everyone will share the service account.
For **Sign in with Google**, Bag of words needs a Google Cloud **OAuth 2.0 client**, separate from the service account.
In the Console → **APIs & Services → Credentials → Create credentials → OAuth client ID**. Choose **Web application** as the type.
Under **Authorized redirect URIs**, add:
```text theme={null}
https:///api/connections/oauth/callback
```
Replace `` with your Bag of words base URL.
These go into the `oauth_client_id` and `oauth_client_secret` fields on the connection. Without both, per-user sign-in cannot start.
Bag of words requests the read-only BigQuery scope, `https://www.googleapis.com/auth/bigquery.readonly`, plus offline access so the token can be refreshed. Make sure that scope is allowed on your OAuth consent screen. If the app is in **Testing** status, add each user as a test user, or publish it internally.
## Step 3 — Add the connection in Bag of words
Go to **Data Sources → Add data source → Google BigQuery**.
| Field | Required | Default | Notes |
| :--------------------- | :------- | :------ | :-------------------------------------------------------------------------------------------------------------------- |
| `project_id` | Yes | — | GCP project that owns the datasets and is billed for the queries. |
| `dataset` | Yes | — | Dataset to index. Accepts a **comma-separated list** of datasets. |
| `maximum_bytes_billed` | No | — | Per-query cap on bytes billed. A query that would scan more fails instead of running. Leave blank to disable the cap. |
| `use_query_cache` | No | `false` | Allow BigQuery to return cached results when the same query has run before. Off by default. |
**Cost controls.** `maximum_bytes_billed` is the safety net worth setting first — it turns a runaway scan into a failed query rather than a bill. A value in the tens of gigabytes is a reasonable starting point for exploratory use. Turning on `use_query_cache` makes repeated identical queries free and instant, at the cost of possibly serving slightly stale results; leave it off if freshness matters more than cost.
## Authentication modes
| Mode | Scope | Fields |
| :------------------------------------------- | :--------------------- | :-------------------------------------------------------------------------- |
| **Service Account JSON** (`service_account`) | Shared **or** per-user | `credentials_json`, plus optional `oauth_client_id` / `oauth_client_secret` |
| **Sign in with Google** (`oauth`) | Per-user only | None — the user signs in interactively |
### Service Account JSON
Paste the contents of the downloaded key file into `credentials_json`. This is the identity used for schema indexing, and for queries whenever no per-user credential applies.
The `oauth_client_id` and `oauth_client_secret` fields live alongside it: they are not used by the service account itself, they are the OAuth client from Step 2 that per-user sign-in needs. Fill them in on the same connection if you plan to enable per-user access.
### Sign in with Google
Each user clicks **Connect** on the data source and completes a Google sign-in. Their token carries the read-only BigQuery scope, so discovery and queries run with **their own** BigQuery permissions — dataset-level access, row-level security, and audit logs all resolve to that person rather than the shared service account. Google access tokens last about an hour; Bag of words refreshes them automatically, so users sign in once.
To force this, enable **Require user authentication** on the connection. With `oauth_client_id` set, OAuth is added to the allowed sign-in methods automatically, and each person's **Connect** click goes straight to Google's consent screen and back. Indexing and schema refresh, which have no user in context, continue to run as the service account.
Per-user authentication on a database connector requires an Enterprise license. See [Authentication](/data-sources/authentication).
## Troubleshooting
The `credentials_json` field did not parse as JSON. Paste the **entire** contents of the key file, including the outer braces, and check nothing was truncated. A server-side file path is also accepted, but only if the file is readable by the Bag of words process.
The service account has a data role but not **BigQuery Job User**. Reads still need a query job. Grant `roles/bigquery.jobUser` on the project named in `project_id`.
The query would have scanned more than `maximum_bytes_billed`. Either raise the cap, or narrow the question — partition and clustering filters are the usual fix. This is the cap doing its job.
`oauth_client_id` and `oauth_client_secret` must both be set on the connection; sign-in fails immediately if either is missing. Also confirm the redirect URI registered on the OAuth client exactly matches `https:///api/connections/oauth/callback`.
Only the datasets listed in the `dataset` field are indexed. Add them as a comma-separated list, and confirm the identity in use has read access to each — with per-user sign-in, a dataset the service account can see may still be invisible to an individual, and vice versa.
## Related
* [Connecting data sources](/data-sources/connecting)
* [Authentication](/data-sources/authentication)
* [SQL databases](/data-sources/connectors/databases)
# Business applications
Source: https://docs.bagofwords.com/data-sources/connectors/business-apps
Connect Salesforce, NetSuite, ServiceNow, Monday and PostHog so the agent can query them as tables
These connectors reach SaaS applications through their own APIs and present them to the agent as **tables**. The agent writes queries in each platform's native language — SOQL for Salesforce, SuiteQL for NetSuite, a Table API query spec for ServiceNow, a board query spec for monday.com, HogQL for PostHog — and Bag of words handles discovery, paging and row limits.
| Connector | Query surface | Auth | Edition |
| :-------------------------- | :------------------------------------- | :----------------------------------------------- | :------ |
| [Salesforce](#salesforce) | SOQL over the REST API | Connected App (JWT bearer), or username/password | |
| [NetSuite](#netsuite) | SuiteQL over the REST API | Token-Based Authentication | |
| [ServiceNow](#servicenow) | Table API query specs | Username/password, or per-user OAuth | Beta |
| [Monday data](#monday-data) | Board query specs over the GraphQL API | API token, or per-user OAuth | Beta |
| [PostHog](#posthog) | HogQL | Personal API key | Beta |
***
## Salesforce
Bag of words enumerates the org's queryable objects — standard and custom `__c` — filtering out system and plumbing objects (sharing rows, field history, change events, Chatter feeds). Reference fields become foreign keys. Discovery is capped at 500 objects, with common CRM objects (Account, Contact, Lead, Opportunity, Case, and so on) prioritized so they always survive the cap. A single query returns at most 10,000 rows.
### Before you start (JWT bearer)
The recommended path is a **Connected App** using the OAuth 2.0 JWT bearer flow: a certificate signs a short-lived assertion that is exchanged for an access token. No interactive login, no stored password.
Create an RSA private key and a matching X.509 certificate. Keep the private key (PEM) — you will paste it into Bag of words.
In Salesforce **Setup → App Manager → New Connected App**, enable OAuth settings, tick **Use digital signatures**, and upload the certificate.
From the Connected App's detail page, copy the **Consumer Key** — this is the OAuth `client_id`.
Set the Connected App's OAuth policy to **Admin approved users are pre-authorized**, then grant the profile or permission set of the Salesforce user Bag of words will authenticate as.
The JWT flow fails if the app is not admin pre-authorized for that specific user. This is the most common cause of an authentication error on first connect.
### Fields
| Field | Required | Default | Notes |
| :-------- | :------- | :------ | :--------------------------------------------------------------------------------------- |
| `sandbox` | No | `false` | Authenticate against `test.salesforce.com`. |
| `domain` | No | `login` | Login domain: `login` (production), `test` (sandbox), or a My Domain subdomain. |
| `objects` | No | — | Comma-separated objects to index, e.g. `Account,Contact,MyObj__c`. Blank auto-discovers. |
### Authentication modes
Both modes are **system**-scope — one shared credential for the whole connection.
**Connected App (JWT Bearer) — `jwt`** (the default)
| Field | Required | Notes |
| :------------- | :------- | :------------------------------------------------------------------------------------------------ |
| `consumer_key` | Yes | The Connected App's Consumer Key (OAuth `client_id`). |
| `private_key` | Yes | RSA private key in PEM form, matching the certificate uploaded to the Connected App. |
| `username` | Yes | The Salesforce username to authenticate as — the JWT subject. Must be pre-authorized for the app. |
**Username / Password — `userpass`** (legacy SOAP login)
| Field | Required | Notes |
| :--------------- | :------- | :---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `username` | Yes | Salesforce username. |
| `password` | Yes | Salesforce password. |
| `security_token` | Yes | The user's security token, appended to the password by the login API. Reset it from **Settings → My Personal Information → Reset My Security Token**. |
***
## NetSuite
Bag of words queries NetSuite with **SuiteQL** over the REST API (`https://.suitetalk.api.netsuite.com/services/rest/query/v1/suiteql`), signing each request with OAuth 1.0a HMAC-SHA256 — NetSuite's Token-Based Authentication (TBA). Results are paged automatically.
### Before you start
In NetSuite **Setup → Company → Enable Features → SuiteCloud**, enable **REST Web Services** and **Token-Based Authentication**.
**Setup → Integration → Manage Integrations → New**. Enable **Token-Based Authentication**. On save, NetSuite shows the **Consumer Key** and **Consumer Secret** once — copy both.
**Setup → Users/Roles → Access Tokens → New**, choosing the integration record, the user, and a role with permission to run SuiteQL against the records you want. NetSuite shows the **Token ID** and **Token Secret** once — copy both.
The consumer secret and token secret are displayed exactly once. If you lose them you must create a new integration record or access token.
### Fields
| Field | Required | Default | Notes |
| :------------- | :------- | :------ | :-------------------------------------------------------------------------------------- |
| `table_filter` | No | — | Comma-separated table names to include in schema discovery. Blank discovers all tables. |
### Authentication
**Token-Based Auth — `token`** (system scope, the only mode)
| Field | Required | Notes |
| :---------------- | :------- | :----------------------------------------------------------------------------------------------------- |
| `account_id` | Yes | NetSuite account id, e.g. `1234567` or `1234567_SB1`. Used for both the REST host and the OAuth realm. |
| `consumer_key` | Yes | From the integration record. |
| `consumer_secret` | Yes | From the integration record. |
| `token_id` | Yes | From the access token. |
| `token_secret` | Yes | From the access token. |
***
## ServiceNow
The ServiceNow connector is in **beta**.
Bag of words queries the ServiceNow **Table API** (`/api/now/table/{table}`). Schema discovery reads ServiceNow's own metadata tables in bulk — `sys_db_object` for tables and inheritance, `sys_dictionary` for fields — so a full snapshot takes a handful of requests rather than one per table. Reference fields become foreign keys.
### Fields
| Field | Required | Default | Notes |
| :--------------- | :------- | :------ | :-------------------------------------------------------------------------------------------------------------------------------------- |
| `instance_url` | Yes | — | Your instance URL, e.g. `https://acme.service-now.com`. |
| `tables` | No | — | Comma-separated tables to expose. Blank uses a curated set of common ITSM tables (incident, change\_request, problem, task, and so on). |
| `discover_all` | No | `false` | Discover all business tables, including custom `u_`/`x_` tables, instead of the curated set. |
| `display_values` | No | `true` | Return human-readable display values for reference and choice fields. |
### Authentication modes
**Username / Password — `userpass`** (scopes: system and user)
| Field | Required | Notes |
| :-------------------- | :------- | :----------------------------------------------------------------------------------------------------------------------------------- |
| `username` | Yes | A ServiceNow user with read access to the target tables. |
| `password` | Yes | That user's password. |
| `oauth_client_id` | No | Client ID of an OAuth app registered in the instance (**System OAuth → Application Registry**). Setting it enables per-user sign-in. |
| `oauth_client_secret` | No | Client secret of that OAuth app. Leave blank if the app is registered as a public client — it then authenticates with PKCE only. |
**Sign in with ServiceNow — `oauth`** (scope: user, no fields). Each user signs in against the instance's own endpoints (`/oauth_auth.do`, `/oauth_token.do`) with the `useraccount` scope, so queries run with that person's own ServiceNow permissions. This requires the `oauth_client_id` above to be configured on the connection.
Per-user authentication on a database-style connection requires an Enterprise license. See [Authentication and access](/data-sources/authentication).
Register the OAuth app's redirect URI in ServiceNow as:
```text theme={null}
https:///api/connections/oauth/callback
```
***
## Monday data
The Monday data connector is in **beta**.
Bag of words queries the monday.com **GraphQL API** and presents each **board as a table**: board columns become schema columns (named by their titles, with status and dropdown labels surfaced to the agent), items become rows, and connect-boards columns become foreign keys to the linked board. Duplicate board names are disambiguated with the board id.
The agent sends a JSON query spec — board, columns, filter rules, ordering, limit — which Bag of words translates into `items_page` calls with cursor pagination. A single query returns at most 10,000 rows. Filters on status and dropdown columns accept the human-readable label (for example `"Done"`); the connector translates it to the label index that monday's API actually matches on. Values come back typed: numbers as floats, checkboxes as booleans, ratings as integers, everything else as display text. Every result also carries three built-in columns — `item_id`, `name` (the item name) and `group` — regardless of which columns the query selects.
This is separate from the **Monday MCP preset**, which exposes monday.com as callable tools (create an item, post an update). Use this connector when you want boards indexed and queryable as data; the two can coexist.
### Fields
| Field | Required | Default | Notes |
| :----------- | :------- | :------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `workspaces` | No | — | Comma-separated workspace names or ids to index. Blank indexes all workspaces the token can see. The account subdomain (`acme` in `acme.monday.com`) is **not** a workspace name — use the workspace names from monday's left sidebar, or leave blank. A wrong value here filters out every board, so discovery reports 0 tables. |
| `boards` | No | — | Comma-separated board names or ids to index. Blank indexes every visible board. |
### Authentication modes
**API Token — `api_token`** (scopes: system and user)
| Field | Required | Notes |
| :-------------------- | :------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `api_token` | Yes | A monday.com API token (avatar → **Developers** → **My access tokens**). Use a dedicated service user's token so shared queries don't depend on one person's account. |
| `oauth_client_id` | No | Client ID of an app created in monday.com's **Developer Center**. Setting it enables per-user sign-in. |
| `oauth_client_secret` | No | Client secret of that app. |
**Sign in with monday.com — `oauth`** (scope: user, no fields). Each user signs in against `auth.monday.com` with read-only scopes (`me:read boards:read workspaces:read users:read account:read`) — enable exactly these on the app in monday's Developer Center, since monday rejects the authorize request if any requested scope is missing. Queries run with that person's own board permissions. This requires the `oauth_client_id` above to be configured on the connection. monday access tokens do not expire and no refresh token is issued.
Per-user authentication on a database-style connection requires an Enterprise license. See [Authentication and access](/data-sources/authentication).
Register the OAuth app's redirect URL in monday.com's Developer Center as:
```text theme={null}
https:///api/connections/oauth/callback
```
Trial and free monday.com accounts have small API rate and daily budgets. Indexing very large accounts or running heavy backfills can exhaust the daily budget, after which the API returns 429 for every request until it resets. The connector absorbs transient throttling automatically.
***
## PostHog
The PostHog connector is in **beta**.
Bag of words queries PostHog with **HogQL** against a fixed catalog that mirrors PostHog's data model — `events`, `persons`, sessions, and related tables — rather than introspecting the instance.
### Fields
| Field | Required | Default | Notes |
| :----------- | :------- | :----------------------- | :--------------------------------------------------------------------------------------------- |
| `host` | No | `https://us.posthog.com` | Instance URL: `https://us.posthog.com`, `https://eu.posthog.com`, or your self-hosted address. |
| `project_id` | Yes | — | PostHog Project ID, found in the project's settings. |
### Authentication
**Personal API Key — `api_key`** (scopes: system and user)
| Field | Required | Notes |
| :-------- | :------- | :-------------------------------------------------------------------------------------------------------------------------- |
| `api_key` | Yes | A PostHog **Personal API Key** with the `query:read` and `project:read` scopes. Create it under your PostHog user settings. |
Because this mode is available at user scope as well as system scope, each user can supply their own personal API key instead of sharing the admin's. Per-user credentials on a database-style connection require an Enterprise license — see [Authentication and access](/data-sources/authentication).
# SQL databases
Source: https://docs.bagofwords.com/data-sources/connectors/databases
Reference for the database and query-engine connectors that need only network access and a login
This is a reference page for the connectors that need no external app registration, tenant setting, or admin consent — just **network access from the Bag of words host** and a **login with read permission**. Add them under **Data Sources → Add data source**, fill in the fields below, test the connection, and pick the tables the agent may use.
Connectors with real external setup have their own pages: [Snowflake](/data-sources/connectors/snowflake), [Google BigQuery](/data-sources/connectors/bigquery), and [Microsoft SQL Server](/data-sources/connectors/sql-server).
Most of these support both a **shared** credential (one login for the whole workspace) and **per-user** credentials (each person authenticates as themselves). Per-user authentication on a database connector requires an Enterprise license — see [Authentication](/data-sources/authentication). Where a mode is shared-only, it is marked below.
## All connectors
| Connector | Config fields | Auth modes | Notes |
| :--------------------------------------------- | :----------------------------------------------------------------------------------------------------------------------------- | :----------------------------------------------------------------------------------------------- | :---------------------------------------------------------------------------------- |
| **PostgreSQL** `postgresql` | `host`, `port` (5432), `database`, `schema` | Username / Password | `schema` is optional and takes a comma-separated list. |
| **MySQL** `mysql` | `host`, `port`, `database` | Username / Password | `user` and `password` may both be blank for anonymous access. |
| **MariaDB** `mariadb` | `host`, `port`, `database` | Username / Password | Same shape as MySQL. |
| **Oracle Database** `oracledb` | `host`, `port` (1521), `service_name`, `schema`, `use_tcps` (false), `verify_ssl` (true) | Username / Password | Connect by **service name**, not SID. |
| **SQLite** `sqlite` | `database` | No auth *(shared only)* | `database` is an absolute path on the Bag of words host. |
| **DuckDB** `duckdb` | `uris` | No auth *(shared)*, AWS Keys *(shared)*, GCP Service Account, Azure Connection String *(shared)* | Queries files in object storage as views. See below. |
| **ClickHouse** `clickhouse` | `host`, `port` (8123), `database`, `secure` (true) | Username / Password | `database` is optional and takes a comma-separated list; blank means all databases. |
| **Trino** `trino` | `host`, `port` (8080), `catalog`, `schema`, `protocol` (`http`) | Username / Password | `catalog` and `schema` are both required. See below. |
| **Vertica** `vertica` | `host`, `port` (5433), `database`, `schema` (`public`) | Username / Password | |
| **Teradata Vantage** `teradata` | `host`, `port` (1025), `database`, `logmech` (`TD2`) | Username / Password | `database` is the namespace (≈ schema) and takes a comma-separated list. See below. |
| **Apache Druid** `druid` beta | `host`, `port` (8082), `secure` (false), `path` (`/druid/v2/sql/`), `schema` | Username / Password, API Token (Bearer), API Token (Basic) | Queried through the Broker or Router SQL API. See below. |
| **Apache Pinot** `pinot` beta | `host`, `port` (8099), `secure` (true), `path` (`/query/sql`), `controller`, `query_options` | Username / Password | Queried through the Broker SQL API. See below. |
| **MongoDB** `mongodb` | `host`, `port` (27017), `database`, `auth_source` (`admin`), `tls` (false), `use_srv` (false) | Username / Password | Document-shaped, not tabular. See below. |
| **Sybase SQL Anywhere** `sybase` EE | `host`, `port` (2638), `database` | Username / Password | Connected over TDS via FreeTDS. |
| **Spark** `spark_connect` | `host`, `port` (15002), `use_ssl` (false), `catalog`, `database`, `require_partition_filter` (false) | No auth *(shared)*, Bearer Token | Spark Connect (`sc://`). See below. |
| **Databricks SQL** `databricks_sql` | `server_hostname`, `http_path`, `catalog`, `schema` | Personal Access Token | `schema` takes a comma-separated list; blank discovers all schemas in the catalog. |
| **Azure Data Explorer** `azure_data_explorer` | `cluster_url`, `database` | Service Principal (AAD App) | Kusto. Auth fields are `client_id`, `client_secret`, `tenant_id`. |
| **AWS Redshift** `aws_redshift` | `host`, `port` (5439), `database`, `schema` (`public`), `region`, `cluster_identifier`, `ssl_mode` (`require`), `timeout` (30) | Username / Password, AWS Keys (IAM), Assume Role (ARN) | See below. |
| **AWS Athena** `aws_athena` beta | `region`, `database`, `workgroup` (`primary`), `s3_output_location`, `data_source` (`AwsDataCatalog`) | AWS Default (IAM Role / Instance Profile), AWS Access Keys | See below. |
beta Beta connector — the shape of the integration may still change.
EE Part of the **Enterprise Edition**.
## Notes on specific connectors
### DuckDB
DuckDB is not a server connection. `uris` holds either the path to a local `.duckdb` file, or **one URI pattern per line** pointing at parquet or CSV files, which Bag of words registers as views and queries in-process. Wildcards are supported:
```text theme={null}
s3://analytics-lake/events/*.parquet
az://container/exports/2024/*/*.csv
/data/reference/dim_customer.parquet
```
Pick the auth mode matching the backing store, not DuckDB itself:
| Mode | Fields | Scope |
| :---------------------- | :---------------------------------------------------- | :----------------- |
| No Auth (public/local) | — | Shared |
| AWS Keys | `access_key`, `secret_key`, `region`, `session_token` | Shared |
| GCP Service Account | `service_account_json` | Shared or per-user |
| Azure Connection String | `connection_string` (SAS or account key) | Shared |
`session_token` is only for temporary AWS credentials. Local paths and `file:/` URIs work with no auth at all.
### Trino
`catalog` and `schema` are both required — a Trino connection is scoped to a single catalog/schema pair, so create one data source per pair you want the agent to reach. Set `protocol` to `https` for a TLS-terminated coordinator; the `password` field is only needed in that case.
### Teradata
`logmech` selects the logon mechanism: `TD2` for native Teradata users, or `LDAP`, `KRB5`, or `TDNEGO` for directory-based logon, which is common on-prem. `host` is the TPA or COP name of the system.
### Apache Druid
Set `secure` to true for HTTPS, and adjust `port` for what you are pointing at — `8082` for a Broker, `8888` for a Router. `schema` defaults to `druid`; system schemas are always excluded from indexing.
Two token modes exist and they are not interchangeable:
* **API Token (Bearer)** sends `Authorization: Bearer `.
* **API Token (Basic)** sends the `basic_token` value verbatim as `Authorization: Basic `, with **no base64 encoding**. Use this one for Imply Polaris `pok_…` API keys.
### Apache Pinot
Points at the Broker SQL endpoint. `controller` is an optional controller base URL (for example `http://controller-host:9000`), used for richer metadata. `query_options` passes a Pinot `queryOptions` string through on every query — `useMultistageEngine=true` is the common one.
### MongoDB
The only document-shaped connector here: the agent sees collections and inferred document structure rather than tables and columns, and writes MongoDB queries rather than SQL.
For **Atlas**, set `use_srv` to true — the connection then uses `mongodb+srv://`, `port` is ignored, `auth_source` is ignored, and TLS is automatic. For a self-hosted deployment, leave `use_srv` off and set `tls` and `auth_source` yourself. `user` and `password` may both be blank for an unauthenticated deployment.
### Spark
Runs Spark SQL against a remote cluster over **Spark Connect** (`sc://`). Compute stays on the cluster — Bag of words sends SQL and receives results, with no in-process engine on the Bag of words server.
Leave `catalog` blank to use the session default, and `database` blank to discover all databases (it also takes a comma-separated list). `require_partition_filter` is a guardrail worth turning on for large lakehouse tables: queries that would scan a partitioned table without filtering on a partition column are rejected via `EXPLAIN` before they run.
The **No auth** mode assumes the Spark Connect endpoint is network-gated — behind a VPN or Tailscale, for example. Otherwise use a Bearer Token.
### AWS Redshift
Three auth modes, all of which still require a `user`:
| Mode | Fields | What it does |
| :------------------ | :--------------------------------- | :------------------------------------------------------------------------------------------------------------------- |
| Username / Password | `user`, `password` | Ordinary Redshift database login. |
| AWS Keys (IAM) | `user`, `access_key`, `secret_key` | Authenticates with IAM credentials rather than a database password. |
| Assume Role (ARN) | `user`, `role_arn` | Assumes the named role and connects with the resulting temporary credentials, refreshed automatically before expiry. |
`region` is needed for both IAM modes. `cluster_identifier` identifies the cluster for IAM-based credential issuance. Leave `ssl_mode` at `require` unless you have a reason not to.
### AWS Athena
Athena is serverless: there is no host or port, only a `region` and a Glue `database`. `data_source` is the Athena catalog name and stays `AwsDataCatalog` for the standard Glue Data Catalog.
`s3_output_location` is where Athena writes query results. Leave it blank **only if** your `workgroup` has a default output location configured; otherwise set it to an S3 URI the identity can write to, since Athena cannot return results without one.
The default auth mode, **AWS Default (IAM Role / Instance Profile)**, takes no fields at all — it uses the ambient AWS credentials of the Bag of words host, which is the right choice when it runs on EC2, ECS, or EKS with an attached role. Otherwise use **AWS Access Keys**, which takes `access_key`, `secret_key`, and `role_arn`.
## Related
* [Data sources overview](/data-sources/overview)
* [Connecting data sources](/data-sources/connecting)
* [Authentication](/data-sources/authentication)
# CSV and QVD
Source: https://docs.bagofwords.com/data-sources/connectors/file-formats
Turn CSV and Qlik QVD files on the backend host into SQL tables the agent can query
The **CSV** and **QVD** connectors expose data files as **SQL tables**. You point each connection at file paths or glob patterns, and every matching file becomes one table the agent can query with SQL, join, and aggregate.
Use these when the file *is* a dataset. If you want the agent to search and read documents — PDFs, Word files, mixed folders — use [Files and Directories](/data-sources/connectors/files-and-directories) instead, which exposes files as a searchable catalog rather than as tables.
## How it works
Both connectors run on **DuckDB** inside Bag of words. Paths are resolved on the **backend host**, exactly like the Files and Directories connector, so a local folder or an already-mounted SMB/NFS share both work. There are no credential fields — access is whatever the operating system grants the backend process.
* **CSV** is read natively by DuckDB. There is no conversion or cache: each resolved file is exposed directly as a table at connect time. One file, one table.
* **QVD** is a proprietary binary format, so each file is converted to a columnar cache on the backend the first time it is indexed, then queried with SQL from there.
Glob patterns are expanded at connect time, so adding a file that matches an existing pattern makes it available on the next index without editing the connection.
## Before you start
* The files exist on the **Bag of words backend host** and are readable by the process that runs it.
* For a network share, mount it with the OS first. If Bag of words runs in a container, the mount must be visible inside the container.
* Give each file a stable, meaningful filename — the filename becomes the table name the agent sees.
***
## CSV
Go to **Data Sources → Add data source → CSV**.
| Field | Required | Default | Notes |
| :----------- | :------- | :-------- | :-------------------------------------------------------------------------------------------------- |
| `file_paths` | Yes | — | CSV file paths or glob patterns, one per line, e.g. `/data/*.csv` or `/mnt/exports/sales_2025.csv`. |
| `delimiter` | No | *(blank)* | Column delimiter. Leave blank to auto-detect. Examples: `,` `;` `|`, or `\t` for tab. |
| `has_header` | No | `true` | Whether the first row contains column names. Turn off for headerless files. |
| `encoding` | No | `utf-8` | File encoding, e.g. `utf-8`, `latin-1`. |
The settings apply to **every** file in the connection. If some of your CSVs are semicolon-delimited and others comma-delimited, or they use different encodings, create a separate connection per group.
### Authentication
A single mode, **No Authentication** (`none`), at system scope. Nothing to enter.
***
## QVD
The QVD connector is part of the **Enterprise Edition**.
Go to **Data Sources → Add data source → Qlik (QVD)**.
| Field | Required | Default | Notes |
| :----------- | :------- | :------ | :----------------------------------------------------------------- |
| `file_paths` | Yes | — | QVD file paths or glob patterns, one per line, e.g. `/data/*.qvd`. |
QVD files carry their own field names and types, so there is nothing to configure beyond the paths.
Indexing a large QVD set takes longer than CSV, because each file is converted before it can be queried. The conversion is cached, so subsequent indexing only touches files that changed.
### Authentication
A single mode, **No Authentication** (`none`), at system scope. Nothing to enter.
***
## Troubleshooting
The glob matched nothing. Check that the path is absolute and correct **from the backend host's point of view** — a path that works on your laptop is not necessarily the path inside the container.
Auto-detection picked the wrong delimiter. Set `delimiter` explicitly on the connection.
The file has no header row but `has_header` is on, or vice versa. Toggle `has_header`.
Set `encoding` to match the file — `latin-1` is the usual fix for exports from older Windows tools.
## Related
* [Files and Directories](/data-sources/connectors/files-and-directories) — the same paths, exposed as a searchable document catalog instead of tables.
* [Amazon S3](/data-sources/connectors/s3) — data files in object storage.
# Files and Directories
Source: https://docs.bagofwords.com/data-sources/connectors/files-and-directories
Expose a local folder or a mounted network share (SMB/NFS) to the agent as a searchable file catalog
The **Files and Directories** connector points Bag of words at a directory on the backend host — a local folder, or an SMB/NFS share the operating system has already mounted. The agent lists the directory, searches filenames and file contents, reads files, and (optionally) writes new ones. It reads inside PDF, Word, PowerPoint, Excel and CSV, so a question can be answered from documents, not just tables.
## How it works
Bag of words treats the directory as a **file catalog**, not a database. The agent gets filesystem primitives:
| Tool | Filesystem equivalent |
| :------------- | :----------------------------------------------------------------- |
| `list_files` | `ls` / `find` |
| `search_files` | `grep -ril` — matches filenames and, for readable formats, content |
| `grep_files` | `grep -n` — matching lines with context |
| `read_file` | `cat`, with tabular files parsed into DataFrames |
| `write_file` | `cp` / `put` — only when the connection is **writable** |
Everything is confined to `root_path`. A file id is its POSIX path relative to the root, and any id that escapes the root — `..`, an absolute path, a symlink pointing outside — is rejected. If you set `include_globs`, files outside those patterns are not merely hidden from listings: reading them is **denied**.
`.csv`, `.tsv`, `.xlsx` and `.xls` are parsed into tables. `.pdf`, `.docx` and `.pptx` have their text extracted. Plain-text formats (`.txt`, `.md`, `.json`, `.html`, `.log`, `.yaml`, `.xml`, `.py`, `.sql`) are read as text. Anything else is matched by name only.
## Before you start
* The directory must exist **on the Bag of words backend host** and be readable by the process that runs it. Bag of words does not mount anything itself.
* For a network share, mount it with the OS first (`/etc/fstab`, `mount -t cifs`, `mount -t nfs`, an autofs map, or a container volume). There are **no credential fields** on this connector — the share's authentication is handled entirely by the mount.
* If Bag of words runs in a container, the mount must be visible **inside** the container (bind-mount or volume), not just on the host.
* For a writable connection, the backend process needs write permission on the mount.
If the share is mounted read-only at the OS level, leave `writable` off. Turning it on does not grant write access — writes will fail at the filesystem.
## Connect in Bag of words
Go to **Data Sources → Add data source → Files and Directories** and fill in the form.
| Field | Required | Default | Notes |
| :-------------------- | :------- | :-------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `root_path` | Yes | — | Absolute path to the directory, e.g. `/mnt/contracts`. All reads, searches and writes are confined here. |
| `include_globs` | No | — | Comma- or newline-separated glob patterns relative to the root, e.g. `reports/**/*.csv`, `**/*.pdf`, `files/**`. When set, only matching files are visible **and** readable. `**` crosses subfolders, `*` matches one segment. |
| `recursive` | No | `true` | Walk subfolders when listing and searching. |
| `writable` | No | `false` | Allow the agent to create or overwrite files (the `write_file` tool). Leave off for a read-only connection. |
| `max_file_mb` | No | `100` | Skip files larger than this when reading, so a huge file cannot be loaded into memory. |
| `index_mode` | No | `content` | How much is cached from the directory — see below. |
| `max_catalog_objects` | No | `10000` | Hard cap on how many files are ever enumerated. A larger tree is truncated; narrow `include_globs` instead of raising this. |
`allowed_extensions` and `index_content` are **deprecated**. They still work on existing connections, but use `include_globs` with a pattern like `**/*.pdf` instead of `allowed_extensions`, and `index_mode` instead of `index_content`.
### Indexing modes
`index_mode` controls how much Bag of words caches. Reads are always live regardless of the mode.
| Mode | What is cached | Use when |
| :--------- | :----------------------------------------------------------------------------------- | :-------------------------------------------------------------------------- |
| `none` | Nothing. The agent lists and reads live every time. | The directory is huge or changes constantly and you want maximum freshness. |
| `metadata` | The file list (name, size, modified time). No content. | You want fast listing but do not need topic search across file contents. |
| `content` | The file list **plus** keywords extracted from PDF, Word, PowerPoint, Excel and CSV. | The default. Lets the agent find files by topic, not just by name. |
## Authentication
This connector has a single mode, **No Authentication** (`none`), scoped to the system. Access is whatever the backend host's OS grants on the mount — there is nothing to enter in Bag of words. To give different teams different slices of a share, create several connections with different `root_path` or `include_globs` values and set access rules per connection. See [Authentication and access](/data-sources/authentication).
## Troubleshooting
Check `include_globs`. Patterns are matched **relative to `root_path`**, so `/mnt/contracts/reports/*.pdf` will never match — write `reports/*.pdf`. Also confirm `recursive` is on if the files live in subfolders.
The tree exceeded `max_catalog_objects` and was truncated. Narrow the connection with `include_globs` or a deeper `root_path` rather than raising the cap.
Either it is larger than `max_file_mb`, or it is outside `include_globs` (in which case access is denied by design), or the backend process lacks read permission on it.
`writable` only removes the product-side block. The mount and the backend process's OS permissions must also allow writing.
## Related
* [Amazon S3](/data-sources/connectors/s3) — the same file catalog, over object storage.
* [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) — document libraries over Microsoft Graph.
* [CSV and QVD](/data-sources/connectors/file-formats) — when you want files exposed as SQL **tables** instead of documents.
# Google Drive
Source: https://docs.bagofwords.com/data-sources/connectors/google-drive
Let each user connect their own Google Drive so the agent can read their Sheets, Excel, CSV and documents
The **Google Drive** connector gives the agent read access to a user's Drive — Google Sheets, Excel, CSV and documents all become available to search and read. Every user connects their own Google account, and the agent works against that account's files.
The Google Drive connector is part of the **Enterprise Edition**.
## How it works
This is a **per-user** connection: `catalog_ownership` is `per_user`, so there is no shared, admin-curated catalog. Each user's own Drive *is* their catalog, and no two users' catalogs overlap unless their Drives do. That is why the connector has **no config fields** — there is nothing for an admin to scope. The admin's only job is registering the OAuth client; the users do the rest by signing in.
Once a user has connected, Bag of words reads their Drive with the Drive API (`https://www.googleapis.com/drive/v3`) and Google-native spreadsheets with the Sheets API (`https://sheets.googleapis.com/v4`). `.csv`, `.tsv`, `.xlsx` and `.xls` are parsed into tables; `.pdf`, `.docx` and `.pptx` are text-extracted. Access is read-only — the connector requests read-only scopes and cannot modify Drive.
See [User context and per-user data](/data-sources/user-context) for how per-user connections behave in a conversation.
## Before you start
* A **Google Cloud project** you can administer.
* The **Google Drive API** and **Google Sheets API** enabled in that project.
* Permission to configure the project's **OAuth consent screen**.
* Your Bag of words base URL, for the redirect URI.
## Step 1 — Create a Google OAuth client
In the [Google Cloud console](https://console.cloud.google.com) → **APIs & Services** → **OAuth consent screen**. For a Google Workspace organization, choose **Internal** so only your own users can consent.
Under **APIs & Services** → **Library**, enable the **Google Drive API** and the **Google Sheets API**.
**APIs & Services** → **Credentials** → **Create credentials** → **OAuth client ID**. Choose application type **Web application**.
It must be a **Web application** client. Desktop, Android/iOS, and service-account credentials do not work with the authorization-code flow Bag of words uses.
Under **Authorized redirect URIs**, add:
```text theme={null}
https:///api/connections/oauth/callback
```
Replace `` with your Bag of words base URL.
Copy the **Client ID** and **Client secret** — these go into Bag of words.
### Scopes requested at sign-in
```text theme={null}
openid email profile
https://www.googleapis.com/auth/drive.readonly
https://www.googleapis.com/auth/spreadsheets.readonly
```
If your consent screen lists scopes explicitly, add these. Both Drive scopes are read-only.
## Connect in Bag of words
Go to **Data Sources → Add data source → Google Drive**. There are **no config fields** — you only supply the OAuth client.
## Authentication modes
### Google OAuth Client — `oauth_app`
Scopes: **system** and **user**. This is the admin-side registration of the Google Cloud OAuth client.
| Field | Required | Default | Notes |
| :-------------------- | :------- | :------ | :---------------------------------------------------------------------------------------------------------------------------------------------- |
| `oauth_client_id` | Yes | — | Google Cloud OAuth 2.0 Client ID, **Web application** type. |
| `oauth_client_secret` | Yes | — | The matching client secret. |
| `workspace_domain` | No | — | Google Workspace domain to restrict sign-in to, e.g. `company.com`. Sets the `hd` hint on the authorize URL so users land on the right account. |
### Sign in with Google — `oauth`
Scope: **user** only, no fields. Each user clicks **Connect**, consents in Google, and the resulting token is what the connector uses for that person. Nothing is shared between users.
See [Authentication and access](/data-sources/authentication).
## Alternative: the Google Drive MCP preset
Bag of words also ships a **Google Drive (MCP Preview)** preset that reaches Drive through Google's preview MCP server (`https://drivemcp.googleapis.com/mcp/v1`) rather than this native connector. It also needs a Google OAuth client, and it gives the agent Google's own Drive tools instead of the Bag of words file catalog. Add it from **Data Sources → Add data source → MCP** and pick the Google Drive preset. See [MCP servers](/data-sources/mcp).
Use the native connector when you want Drive files in the standard file catalog with Bag of words parsing and search; use the MCP preset when you specifically want Google's tool surface.
## Troubleshooting
The **Authorized redirect URIs** list on the OAuth client must contain `https:///api/connections/oauth/callback` exactly, matching your Bag of words base URL.
The connection is missing `oauth_client_id` / `oauth_client_secret`. Both must be set on the connection before any user can sign in.
Set `workspace_domain` to your Workspace domain so the authorize URL carries the `hd` hint.
The **Google Sheets API** is not enabled in the Cloud project, or the `spreadsheets.readonly` scope was not consented. Native Google spreadsheets are read via the Sheets API, not the Drive API.
## Related
* [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) — the Microsoft equivalent.
* [Gmail and Outlook Mail](/data-sources/connectors/mail) — Gmail uses the same kind of Google OAuth client.
# Infor OLAP
Source: https://docs.bagofwords.com/data-sources/connectors/infor-olap
Connect Infor d/EPM OLAP cubes over the XMLA Provider and query them with MDX
Bag of words connects to the **Infor d/EPM OLAP XMLA Provider** — the supported entry point for on-premise Infor OLAP / Infor BI (25.x), since native connections were removed — discovers the cubes in each OLAP database, and runs **MDX** against them.
The Infor OLAP connector is part of the **Enterprise Edition**.
## How it works
XMLA is a SOAP-over-HTTP protocol. Bag of words posts to the endpoint you configure and:
1. Lists catalogs (OLAP databases) with a `DBSCHEMA_CATALOGS` Discover.
2. Lists cubes per catalog (`MDSCHEMA_CUBES`), then their hierarchies (`MDSCHEMA_HIERARCHIES`) and measures (`MDSCHEMA_MEASURES`).
3. Executes MDX at query time (XMLA `Execute`, `Format=Tabular`).
Each cube becomes a schema table named `Catalog/Cube` (for example `Finance/GL`), whose columns are dimension hierarchies (`dtype="dimension"`) and measures (`dtype="measure"`). The MDX unique name for every column is carried in `metadata.unique_name`.
**Two things are specific to Infor and worth understanding before you configure anything:**
**The application identity travels inside the XMLA request.** Infor database workers authenticate from `UserName`, `Password`, and `Tenant` properties in each request's XMLA `PropertyList` — not from HTTP Basic. Bag of words sends both: HTTP Basic reaches the endpoint, and the XMLA properties establish the Infor application identity. Sending Basic alone reaches the worker but leaves the username empty, which the worker rejects.
**Farms route through a manager.** Infor's documented connection flow is to send `DISCOVER_DATASOURCES` to the **OLAP Service Manager** at `http(s)://:/BI/APP/SOAP/OLAPDB`. The response lists each database with the URL of the **Database Worker** that serves it, and all subsequent traffic goes to that worker URL. Enable **Manager discovery** to have Bag of words perform this bootstrap on connect.
## Before you start
* Decide which endpoint you have: a **Database Worker** XMLA URL (point at it directly) or the **OLAP Service Manager** URL (enable manager discovery). Worker endpoint paths are farm-specific; the manager endpoint is the documented, stable entry point.
* The Bag of words backend host must reach that URL. The connector posts to the exact URL configured — no path discovery, no redirect handling.
* An Infor EPM user with read access to the OLAP database.
* Know your **Tenant** value (`single` on single-tenant farms) and whether the datasource is advertised as **Secured** — manager discovery matches on both.
* For **ION API Gateway** routing, a backend-service `.ionapi` credentials file for an authorized application. You will need its `pu` + `ot` (token URL), `ci` (client ID), and `cs` (client secret) values.
Farm-side verification of the registered listeners is `netsh http show servicestate view=requestq` on the OLAP application server. A live XMLA endpoint answers `GET` with **405** (it is POST-only); Windows HTTP.sys answers an unregistered path with a **404** carrying `Server: Microsoft-HTTPAPI/2.0` — that combination means right machine, wrong path.
## Step 1 — Choose the endpoint
Set **Endpoint URL** to the Database Worker's XMLA URL and leave **Manager discovery** off. Use this when you already know the worker URL and it is reachable from the backend.
Set **Endpoint URL** to the OLAP Service Manager:
```text theme={null}
http(s)://:/BI/APP/SOAP/OLAPDB
```
Turn **Manager discovery** on. On connect, Bag of words sends `DISCOVER_DATASOURCES` (carrying `Tenant`, the `Secured` value, and — if you set **Catalog** — a `Databasename` restriction), picks the matching database, and switches to its worker URL. **Test Connection** reports the resolved worker URL so you can confirm what it picked.
If the manager hosts more than one database, you must set **Catalog**; otherwise the connection fails with the list of available database names.
## Step 2 — Handle worker host rewriting
Farms advertise **internal** machine names in the worker URLs they return, and those names rarely resolve from outside the farm. **Rewrite worker host** is on by default: the hostname in the discovered worker URL is replaced with the host from the endpoint URL you configured (the worker is reached at the same address the manager was), keeping the discovered path and port.
Turn it off only when workers genuinely run on different machines whose hostnames the backend can resolve.
## Step 3 — (Optional) Route through ION API Gateway
When the OLAP farm is fronted by ION API Gateway or another reverse proxy, the worker paths returned by manager discovery have to be mapped onto the external route.
Put the API-suite route that sits in front of `/BI/APP/SOAP/OLAPDB` into **Worker URL base**. It must be an absolute URL. The path returned by discovery is appended to it, and the scheme and host of that base win — which is what makes an HTTPS gateway route survive in front of an HTTP OLAP farm.
Choose the **ION API Gateway** authentication mode and fill it from the backend-service `.ionapi` file: `pu` + `ot` form the token URL, `ci` is the client ID, `cs` is the client secret. Bag of words performs an OAuth **client-credentials** grant, caches the token until shortly before it expires, sends it as a bearer token on every XMLA call, and retries once with a fresh token if the gateway answers HTTP 401.
The gateway credentials authenticate the *route*, not the OLAP user. The Infor username and password are still required and still travel in the XMLA `PropertyList` on every worker request.
Set **Secured** to match the value `DISCOVER_DATASOURCES` advertises for the datasource. It describes the Infor datasource itself — not the transport — so it stays as the farm reports it even when an HTTPS gateway fronts an HTTP OLAP farm.
## Connect in Bag of words
Go to **Data Sources → Add data source → Infor OLAP** and fill in the form.
| Field | Required | Default | Notes |
| :-------------------- | :------- | :-------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `host` | Yes | — | A Database Worker XMLA URL, or — with manager discovery on — the OLAP Service Manager endpoint `http(s)://:/BI/APP/SOAP/OLAPDB`. |
| `catalog` | No | *(empty)* | OLAP catalog/database to scope discovery to. Leave blank to list all accessible catalogs. Required when the manager hosts more than one database. |
| `manager_discovery` | No | `false` | Treat the URL as the OLAP Service Manager and resolve the database's worker URL via `DISCOVER_DATASOURCES`. Leave off when the URL already points at a worker. |
| `rewrite_worker_host` | No | `true` | Replace the hostname in discovered worker URLs with the host from the endpoint URL. Disable only when workers run on other machines with resolvable hostnames. |
| `worker_url_base` | No | *(empty)* | External base URL for mapping worker paths through ION API Gateway or a reverse proxy. Specify the API-suite route that precedes `/BI/APP/SOAP/OLAPDB`. Must be absolute. |
| `tenant` | No | `single` | XMLA `Tenant` property sent during manager discovery and on every worker request. |
| `secured` | No | `false` | Match the `Secured` value advertised by `DISCOVER_DATASOURCES`. |
| `verify_ssl` | No | `true` | Verify the TLS certificate when calling the XMLA endpoint. |
| `timeout_sec` | No | `60` | HTTP timeout for XMLA calls, in seconds. |
**Test Connection** authenticates, lists catalogs, and — when a catalog is configured — also lists that catalog's cubes on the resolved worker, so a manager-only success cannot mask an unreachable worker. When manager discovery resolved a worker, the message includes the worker URL it will use.
## Authentication modes
| Mode | Scope | Fields |
| :---------------------- | :------------------ | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Username / Password** | System and per-user | `username`, `password` — the Infor OLAP user. Sent in the XMLA worker `PropertyList`; direct connections also use HTTP Basic. |
| **ION API Gateway** | System only | `username`, `password` (as above) plus `gateway_token_url` (from `pu` + `ot`), `gateway_client_id` (`ci`), `gateway_client_secret` (`cs`), and optional `gateway_scope` (space-separated OAuth scopes assigned to the authorized application). |
**Username / Password** can be shared (one admin-supplied EPM account for everyone) or per-user, where each person supplies their own Infor credentials so the OLAP server applies their own access.
**ION API Gateway** is system-scope only — the gateway client is a shared backend-service identity, so this mode always runs on one shared credential.
Per-user authentication on database-style connectors requires an Enterprise license. See [Authentication](/data-sources/authentication).
## Troubleshooting
The host answered but nothing serves XMLA there. If the 404 carries `Server: Microsoft-HTTPAPI/2.0`, the message adds the documented hint: point the URL at the OLAP Service Manager (`http(s)://:/BI/APP/SOAP/OLAPDB`) and enable manager auto-discovery. Worker paths are farm-specific — verify the registered listeners on the OLAP app server.
Manager discovery returned more than one database and cannot choose. Set **Catalog** to one of the names listed in the error.
The **Catalog** value does not match any database the manager advertises. The error lists the available names; database names are matched case-sensitively first, then case-insensitively.
`DISCOVER_DATASOURCES` came back empty. Check **Tenant**, **Catalog**, **Secured**, and that the user has access to the application — all four restrict the response.
An empty application username means the worker got the request without the XMLA identity properties. Error `1042` means the worker parsed the identity and rejected the credential — check the Infor EPM username and password, not the transport.
The farm advertised an internal machine name. Keep **Rewrite worker host** on so the configured host is substituted back in, or set **Worker URL base** when the worker is reached through a gateway.
**Worker URL base** needs both a scheme and a host, for example `https://gateway.example.com/MYTENANT/EPM_OLAP`. A bare path is rejected.
The client-credentials grant against `gateway_token_url` was refused. Re-copy `pu` + `ot`, `ci`, and `cs` from the backend-service `.ionapi` file, and add `gateway_scope` if the authorized application requires scopes.
Reported as *"No OLAP databases visible to this user — check application access."* The endpoint and credentials are fine; the EPM user has no access to any OLAP database.
# Gmail and Outlook Mail
Source: https://docs.bagofwords.com/data-sources/connectors/mail
Let the agent search and read a user's own mailbox as a data source
The **Gmail** and **Outlook Mail** connectors let the agent search and read messages in a user's own mailbox. Each user connects their own account; the agent then answers questions from what is in that inbox — a contract sent last quarter, the thread where a number was agreed, the vendor's latest invoice.
Both connectors are part of the **Enterprise Edition**.
These connectors are **not** the [Email channel](/channels/email). The Email channel gives the Bag of words analyst *its own* mailbox so it can send answers and receive questions — one shared address, configured once by an admin. These connectors do the opposite: they let the agent read *your* mailbox as data. The two are configured separately and can be used together or independently.
## How it works
Both connectors are **per-user** (`catalog_ownership: per_user`) and **read-only**. There is no shared catalog and no admin-side message list — a mailbox is searched and read live, per user, at question time. That is why neither connector has any config fields.
The agent gets mail-shaped tools rather than file tools:
| Tool | What it does |
| :------------- | :-------------------------------------------------------------------------------------------------------------- |
| `list_emails` | The most recent messages — subject, sender, received time. |
| `search_email` | A keyword search across the mailbox. |
| `read_email` | One message rendered as plain text: subject, from, to, date, then the body (HTML bodies are converted to text). |
| | Gmail | Outlook Mail |
| :--------------- | :----------------------------------------------------- | :------------------------------------------------------------------- |
| API | Gmail API v1 (`https://gmail.googleapis.com/gmail/v1`) | Microsoft Graph (`https://graph.microsoft.com/v1.0`, `/me/messages`) |
| Admin credential | Google Cloud OAuth client (`oauth_app`) | Entra ID app registration (`service_principal`) |
| Per-user sign-in | Sign in with Google (`oauth`) | Sign in with Microsoft (`oauth`) |
| Config fields | None | None |
Only reading and searching are supported. Neither connector can send, draft, label, or delete mail.
See [User context and per-user data](/data-sources/user-context) for how per-user connections behave in a conversation.
## Gmail
### Before you start
* A **Google Cloud project** you can administer, with the **Gmail API** enabled.
* Access to the project's **OAuth consent screen** (choose **Internal** for a Workspace organization).
* Your Bag of words base URL, for the redirect URI.
### Step 1 — Create a Google OAuth client
Google Cloud console → **APIs & Services** → **Library** → enable the **Gmail API**.
**APIs & Services** → **Credentials** → **Create credentials** → **OAuth client ID**, application type **Web application**.
Under **Authorized redirect URIs**:
```text theme={null}
https:///api/connections/oauth/callback
```
Scopes requested at sign-in:
```text theme={null}
openid email profile https://www.googleapis.com/auth/gmail.readonly
```
### Authentication modes
**Google OAuth Client — `oauth_app`** (scopes: system and user)
| Field | Required | Notes |
| :-------------------- | :------- | :----------------------------------------------------------------------------------------------------------- |
| `oauth_client_id` | Yes | Google Cloud OAuth 2.0 Client ID, **Web application** type. |
| `oauth_client_secret` | Yes | The matching client secret. |
| `workspace_domain` | No | Google Workspace domain to restrict sign-in to, e.g. `company.com`. Sets the `hd` hint on the authorize URL. |
**Sign in with Google — `oauth`** (scope: user, no fields). Each user clicks **Connect** and consents; the agent reads only that user's mailbox.
## Outlook Mail
### Before you start
* A **Microsoft Entra ID app registration** with a client secret.
* An administrator who can **grant admin consent** for the Graph permissions.
* Your Bag of words base URL, for the redirect URI.
### Step 1 — Register an Entra ID application
Azure Portal → **Microsoft Entra ID** → **App registrations** → **New registration**. Copy the **Directory (tenant) ID** and **Application (client) ID** from the Overview page.
**Certificates & secrets** → **New client secret**. Copy the value immediately.
**API permissions** → **Microsoft Graph** → delegated **`Mail.Read`**, **`User.Read`**, **`openid`**, **`profile`**, **`offline_access`**. Then click **Grant admin consent**.
**Authentication** → **Add a platform** → **Web**:
```text theme={null}
https:///api/connections/oauth/callback
```
If you already registered an app for [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive), you can reuse it — just add the `Mail.Read` delegated permission and grant consent again.
### Authentication modes
**Entra ID App (Service Principal) — `service_principal`** (scopes: system and user)
| Field | Required | Notes |
| :-------------------- | :------- | :--------------------------------------------------------------------------------- |
| `tenant_id` | Yes | Directory (tenant) ID. |
| `client_id` | Yes | Application (client) ID of the app registration. |
| `client_secret` | Yes | The client secret value. |
| `oauth_client_id` | No | A separate app registration client ID for user sign-in. Falls back to `client_id`. |
| `oauth_client_secret` | No | Secret for that separate app. Falls back to `client_secret`. |
**Sign in with Microsoft — `oauth`** (scope: user, no fields). Each user completes the Microsoft authorization-code flow; Graph then serves `/me/messages` for that user only.
See [Authentication and access](/data-sources/authentication).
## Connect in Bag of words
Go to **Data Sources → Add data source** and choose **Gmail** or **Outlook Mail**. Enter the admin credential above and save — there is nothing else to configure. Each user then clicks **Connect** on the connection to sign in with their own account before the agent can search their mail.
## Troubleshooting
The user has not completed **Connect**. These connectors have no shared credential to fall back on — a mailbox is only reachable after its owner signs in.
Both providers must have `https:///api/connections/oauth/callback` registered exactly, matching your Bag of words base URL.
`Mail.Read` was not granted or not admin-consented. Check **API permissions** on the app registration.
`offline_access` (Microsoft) is missing from the granted permissions, so no refresh token is issued.
## Related
* [Email channel](/channels/email) — give the analyst its own mailbox to send and receive answers. A different feature from these connectors.
* [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) — same Entra app registration.
* [OneNote](/data-sources/connectors/onenote) — read Microsoft OneNote notebooks with the same Entra app.
* [Google Drive](/data-sources/connectors/google-drive) — same kind of Google OAuth client.
# Microsoft Fabric
Source: https://docs.bagofwords.com/data-sources/connectors/microsoft-fabric
Connect Microsoft Fabric Warehouse and Lakehouse SQL endpoints and query them with T-SQL
Bag of words connects to **Microsoft Fabric** Warehouse and Lakehouse **SQL endpoints** with Microsoft Entra ID (Azure AD) authentication, discovers the tables the connecting identity may read, and queries them with **T-SQL**. A shared service principal and per-user sign-in are both supported.
## How it works
The Fabric SQL endpoint is a SQL Server-compatible endpoint. Bag of words acquires an Entra access token, then connects with the **Microsoft ODBC Driver 18 for SQL Server** using that token (`Encrypt=yes`, `TrustServerCertificate=no`).
* **Service principal** — a client-credentials token for `https://database.windows.net/.default`.
* **Per-user** — a delegated token for `https://database.windows.net/user_impersonation offline_access`, obtained by user sign-in or by an on-behalf-of exchange from the user's Entra login.
The SQL endpoint authenticates with **Azure SQL** tokens, not Fabric API tokens. An app registration granted only Fabric/Power BI API permissions yields tokens the SQL endpoint rejects with login error `18456`. The permission that matters is **Azure SQL Database → user\_impersonation** (delegated), with admin consent.
Discovery reads `INFORMATION_SCHEMA.COLUMNS` for the configured database, skips the `sys`, `INFORMATION_SCHEMA`, and `queryinsights` schemas, and — importantly — filters to objects the connecting principal actually has `SELECT` on (`HAS_PERMS_BY_NAME`). `INFORMATION_SCHEMA` alone lists objects whose *existence* is visible, which is broader than read access, so without this filter a principal with `DENY SELECT` would still see tables listed. Table and column descriptions come from `MS_Description` extended properties when readable; otherwise a simpler introspection runs.
Each object is exposed to the agent as `schema.table`.
Fabric SQL endpoints are serverless and can be slow to answer the first connection after the capacity has been idle. Bag of words allows a 60-second login timeout and retries transient connection failures up to three times, so a cold start surfaces as a slow first query rather than an error.
## Before you start
* A Fabric Warehouse or Lakehouse, and its **SQL endpoint** hostname (for example `abc123.datawarehouse.fabric.microsoft.com`) — copy it from the item's settings in Fabric.
* Permission to create an app registration in Microsoft Entra ID, and an administrator who can grant admin consent.
* The identity you connect with needs access to the workspace and read access to the warehouse or lakehouse. Discovery only lists objects it holds `SELECT` on, so missing grants show up as missing tables rather than as an error.
* The Microsoft ODBC Driver 18 for SQL Server must be present on the backend host. The official Bag of words container image already includes it.
## Step 1 — Register an Entra ID application
In the [Azure Portal](https://portal.azure.com) → **Microsoft Entra ID** → **App registrations** → **New registration**.
Name it (for example `Bag of words - Fabric`). Under **Supported account types**, choose **Accounts in this organizational directory only** unless you specifically need multi-tenant.
From the app's **Overview** page, copy the **Directory (tenant) ID** and the **Application (client) ID**.
**Certificates & secrets → New client secret**. Copy the secret **value** immediately — it is shown only once.
**API permissions → Add a permission → APIs my organization uses → Azure SQL Database**, then add the delegated **user\_impersonation** permission and **grant admin consent** for the directory. This is what makes the issued token acceptable to the Fabric SQL endpoint.
Under **Authentication**, add a **Web** redirect URI:
```text theme={null}
https:///api/connections/oauth/callback
```
Keep **offline\_access** among the delegated scopes so the token can be refreshed without asking the user to sign in again.
## Step 2 — Grant the identity access in Fabric
Add the service principal (or the security group containing it) to the Fabric **workspace**, and grant it read access to the warehouse or lakehouse you want to query. Do the same for the user accounts that will sign in per-user.
A connection that tests successfully but discovers zero tables is almost always a permissions gap, not a configuration error: the identity can log in to the endpoint but holds `SELECT` on nothing.
## Connect in Bag of words
Go to **Data Sources → Add data source → Microsoft Fabric** and fill in the form.
| Field | Required | Default | Notes |
| :---------------- | :------- | :-------- | :-------------------------------------------------------------------------------------- |
| `server_hostname` | Yes | — | The Fabric SQL endpoint, e.g. `abc123.datawarehouse.fabric.microsoft.com`. |
| `database` | Yes | — | The Warehouse or Lakehouse name. |
| `schema` | No | *(empty)* | A schema, or a comma-separated list. Empty discovers all schemas the identity can read. |
**Test Connection** acquires a token, opens the ODBC connection, and runs `SELECT 1`.
## Authentication modes
One shared application identity discovers and queries Fabric for everyone. Simplest to operate; every user sees the same tables. System scope.
Each user signs in with their own Microsoft account. Discovery and queries run with that user's own permissions on the warehouse. Per-user scope.
| Mode | Scope | Fields |
| :------------------------------- | :------------ | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Service Principal (Azure AD)** | System only | `tenant_id` — Directory (tenant) ID; `client_id` — app registration Client ID; `client_secret` — app registration secret; optional `oauth_client_id` / `oauth_client_secret` — a separate app registration used for **user sign-in**, falling back to the Client ID/Secret above when blank. |
| **Sign in with Microsoft** | Per-user only | None — each user authorizes through the sign-in flow and their delegated token is stored for them. |
Per-user authentication on database-style connectors requires an Enterprise license. See [Authentication](/data-sources/authentication).
To force everyone to use their own account instead of the shared service principal, enable **Require user authentication** on the data source. Each user then clicks **Connect** and signs in before they can query.
## Querying
Fabric uses **T-SQL**, and the agent writes it accordingly: `SELECT TOP n` rather than `LIMIT`, `+` for string concatenation, `GETDATE()`, `ISNULL()`/`COALESCE()`, `DATEPART()`/`DATEADD()`/`DATEDIFF()`, and square brackets around reserved words. Tables are addressed as `schema.table`.
## Personalized dashboards over Fabric permissions
With **per-user** authentication, a dashboard built on Fabric can be shared so each viewer's queries run under **their own** token. The warehouse's own `GRANT`/`DENY SELECT` then applies per person — a viewer without access to a table sees nothing from it, while others see their permitted rows, all from one shared dashboard. Configure this with **Viewer** run identity when sharing; see [personalizing a dashboard](/using-bow/dashboards#personalize-a-dashboard-per-viewer). As with any delegated source, **View-as** previews the target's parameter binding but keeps your token — to confirm exactly what another person can read, have them open the shared dashboard themselves.
## Troubleshooting
The token has the wrong audience. Add the **Azure SQL Database → user\_impersonation** delegated permission to the app registration and grant admin consent; a Fabric/Power BI API scope produces tokens the SQL endpoint rejects.
A cold-starting serverless endpoint. Bag of words already retries with a 60-second login timeout; if it persists across retries, the endpoint or the capacity is unavailable rather than idle.
Discovery lists only objects the identity has `SELECT` on. Grant the service principal (or user) access to the workspace and read access on the warehouse/lakehouse, and check the `schema` field is not excluding them.
On a connection that runs queries with each user's own credentials, the creating admin has no delegated token yet, so the table list is empty and **Reload tables** cannot help. Click **Connect** on the data source and sign in with Microsoft; the tables appear once the token is stored. The same applies to any member opening the tables view before connecting.
Table and column comments come from `MS_Description` extended properties. When that enriched query fails — commonly on a low-privilege principal — discovery falls back to names and data types only.
## Reference
* **Service principal token scope**: `https://database.windows.net/.default`
* **Per-user (delegated) scope**: `https://database.windows.net/user_impersonation offline_access`
* **OAuth redirect URI**: `https:///api/connections/oauth/callback`
# Observability and monitoring
Source: https://docs.bagofwords.com/data-sources/connectors/observability
Connect Splunk, Elasticsearch, OpenSearch, Jaeger, Zabbix, Prometheus, AWS CloudWatch and AWS Cost Explorer so the agent can investigate logs, traces, metrics and spend
These connectors let the agent investigate operational data — logs, search indices, distributed traces, monitoring metrics, and cloud spend — alongside your business data. None of them speak SQL natively, so Bag of words maps each platform onto a catalog the agent can reason about and issues queries in the platform's own language.
| Connector | What the catalog looks like | Query surface | Edition |
| :-------------------------------------- | :---------------------------------------------------------------------- | :---------------------------- | :--------------- |
| [Splunk](#splunk) | One table per `index::sourcetype` | SPL | Enterprise, Beta |
| [Elasticsearch](#elasticsearch) | One object per index or index pattern | Query DSL, SQL, ES\|QL | Beta |
| [OpenSearch](#opensearch) | One object per index or index pattern | Query DSL, SQL | Beta |
| [Jaeger](#jaeger) | Fixed tables: services, operations, spans, dependencies | Parameterized trace search | Beta |
| [Zabbix](#zabbix) | Fixed tables: hosts, items, triggers, problems, events, history, trends | JSON-RPC query specs | Enterprise |
| [Prometheus](#prometheus) | One table per metric, with its labels as columns | PromQL | Beta |
| [AWS CloudWatch](#aws-cloudwatch) | `log_group::` and `metric::` tables on one connection | Logs Insights, metric queries | Beta |
| [AWS Cost Explorer](#aws-cost-explorer) | Cost and usage tables | Cost Explorer API calls | Beta |
***
## Splunk
The Splunk connector is part of the **Enterprise Edition**, and is currently in **beta**.
Bag of words talks to the Splunk REST API on the management port (`https://:8089`). There is no SQL endpoint — queries are **SPL** run as oneshot search jobs.
Tables are `index::sourcetype` pairs, enumerated with one cheap `tstats` call that reads tsidx metadata rather than raw events, so discovery cost does not grow with the number of sourcetypes. Columns cost a real search, so fields are sampled only for the top sourcetypes by volume; the rest stay thin and the agent samples their fields on demand.
### Fields
| Field | Required | Default | Notes |
| :------------------------ | :------- | :------ | :-------------------------------------------------------------------------------------------------------------- |
| `host` | Yes | — | Splunk host, e.g. `splunk.acme.com`, or a full management URL such as `https://splunk.acme.com:8089`. |
| `port` | No | `8089` | REST/management port. Ignored when `host` is a full URL. |
| `verify_ssl` | No | `true` | Verify the server's TLS certificate. Disable only for self-signed certificates. |
| `discovery_window_days` | No | `7` | Default lookback applied to schema discovery and to searches that omit a time range. |
| `max_sampled_sourcetypes` | No | `50` | How many sourcetypes, ranked by event volume, get their fields sampled during indexing. Keeps reindexing cheap. |
### Authentication modes
Both modes support **system** and **user** scope.
**Authentication Token — `token`** (the default)
| Field | Required | Notes |
| :---------- | :------- | :---------------------------------------------------------------------------------------------------------- |
| `api_token` | Yes | A Splunk authentication token (**Settings → Tokens**). Recommended, and the way to connect to Splunk Cloud. |
**Username / Password — `userpass`**
| Field | Required | Notes |
| :--------- | :------- | :------------------------------------------------------ |
| `username` | Yes | A Splunk user with search access to the target indexes. |
| `password` | Yes | That user's password. |
***
## Elasticsearch
The Elasticsearch connector is in **beta**.
Indices, aliases and data streams map to catalog objects, and the index **mapping** is the schema — discovery is a single bulk `GET /_mapping`, with no document sampling. Daily or rolling time-series indices (`logs-app-2026.07.10`, `…07.09`, …) are collapsed into one `logs-app-*` object holding the union of their fields, so the catalog stays a handful of patterns instead of one entry per day.
Queries use the native query DSL wrapped in a JSON envelope, with `POST /_sql` and ES|QL (`POST /_query`, Elasticsearch 8.11+) available as escape hatches.
### Fields
| Field | Required | Default | Notes |
| :-------------- | :------- | :------ | :-------------------------------------------------------------------------------------------------------- |
| `host` | Yes | — | Host, e.g. `localhost`, or a full URL such as `https://es.example.com:9200`. |
| `port` | No | `9200` | REST port. Ignored when `host` is a full URL. |
| `secure` | No | `true` | Connect over HTTPS. Elasticsearch 8.x uses TLS by default. Ignored when `host` is a full URL. |
| `verify_certs` | No | `true` | Disable only for clusters using self-signed demo certificates. |
| `index_pattern` | No | — | Comma-separated index names or globs to expose, e.g. `logs-*,metrics-*`. Default: all non-system indices. |
### Authentication modes
**API Key — `apikey`** (the default; scopes: system and user)
| Field | Required | Notes |
| :-------- | :------- | :------------------------------------------------------------------------------------------------------------------------------------------ |
| `api_key` | Yes | An Elasticsearch API key. Paste either the encoded key or the raw `id:api_key` pair (**Stack Management → API keys**). Recommended for 8.x. |
**Username / Password — `userpass`** (scopes: system and user)
| Field | Required | Notes |
| :--------- | :------- | :---------------------------------------------------------------------------- |
| `user` | Yes | Username for HTTP basic auth, e.g. `elastic` or a role user with read access. |
| `password` | Yes | That user's password. |
**No Authentication — `none`** (scope: system, no fields). For clusters with security disabled or gated purely at the network layer.
***
## OpenSearch
The OpenSearch connector is in **beta**.
OpenSearch behaves like Elasticsearch: indices map to catalog objects, the mapping is the schema (one `GET /_mapping`, no document sampling), and time-series indices collapse into patterns. Queries are the native query DSL, with an SQL escape hatch via the bundled plugin (`/_plugins/_sql`).
### Fields
| Field | Required | Default | Notes |
| :-------------- | :------- | :------ | :----------------------------------------------------------------------------------------------------- |
| `host` | Yes | — | Host, e.g. `localhost`, or a full URL such as `https://search.example.com:9200`. |
| `port` | No | `9200` | REST port. Ignored when `host` is a full URL. |
| `secure` | No | `false` | Connect over HTTPS. Ignored when `host` is a full URL. |
| `verify_certs` | No | `true` | Disable only for clusters using self-signed demo certificates. |
| `index_pattern` | No | — | Comma-separated index names or globs to expose, e.g. `logs-*,orders`. Default: all non-system indices. |
### Authentication modes
**Username / Password — `userpass`** (the default; scopes: system and user)
| Field | Required | Notes |
| :--------- | :------- | :------------------------------------------------------------- |
| `user` | Yes | Username for HTTP basic auth (the OpenSearch security plugin). |
| `password` | Yes | That user's password. |
**No Authentication — `none`** (scope: system, no fields). For clusters with security disabled or network-gated.
***
## Jaeger
The Jaeger connector is in **beta**.
Jaeger has no query language — it is a parameterized trace search — so instead of discovering tables Bag of words presents a fixed catalog that mirrors the Query API: `services`, `operations`, `spans` and `dependencies`. Span rows are flattened to identity, topology, timing and status columns, plus the span's own tags.
### Fields
| Field | Required | Default | Notes |
| :----------------- | :------- | :------ | :----------------------------------------------------------------------------------------- |
| `base_url` | Yes | — | Jaeger Query URL including scheme and port, e.g. `http://jaeger:16686`. |
| `verify_ssl` | No | `true` | Verify the server's TLS certificate. Disable only for self-signed certs on internal hosts. |
| `default_lookback` | No | `1h` | Search window used when a query omits one, e.g. `1h`, `6h`, `2d`. |
| `default_limit` | No | `20` | Default maximum number of traces returned by a span search. |
### Authentication modes
**No Auth (network-gated) — `none`** (the default; scope: system, no fields). Jaeger Query typically has no auth of its own.
**Username / Password (Basic) — `basic`** (scopes: system and user)
| Field | Required | Notes |
| :--------- | :------- | :------------------------------------------------------------------------ |
| `username` | Yes | For HTTP basic auth — typically a reverse proxy in front of Jaeger Query. |
| `password` | Yes | That user's password. |
**Bearer Token — `bearer`** (scopes: system and user)
| Field | Required | Notes |
| :------ | :------- | :---------------------------------------------------------------------------------------------------- |
| `token` | Yes | Sent as `Authorization: Bearer `. Used when Jaeger Query sits behind an auth proxy or gateway. |
***
## Zabbix
The Zabbix connector is part of the **Enterprise Edition**.
Bag of words talks to the Zabbix JSON-RPC 2.0 API (the `/api_jsonrpc.php` endpoint is appended to your frontend URL automatically). Queries are JSON specs that map one-to-one onto Zabbix API methods — `host.get`, `item.get`, `problem.get`, `history.get`, and so on.
The catalog is a fixed set of virtual tables — hosts, items, triggers, problems, events, history, trends — because Zabbix's data model is stable. The `items` table is enriched from a live `item.get` so the agent sees the value types actually present.
### Fields
| Field | Required | Default | Notes |
| :-------------------- | :------- | :------ | :---------------------------------------------------------------------------------------------- |
| `url` | Yes | — | Your Zabbix frontend URL, e.g. `https://zabbix.acme.com`. |
| `verify_ssl` | No | `true` | Verify the server's TLS certificate. Disable only for self-signed certificates. |
| `history_window_days` | No | `7` | Default lookback applied when querying metric history or trends without an explicit time range. |
### Authentication modes
Both modes support **system** and **user** scope.
**API Token — `token`** (the default)
| Field | Required | Notes |
| :---------- | :------- | :-------------------------------------------------------------------------------------------------------------------- |
| `api_token` | Yes | A Zabbix API token (**Users → API tokens**). Recommended for Zabbix 5.4+, and the way to connect in SSO environments. |
**Username / Password — `userpass`**
| Field | Required | Notes |
| :--------- | :------- | :------------------------------------------------------------------------------------------------ |
| `username` | Yes | A Zabbix user with read access to the monitored hosts. Used on older installs without API tokens. |
| `password` | Yes | That user's password. |
Zabbix's SAML/OIDC SSO governs the **frontend** only — the API never accepts an external identity provider's token. An SSO user should mint a personal API token in the UI and use the token mode.
***
## Prometheus
The Prometheus connector is in **beta**.
Bag of words talks to the Prometheus HTTP API and queries in **PromQL**. Each metric becomes a table whose columns are that metric's labels, so the agent can filter and group without knowing the label set in advance.
Metric **type** matters for correct queries — a counter read without `rate()` returns a meaningless monotonic total — so each metric carries its type from `/api/v1/metadata`. Histogram and summary components are typed from their base metric: `_bucket` resolves to a histogram (use `histogram_quantile`), `_sum` and `_count` to counters.
Schema discovery is bounded to a recent window rather than the whole retention period, so a long-lived instance does not materialize every series it has ever seen. Widen it with `discovery_lookback_hours` only if a metric is scraped less often than the window.
The connector works against any Prometheus-compatible API, including Thanos, Cortex and Grafana Mimir — set `org_id` for the multi-tenant header those back-ends expect.
### Fields
| Field | Required | Default | Notes |
| :------------------------- | :------- | :------ | :--------------------------------------------------------------------------------------------------------------------------------------------- |
| `base_url` | Yes | — | Prometheus server URL including scheme and port, e.g. `http://prometheus:9090`. |
| `verify_ssl` | No | `true` | Verify the server's TLS certificate. Disable only for self-signed certs on internal hosts. |
| `org_id` | No | — | Sent as `X-Scope-OrgID` for multi-tenant back-ends (Thanos, Cortex, Grafana Mimir). |
| `metric_prefix` | No | — | Bound discovery on a large instance, e.g. `node_` or `http_`. Leave blank to index all metrics. |
| `discovery_lookback_hours` | No | `1` | How far back discovery looks for a metric's labels. Raise it only if a metric is scraped less often than that and its labels are being missed. |
| `timeout` | No | `30` | Per-request timeout in seconds for the Prometheus HTTP API. Raise it for a slow or heavily loaded instance. |
### Authentication modes
**No Auth (network-gated) — `none`** (the default; scope: system, no fields). For an instance reachable only over a VPN or internal network.
**Username / Password (Basic) — `basic`** (scopes: system and user)
| Field | Required | Notes |
| :--------- | :------- | :---------------------------------------------------------------------- |
| `username` | Yes | For HTTP basic auth — typically a reverse proxy in front of Prometheus. |
| `password` | Yes | That user's password. |
**Bearer Token — `bearer`** (scopes: system and user)
| Field | Required | Notes |
| :------ | :------- | :-------------------------------------------------------------------------------------------- |
| `token` | Yes | Sent as `Authorization: Bearer `. Used by most hosted or managed Prometheus offerings. |
***
## AWS CloudWatch
The AWS CloudWatch connector is in **beta**.
Logs and metrics on **one** connection, because an investigation crosses both halves — the function erroring in Logs is the one whose duration lives in Metrics. Splitting them across two connectors would put them on separate connections with no way for the agent to correlate.
Tables are namespaced by prefix, the way Splunk namespaces `index::sourcetype`:
```text theme={null}
log_group::/aws/lambda/checkout @timestamp, @message, @logStream
+ JSON keys sampled from recent events
metric::AWS/EC2/CPUUtilization + timestamp + value
```
Log discovery is schema-on-read: CloudWatch has no field catalog, so a log group's columns come from sampling recent events and parsing JSON out of `@message`. Only the largest groups by stored bytes are sampled; the rest stay thin and the agent inspects them on demand. Metrics are grouped by namespace and metric name, with their dimension names unioned — the API returns one entry per dimension-set variant.
Logs Insights bills on bytes **scanned**, and a `limit` clause does not reduce that — the time window is the only real cost control. Keep `discovery_window_hours` tight and set `log_group_prefix` on a busy account.
### Fields
| Field | Required | Default | Notes |
| :----------------------- | :------- | :------ | :--------------------------------------------------------------------------------------------------------------------------- |
| `region` | Yes | — | AWS region to read CloudWatch from, e.g. `eu-west-1`. Log groups and metrics are per-region. |
| `log_group_prefix` | No | — | Only discover log groups whose name starts with this, e.g. `/aws/lambda/`. Strongly recommended on a busy account. |
| `metric_namespaces` | No | — | Comma-separated namespaces to index as tables, e.g. `AWS/EC2,AWS/RDS`. Leave blank to index all. |
| `discovery_window_hours` | No | `24` | How far back to sample log events when inferring a log group's columns. Larger windows find more fields and scan more bytes. |
| `max_sampled_log_groups` | No | `25` | Cap on how many log groups, ranked by stored bytes, get their fields sampled during indexing. |
### Authentication modes
All three modes are **system** scope.
**AWS Access Key — `aws_keys`** (the default)
| Field | Required | Notes |
| :-------------- | :------- | :------------------------- |
| `access_key` | Yes | AWS access key id. |
| `secret_key` | Yes | AWS secret access key. |
| `session_token` | No | For temporary credentials. |
**AWS Assume Role (STS) — `aws_role`**
| Field | Required | Notes |
| :----------- | :------- | :----------------------------------------------------------------------------------- |
| `role_arn` | Yes | ARN of the IAM role to assume for CloudWatch access. |
| `access_key` | No | Used to assume the role. Leave blank to assume it from the instance profile or IRSA. |
| `secret_key` | No | Secret for the key above. |
**AWS Default Chain — `aws_default`** (no fields). Resolves credentials the way boto3 normally does — environment variables, shared config, EC2 instance profile, or EKS IRSA. This is the mode for a deployment running inside AWS, where no secret should be stored at all.
***
## AWS Cost Explorer
The AWS Cost Explorer connector is in **beta**.
Bag of words queries the AWS **Cost Explorer** API (`ce`) so the agent can analyze spend and usage over time — by service, account, tag, or any other Cost Explorer dimension.
### Fields
| Field | Required | Default | Notes |
| :------------ | :------- | :------ | :-------------------------------------------------------------- |
| `region_name` | Yes | — | AWS region used for the Cost Explorer client, e.g. `us-east-1`. |
### Authentication
**AWS Keys — `key`** (scopes: system and user)
| Field | Required | Notes |
| :----------- | :------- | :--------------------- |
| `access_key` | Yes | AWS access key id. |
| `secret_key` | Yes | AWS secret access key. |
The credential needs permission to call the Cost Explorer read APIs (`ce:GetCostAndUsage` and related). Because the mode is also available at user scope, individual users can supply their own keys instead of sharing the admin's — per-user credentials on a database-style connection require an Enterprise license. See [Authentication and access](/data-sources/authentication).
# OneNote
Source: https://docs.bagofwords.com/data-sources/connectors/onenote
Search and read Microsoft OneNote notebooks — pages become a searchable catalog the agent can grep and read, embedded images included
The **OneNote** connector reads Microsoft OneNote notebooks through **Microsoft Graph** and exposes their pages to the agent as a searchable catalog. A notebook's hierarchy — notebook, section groups, sections, pages — is flattened into `Notebook/Section/Page` paths, so the agent can list, search, grep, and read pages the same way it works with a file source. Embedded images on a page are extracted and passed to the model when the page is read.
The OneNote connector is part of the **Enterprise Edition**.
OneNote is **delegated-only**. Microsoft retired app-only (service-principal) access to the OneNote Graph APIs on **2025-03-31** with no replacement, so — unlike SharePoint — there is no app-only path that can ever read notebooks. The admin supplies an Entra app registration; each user then signs in, and their own token is what reads pages.
## How it works
Bag of words calls Microsoft Graph (`https://graph.microsoft.com/v1.0`) to walk notebooks, list pages, fetch page HTML, and pull embedded media. The agent gets **note-shaped** tools rather than file tools:
| Tool | What it does |
| :------------- | :------------------------------------------------------------------------------------------------------------------------------- |
| `list_notes` | The pages in the catalog, with their full `Notebook/Section/Page` path. |
| `search_notes` | Keyword search over page titles and paths — good when the user names a notebook, section, or page. |
| `grep_notes` | A regex/substring sweep over page **bodies** — good for an error string, hostname, ticket id, or any word written inside a page. |
| `read_note` | One page rendered as text, with its path and any embedded images passed through to the model's vision channel. |
### Shared catalog
Unlike OneDrive (which is per-user), the OneNote catalog is **shared** (`catalog_ownership: shared`). A OneNote deployment is usually a team knowledge base many people can see, so a per-user catalog would index the same notebook once per user and store N copies of identical page text. Instead, the first user to crawl populates the shared catalog; because a per-user crawl may only **add** rows (never prune), everyone else's crawl is skipped by the incremental check when nothing has changed. This also keeps the connection eligible for scheduled reindex.
### Indexing
By default the connector caches page **text** (`index_mode: content`). A page is a few KB of HTML and accounts hold hundreds of pages, not tens of thousands, so caching the body is affordable — and it is the only thing that makes a page findable by a word in its body, because Graph's page-level search does not reach work or school notebooks. Set indexing to titles-only or live-only if you would rather not cache page text.
## Notebook sources
One connection reads notebooks from a single source, chosen with **Notebooks To Read**:
| Source | Reads | Also set |
| :------ | :-------------------------------------------------------------------------------------------------------------------------------------- | :----------- |
| `me` | Each signed-in user's own notebooks. Requires a Microsoft 365 licence — personal notebooks live in OneDrive and are not reachable here. | — |
| `site` | A SharePoint site's notebooks. | **Site URL** |
| `group` | A Microsoft 365 group's notebook. | **Group ID** |
Site and group notebooks are the usual home of a shared team knowledge base and need no personal OneDrive.
## Before you start
* A **Microsoft Entra ID app registration** in your tenant, with a client secret.
* An administrator who can **grant admin consent** for the Graph permissions.
* Your Bag of words base URL, for the OAuth redirect URI.
* For a `site` source: the full SharePoint site URL. For a `group` source: the Microsoft 365 group id.
## Step 1 — Register an Entra ID application
[Azure Portal](https://portal.azure.com) → **Microsoft Entra ID** → **App registrations** → **New registration**. Copy the **Directory (tenant) ID** and **Application (client) ID** from the Overview page.
**Certificates & secrets** → **New client secret**. Copy the value immediately — it is shown once.
**Authentication** → **Add a platform** → **Web**:
```text theme={null}
https:///api/connections/oauth/callback
```
Replace `` with your Bag of words base URL.
If you already registered an app for [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) or [Outlook Mail](/data-sources/connectors/mail), you can reuse it — just add the OneNote permissions below and grant consent again.
## Step 2 — Grant Microsoft Graph permissions
Under **API permissions** → **Add a permission** → **Microsoft Graph** → **Delegated permissions**, add the permissions below, then click **Grant admin consent for \**.
| Permission | Why |
| :------------------ | :------------------------------------------------------------------ |
| `Notes.Read` | Read the signed-in user's own notebooks. |
| `Notes.Read.All` | Reach **shared**, site, and group notebooks the user has access to. |
| `User.Read` | Basic sign-in / profile. |
| `openid`, `profile` | OpenID Connect sign-in. |
| `offline_access` | Issue a refresh token so users are not asked to sign in every hour. |
Without admin consent, sign-in fails or returns a token with no usable Graph scopes. Omit `offline_access` and no refresh token is issued, so users must re-authenticate whenever the access token expires.
## Connect in Bag of words
Go to **Data Sources → Add data source** and choose **OneNote**. Enter the app registration credentials, pick a notebook source, and save. Each user then clicks **Connect** on the connection to sign in with their own Microsoft account before the agent can read any pages.
### Configuration fields
| Field | Required | Default | Notes |
| :-------------------- | :--------- | :-------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `notebook_source` | Yes | `me` | Whose notebooks to read: `me`, `site`, or `group` (see [Notebook sources](#notebook-sources)). |
| `site_url` | If `site` | — | SharePoint site holding the notebooks, e.g. `https://contoso.sharepoint.com/sites/Engineering`. |
| `group_id` | If `group` | — | Microsoft 365 group id whose notebook to read. |
| `include_globs` | No | — | Comma- or newline-separated glob patterns bounding which pages are indexed, matched against `Notebook/Section/Page` paths — e.g. `Team Notebook/**` or `**/Troubleshooting*/**`. Blank indexes every notebook the signed-in user can see. |
| `index_mode` | No | `content` | `content` caches page text (recommended); `metadata` caches titles/paths only; `none` caches nothing and reads pages live. |
| `max_catalog_objects` | No | `5000` | Safety cap on pages enumerated into one catalog. Truncation keeps the most recently modified pages. |
Scope with `include_globs` to the shared notebooks a team actually uses. It keeps personal notebooks out of the org catalog and bounds indexing cost.
## Authentication
### Sign in with Microsoft — `oauth`
Scopes: **system** and **user**. OneNote has a single authentication mode. Because there is no service-principal variant, the Entra app registration is captured here rather than under a separate credential.
| Field | Required | Notes |
| :-------------- | :------- | :--------------------------------------------------------------------- |
| `tenant_id` | Yes | Directory (tenant) ID. |
| `client_id` | Yes | Application (client) ID of the app registration used for user sign-in. |
| `client_secret` | Yes | The client secret value from Step 1. |
Each user clicks **Connect** and completes the Microsoft authorization-code flow against this app registration. Discovery and reads then run as that user, so people see only the notebooks their own account can reach.
See [Authentication and access](/data-sources/authentication) for how to require user sign-in on a connection.
## Troubleshooting
The user has not completed **Connect**. OneNote is delegated-only — there is no shared credential to fall back on, so a notebook is only reachable after the user signs in.
`Notes.Read` (own notebooks) or `Notes.Read.All` (shared/site/group notebooks) was not granted or not admin-consented. Check **API permissions** on the app registration.
The `me` source needs a Microsoft 365 licence — personal (consumer) OneNote notebooks live in OneDrive and are not reachable through this API. Use a `site` or `group` source for a shared team notebook.
The app registration must have `https:///api/connections/oauth/callback` registered as a **Web** platform redirect URI, matching your Bag of words base URL exactly.
`offline_access` is missing from the granted delegated permissions, so no refresh token is issued.
## Related
* [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) — the same Entra app registration backs both; SharePoint/OneDrive read files rather than notebook pages.
* [Gmail and Outlook Mail](/data-sources/connectors/mail) — another per-user Microsoft Graph source.
* [Authentication and access](/data-sources/authentication) — how per-user sign-in works.
# Oracle BI
Source: https://docs.bagofwords.com/data-sources/connectors/oracle-bi
Connect Oracle BI subject areas and query them with Logical SQL
Bag of words connects to **Oracle Business Intelligence** — OBIEE 11g/12c, Oracle Analytics Server, and Oracle Analytics Cloud — through the BI Web Services SOAP API. It discovers the subject areas the credential can see, reads their presentation tables and columns, and runs **Logical SQL** against the BI Server, so every query goes through your semantic model rather than around it.
The Oracle BI connector is part of the **Enterprise Edition**.
## How it works
All three products ship the same v12 web services at `/analytics-ws/saw.dll`, so one connector covers them:
1. Bag of words logs on (`nQSessionService.logon`) and holds a session ID.
2. It lists subject areas (`MetadataService.getSubjectAreas`) and describes each one with its presentation tables and columns (`MetadataService.describeSubjectArea`).
3. Queries run as Logical SQL (`XmlViewService.executeXMLQuery`), and the returned rowset is typed from its inline schema — numbers, dates, and booleans come back as real types, with Oracle's user-facing column captions applied.
Each presentation table becomes a schema entry named `SubjectArea/PresentationTable`, for example `A - Sample Sales/Products`.
Logical SQL is not database SQL. Columns are referenced as `"Presentation Table"."Column"` and the `FROM` clause names the **subject area**, not a table. Joins are implicit — the BI Server resolves them from the semantic model — and row limits use `FETCH FIRST N ROWS ONLY` rather than `LIMIT`.
## Before you start
* The base URL of the instance: the analytics URL for OBIEE/OAS, or the OAC instance URL.
* The **BI Web Services** SOAP endpoint (`/analytics-ws/saw.dll`) reachable from Bag of words over HTTP(S) — some deployments front the portal with a proxy that does not expose it.
* An account that can log on and has been granted the subject areas you want to expose. For OAC the username is the account's email; for OBIEE/OAS it is the domain user.
* A **deployed semantic model** (an RPD, or a Semantic Model on OAC). An instance with nothing deployed connects successfully but exposes no subject areas.
## Connect in Bag of words
Go to **Settings → Data Sources → Add data source → Oracle BI**. See [Connecting a data source](/data-sources/connecting) for the general flow.
| Field | Required | Default | Notes |
| :------------ | :------- | :------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `host` | Yes | — | Base URL of the Oracle BI instance, e.g. `https://analytics.example.com` or the OAC instance URL. Do not include `/analytics-ws` — the SOAP path is appended for you. |
| `verify_ssl` | No | `true` | Verify the TLS certificate when calling the SOAP endpoint. Disable only for self-signed test servers. |
| `timeout_sec` | No | `60` | HTTP timeout for SOAP calls. Raise it when large Logical SQL queries run long on the BI Server. |
**Test Connection** logs on and counts the subject areas. If the instance has none, the test still succeeds but says so explicitly — that means the credential works and there is nothing deployed for it to see.
## Authentication modes
| Mode | Scope | Fields |
| :---------------------- | :------------------ | :------------------------------------------- |
| **Username / Password** | `system` and `user` | `username` (required), `password` (required) |
* `username` — the Oracle BI / OAC user. Use the email address for OAC, the domain user for OBIEE and OAS.
* `password` — that user's password.
Because the mode is available at both scopes, you can configure **one shared service account** for the workspace (`system`), or have **each user supply their own Oracle BI credential** (`user`) so the BI Server applies that person's own subject-area grants and data filters. Per-user credentials on a connector like this require Enterprise — see [Authentication](/data-sources/authentication).
## Troubleshooting
The SOAP call reached the server but the credential was rejected. Check the username form for your product (email on OAC, domain user on OBIEE/OAS) and that the account is not locked. A SOAP fault is surfaced with Oracle's own message and error code.
Confirm `host` is the base URL only — the connector appends `/analytics-ws/saw.dll` itself, so a host that already includes it will not resolve. Also confirm that any reverse proxy in front of the instance forwards `/analytics-ws`.
Either no semantic model is deployed on the instance, or the account has not been granted any subject area. Deploy the RPD / Semantic Model, then grant the account access and re-index.
The BI Server echoes a subject area name back even when it cannot describe it, so entries that come back with no business model and no tables are dropped from the catalog. Grant the account access to that subject area's presentation tables.
Oracle returns query errors inside the rowset rather than as a fault; Bag of words surfaces the text and code as the query error. The usual causes are an unquoted identifier containing spaces, a column referenced with its subject area prefix instead of its presentation table, or an explicit `JOIN` clause — the semantic model resolves joins itself.
# Power BI
Source: https://docs.bagofwords.com/data-sources/connectors/power-bi
Connect Power BI semantic models to Bag of words and query them with DAX
Bag of words connects to the **Power BI REST API** to auto-discover the workspaces, semantic models (datasets), tables, and reports an identity can access, and to run **DAX** queries against them. This page covers everything you set up on the Microsoft side (app registration, tenant settings, workspace membership, permissions) and how to enter it in Bag of words.
The Power BI connector is part of the **Enterprise Edition**. Per-user (delegated) authentication in particular requires an Enterprise license.
## How it works
Bag of words authenticates to Power BI as an **Azure AD (Microsoft Entra ID) application**, then:
1. Lists the **workspaces** the identity belongs to (`GET /v1.0/myorg/groups`).
2. Lists the **semantic models** (datasets) and **reports** in each workspace.
3. Reads each model's **tables and columns** so the AI agent knows the schema. Discovery uses the **read-only Admin (Scanner) API** when available, and falls back to a DAX `COLUMNSTATISTICS()` probe per model otherwise.
4. Runs **DAX** queries at request time (`POST .../executeQueries`).
Each Power BI table is exposed to the agent as a schema table named `Dataset/Table` (for example `Sales Model/Customers`).
## Authentication modes
Power BI supports two authentication modes. You can use either, or both.
A single shared application identity (a **system** credential) discovers and queries Power BI for everyone. Simplest to operate. Best when all users may see the same models.
Each user signs in with their own Microsoft account (OAuth / on-behalf-of). Discovery and queries run with that user's own permissions, so each person sees only what they are allowed to. Requires Enterprise — see [Authentication](/data-sources/authentication).
With per-user authentication, a semantic model is selectable for a user as long as **their own** account can see it — even if the shared service principal cannot. Usage and instructions are still tracked at the organization level per model.
## Before you start
* A **Microsoft Entra ID (Azure AD)** tenant where you can create an app registration.
* A **Fabric / Power BI administrator** who can change tenant settings.
* Workspace admin rights on the workspaces you want to expose, so you can add the identity as a Member or Contributor.
* Outbound network access from Bag of words to `https://api.powerbi.com` and `https://login.microsoftonline.com`.
## Step 1 — Register an Azure AD application
In the [Azure Portal](https://portal.azure.com) → **Microsoft Entra ID** → **App registrations** → **New registration**.
Give it a name (e.g. `Bag of words - Power BI`). Under **Supported account types**, choose **Accounts in this organizational directory only** unless you specifically need multi-tenant.
From the app's **Overview** page, copy the **Directory (tenant) ID** and the **Application (client) ID**. You will paste these into Bag of words.
Go to **Certificates & secrets** → **New client secret**. Copy the **secret value** immediately (it is only shown once). This is the `client_secret` field in Bag of words.
Under **API permissions** → **Add a permission** → **Power BI Service**, add the delegated **Tenant.Read.All** (or the read scopes your policy allows). For per-user sign-in, keep the delegated **profile**, **email**, and **openid** scopes. Grant admin consent for the directory.
For **Sign in with Microsoft**, add a **Web** redirect URI under **Authentication**:
```text theme={null}
https:///api/connections/oauth/callback
```
Replace `` with your Bag of words base URL. Enable **offline\_access** so the token can be refreshed.
## Step 2 — Enable the Power BI tenant settings
These live in the **Power BI / Fabric Admin portal** → **Tenant settings** (a Fabric/Power BI administrator must change them). Applying each to a dedicated **security group** and adding your app to that group is the recommended pattern.
| Tenant setting | Why it matters |
| :------------------------------------------------------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Service principals can use Fabric / Power BI APIs** | Required for the service principal to call the Power BI REST API at all. Without it, discovery and queries fail. |
| **Service principals can access read-only admin APIs** | Lets Bag of words read model schemas via the Admin (Scanner) API — the most reliable discovery path, and the only one that reads schema without per-model query permission. |
| **Enhanced admin API responses with detailed metadata** | Makes the Scanner API return table/column schema (datasetSchema). Strongly recommended, especially for **DirectLake** and Fabric default semantic models. |
If the read-only admin APIs are **not** enabled, Bag of words falls back to a per-model DAX probe. That probe requires **Build** permission on each model and does not work for some **DirectLake** models — which is the most common reason a model appears in Power BI but is missing from the schema list. Enabling the two admin settings above resolves this for most tenants.
After enabling **Enhanced admin API responses**, models that have not been refreshed since the setting was turned on may still return no schema until their next refresh. Refresh such models once.
## Step 3 — Grant workspace and dataset access
For the **service principal**, discovery only sees workspaces where it holds a workspace **role** — sharing a single report or dataset directly is not enough. With **per-user** authentication this is looser: a model shared **directly** with a user (Build permission) is also discovered, even when they have no workspace role at all. That item-level path is exactly what row-level security requires (see the RLS step).
In each Power BI workspace → **Manage access** → **Add people or groups**, add the service principal (or the security group containing it), and any per-user accounts, as **Member** or **Contributor**.
For the **service principal** relying on the DAX discovery fallback, **Viewer is not enough** — a Viewer cannot run `executeQueries`. Use **Member** or **Contributor**, or enable the read-only admin APIs above. **Row-level security is the exception:** a per-user identity that must be RLS-filtered should be **Viewer or lower** (Member/Contributor bypass RLS) — see the RLS step below.
**Build** is the permission that actually lets an identity run DAX (`executeQueries`) — Read alone is not enough. Workspace Member/Contributor typically confers Build; you can also grant it **directly on the model** (the model's **Manage permissions → Add user → Build**). Direct Build with no workspace role is exactly what lets a per-user identity query a model under row-level security (see the next step).
Row-level security is enforced against the **querying identity**, and two Microsoft rules decide the setup:
* **A service principal cannot query an RLS model at all.** It cannot be added to an RLS role, so `executeQueries` returns `401` — even if the service principal is a workspace Member. Use **Sign in with Microsoft** (per-user) for any RLS-protected model; the service principal can still index non-RLS models in the same tenant.
* **An edit-level workspace role bypasses RLS.** Admin, Member, and Contributor have edit permission, so RLS does **not** apply to them. For RLS to take effect a user must hold at most **Viewer**, or no workspace role with the model shared to them directly.
So the correct setup for an RLS model is, per user: **Build** permission on the model **and** membership in the appropriate **RLS role**, with **no** edit-level workspace role. Bag of words discovers and queries the model with that user's own token, and Power BI filters the rows to their role.
## Connect in Bag of words
Go to **Settings → Data Sources → Add data source → Power BI** and fill in the form. See [Connecting a data source](/data-sources/connecting) for the general flow.
| Field | Required | Default | Notes |
| :-------------------- | :------- | :------ | :----------------------------------------------------------------------------------------------------------------------- |
| `tenant_id` | Yes | — | Azure AD Tenant ID (Directory ID) from the app's Overview page. |
| `client_id` | Yes | — | Azure AD App Registration Client ID. |
| `client_secret` | Yes | — | Azure AD App Registration secret value you copied in Step 1. |
| `oauth_client_id` | No | — | App Registration Client ID used for **user sign-in** (authorization code flow). If blank, falls back to `client_id`. |
| `oauth_client_secret` | No | — | Secret for the user-sign-in app. If blank, falls back to `client_secret`. |
| `workspaces` | No | — | Workspace name(s) or ID(s), comma-separated, to limit discovery. If empty, **all** accessible workspaces are discovered. |
Pick **Service Principal (Azure AD)** for a shared identity, or **Sign in with Microsoft** for per-user (delegated) access. The **Sign in with Microsoft** mode has no fields of its own — it reuses the app registration configured above.
Click **Test Connection**. Bag of words authenticates, lists workspaces, and probes a semantic model to verify query access. A model that is empty or not queryable does not fail the test — it reports that query access was verified.
To force every user to sign in with their own Microsoft account instead of using the shared service principal, enable **Require user authentication** under the data source's access settings. Each user then clicks **Connect** to sign in before they can query. See [Authentication](/data-sources/authentication).
After the connection indexes, choose which tables the AI agent may use, then save. See [Data sources overview](/data-sources/overview) for managing tables, instructions, and access.
## Querying with DAX
Once connected, the AI agent writes and runs **DAX** against your semantic models automatically. Tables are addressed as `Dataset/Table`, and relationships defined in the model are available for joins. You do not need to configure anything further to start asking questions.
## Personalized dashboards over Power BI RLS
With **per-user** authentication, a dashboard built on a Power BI model can be shared so that each viewer's queries run under **their own** token. Power BI's row-level security then filters the rows per person — one shared dashboard, and every viewer sees only what their RLS role allows. Configure this with **Viewer** run identity when sharing; see [personalizing a dashboard](/using-bow/dashboards#personalize-a-dashboard-per-viewer).
**View-as** on a Power BI (delegated) source previews the target identity's parameter binding but keeps *your* token, so it shows your source-level rows, not theirs. To confirm the exact rows another person gets under RLS, have them open the shared dashboard themselves.
## Troubleshooting: a model is missing from the schema
If a semantic model is visible in `app.powerbi.com` but not selectable in Bag of words, work through these in order:
For the **service principal**, discovery only sees workspaces where it has a role — add it as **Member** or **Contributor**, and note that content in **My Workspace** is not discovered. With **per-user** authentication this is looser: a model shared directly with the signed-in user (Build permission) is discovered even with no workspace role, so a direct dataset share **is** sufficient there — which is the setup RLS requires.
Without the read-only admin APIs, schema comes from a DAX probe that needs **Build** permission and does not work for some **DirectLake** models. Enable **Service principals can access read-only admin APIs** + **Enhanced admin API responses with detailed metadata** in the tenant settings, and grant **Build** on the model. The connection's indexing report lists models that were found but could not be read, with the reason.
The Scanner API returns no schema for models not refreshed since detailed-metadata scanning was enabled. Refresh the model once and re-index the connection.
With per-user authentication, the user must have completed **Connect** (Microsoft sign-in). Once signed in, models their own account can access become selectable even if the shared service principal cannot see them. If access was **just changed** in Power BI, note that Power BI caches user permissions — Bag of words refreshes them on sign-in and on **Reload tables**, so click **Reload** if a newly granted model hasn't appeared yet.
A model that only a signed-in user can see (for example an RLS model the service principal cannot index) is added to the catalog but starts **unselected**. An admin or the data source owner must enable it on the **Select tables** step before the agent can query it. Until then it appears in the user's table list but not in the agent's context.
If you set `workspaces`, only those workspaces are discovered. Clear it to discover everything, or add the workspace's name/ID.
## Reference
* **Service principal scope**: `https://analysis.windows.net/powerbi/api/.default`
* **Per-user (delegated) scope**: `https://analysis.windows.net/powerbi/api/.default offline_access`
* **OAuth redirect URI**: `https:///api/connections/oauth/callback`
For the on-premises product, see [Power BI Report Server](/data-sources/connectors/power-bi-report-server).
# Power BI Report Server
Source: https://docs.bagofwords.com/data-sources/connectors/power-bi-report-server
Connect an on-premises Power BI Report Server and query its reports, datasets, and PBIX models
Bag of words connects to an on-premises **Power BI Report Server (PBIRS)** over its REST API at `/Reports/api/v2.0/` using **NTLM** authentication. It discovers Power BI (`.pbix`) reports, paginated (RDL) reports, shared datasets, KPIs, and the upstream data-source lineage behind them, and lets the agent query the ones that are queryable.
The Power BI Report Server connector is part of the **Enterprise Edition**.
## How it works
Bag of words signs in with a Windows account, then enumerates the report server catalog and builds one schema entry per asset. Entries are prefixed by kind so the agent knows what it is looking at:
| Catalog entry | What it is | Queryable |
| :----------------------- | :--------------------------------------------------------------------------------------------------------------------------------- | :------------------ |
| `pbix:` | A Power BI report — the umbrella entry, carrying its data sources, upstream lineage, model tables, relationships, and DAX measures | No (metadata only) |
| `pbix:/
` | An internal table inside the report's semantic model | Yes, via SQL |
| `rdl:/` | A dataset inside a paginated (RDL) report, including its backing SQL (`command_text`) | Yes, via CSV export |
| `dataset:` | A shared dataset (`.rsd`) | Yes |
| `kpi:` | A KPI tile (current value, goal, status) | No (metadata only) |
### PBIX semantic models are a cached snapshot
Power BI Report Server has no `executeQueries` endpoint like the cloud service, so DAX cannot be run against an embedded `.pbix` model. Instead, Bag of words downloads the `.pbix`, extracts its Vertipaq tables to **Parquet**, and queries them with **DuckDB**. All tables from the same report are registered in one DuckDB session, so the agent can join them with plain SQL using the internal table names shown in the schema.
The data you query is a **snapshot of the last PBIX refresh**, not live upstream data. When the answer must be current, connect the report's upstream source (SQL Server, a file share, and so on) as its own data source instead — the `pbix:` entry lists that source in its metadata.
The Parquet cache is keyed by report ID **and** last-modified date, so editing and re-publishing a report invalidates it automatically. Caches are also warmed on a schedule so the first question about a large report does not stall. Auto-generated internal date tables (`LocalDateTable_*`, `DateTableTemplate_*`) are filtered out. Reports larger than 200 MB, and individual model tables above 5 million rows, are skipped rather than materialized.
DAX **measures** are captured as metadata but cannot be executed — they are expressions, not data. The agent rewrites them as SQL over the extracted columns when you ask for a measure-like aggregate.
## Before you start
* The report server's web portal URL, reachable from Bag of words over HTTP(S).
* A Windows account that can sign in to the report server and browse the folders you want to expose. It may be a domain account (`DOMAIN\user`) or a local machine account.
* If the server uses a certificate issued by an internal CA, the CA bundle file must be readable on the Bag of words host.
## Connect in Bag of words
Go to **Settings → Data Sources → Add data source → Power BI Report Server**. See [Connecting a data source](/data-sources/connecting) for the general flow.
| Field | Required | Default | Notes |
| :--------------- | :------- | :------ | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `server_url` | Yes | — | Base URL of the report server, e.g. `http://pbi.example.com` or `http://pbi.example.com/Reports`. Both forms work — the `/Reports/api/v2.0` API path is derived for you. |
| `verify_ssl` | No | `true` | Verify the TLS certificate. Disable only for self-signed test servers. |
| `ca_bundle_path` | No | — | Path to a custom CA bundle for internal certificates. Use this instead of turning `verify_ssl` off when the server's certificate comes from a private CA. |
**Test Connection** authenticates, reads `/System`, and counts the catalog. A successful test reports the product name and version along with how many Power BI reports, paginated reports, shared datasets, and KPIs were found.
## Authentication modes
| Mode | Scope | Fields |
| :----------------------------- | :------------------ | :---------------------------------------------------------------- |
| **Username / Password (NTLM)** | `system` and `user` | `username` (required), `password` (required), `domain` (optional) |
* `username` — the Windows username. It may already include a domain prefix (`DOMAIN\user`) or be a local machine user.
* `password` — the Windows password.
* `domain` — optional Windows domain (AD domain or workgroup/machine name). If you leave it blank and the username has no domain prefix, NTLM authenticates against the local machine.
Because the mode is available at both scopes, you can either configure **one shared service account** for the whole workspace (`system`) or require **each user to supply their own Windows credentials** (`user`), so the report server applies that person's own permissions. Per-user credentials on a connector like this require Enterprise — see [Authentication](/data-sources/authentication).
## Troubleshooting
The server answered but rejected the credentials. Check the username, password, and especially the **domain**: a local machine account needs the machine name as the domain (or a `MACHINE\user` username), while an AD account needs the AD domain.
The `/System` endpoint was not reachable. Verify `server_url` (both `http://host` and `http://host/Reports` are accepted), that the host is routable from Bag of words, and — for HTTPS with an internal CA — that `ca_bundle_path` points at a valid bundle.
Set `ca_bundle_path` to the CA bundle file rather than disabling `verify_ssl`. Turning verification off should be reserved for throwaway test servers.
Some reports have nothing to materialize: the report exceeds the 200 MB limit, every model table is above the 5 million row cap, or the file has no embedded semantic model (for example a thin report over a shared dataset). The `pbix:` entry still carries the upstream data sources — connect one of those directly to query live data.
Expected: PBIX queries run against the Parquet snapshot taken from the last published/refreshed `.pbix`. Republishing or refreshing the report changes its modified date, which invalidates the cache on the next query.
`/Datasets` only lists standalone shared datasets. Models embedded inside a `.pbix` never appear there — they are discovered from the report itself as `pbix:/` entries.
For the cloud service, see [Power BI](/data-sources/connectors/power-bi).
# Qlik Sense
Source: https://docs.bagofwords.com/data-sources/connectors/qlik-sense
Connect a Qlik Cloud tenant and let the agent query its apps with hypercubes
Bag of words connects to a **Qlik Cloud** tenant, discovers the apps a credential can see, and runs queries against them through the **Qlik Engine API (QIX)** — the same hypercube engine the Qlik front end uses. Dimensions, measures, and selections behave exactly as they do inside Qlik, including the associative model.
The Qlik Sense connector is part of the **Enterprise Edition**.
This connector is for **Qlik Cloud** (`https://..qlikcloud.com`). For on-premises **Qlik Sense Enterprise on Windows (QSEoW)**, use the [Qlik Sense on-prem](/data-sources/connectors/qlik-sense-onprem) connector instead.
## How it works
1. Apps are enumerated over REST (`/api/v1/items?resourceType=app`), following pagination and filtered by space when you configure one.
2. For each app, the model is read from `/api/v1/apps/{appId}/data/metadata`. If that returns nothing, Bag of words falls back to opening the app over a **WebSocket** and calling QIX `GetTablesAndKeys`.
3. Queries run as QIX hypercubes over a WebSocket to `wss:///app/`.
Each table inside an app becomes a schema entry named `Space/App/Table` (or `App/Table` when the app is not in a space). Fields tagged `$key` by Qlik become primary keys, and the tables that share a key are linked as relationships, so the agent understands how an app's tables associate.
Qlik is queried with **hypercubes, not SQL**. The agent sends a list of dimension field names plus measures written as Qlik expressions (`Sum([Net Sales])`, `Count(distinct [OrderID])`), and filters are applied as **Qlik selections** — they narrow the associative state and propagate across every related table, which is not how a SQL `WHERE` behaves.
If an app cannot be crawled, it still appears in the catalog as an inactive entry whose description carries the error, so a single broken app never aborts discovery of the rest of the tenant.
## Before you start
* Your Qlik Cloud **tenant base URL**, for example `https://acme.us.qlikcloud.com`.
* Permission on the tenant to generate an API key, or to create an OAuth client in the Management Console.
* The credential needs the **`apps.read`** scope and access to the spaces holding the apps you want to expose. A credential with no app visibility connects successfully but discovers nothing.
* Outbound network access from Bag of words to the tenant over **HTTPS and WebSocket (`wss://`)**. Queries fail if only plain HTTPS is allowed through.
## Step 1 — Create a credential
On the tenant, go to **Settings → API keys** and generate a key. Copy the value immediately — it is shown once. This is the fastest path: a single rotatable secret.
In the **Management Console**, create an OAuth client of the machine-to-machine kind and copy its **client ID** and **client secret**. Bag of words exchanges them for short-lived access tokens and refreshes them before expiry, which suits deployments with secret-rotation policies.
## Connect in Bag of words
Go to **Settings → Data Sources → Add data source → Qlik Sense**. See [Connecting a data source](/data-sources/connecting) for the general flow.
| Field | Required | Default | Notes |
| :------------- | :------- | :------ | :---------------------------------------------------------------------------- |
| `base_url` | Yes | — | Qlik Cloud tenant base URL, e.g. `https://tenant.us.qlikcloud.com`. |
| `verify_ssl` | No | `true` | Verify the TLS certificate on both the REST and WebSocket endpoints. |
| `space_filter` | No | — | Comma-separated space IDs or names. If empty, every visible space is crawled. |
**Test Connection** validates the credential against `/api/v1/users/me` and then asks for a single app to confirm the key can list content. It reports the identity it connected as, and tells you when the tenant has no apps visible to that credential.
## Authentication modes
Both modes are available at the `system` scope (one shared credential for the workspace) and the `user` scope (each person supplies their own, so Qlik applies that person's own space and app access). Per-user credentials on a connector like this require Enterprise — see [Authentication](/data-sources/authentication).
### API Key
| Field | Required | Default | Notes |
| :-------- | :------- | :------ | :------------------------------------------------------------------------------------------------ |
| `api_key` | Yes | — | Qlik Cloud API key, used as a bearer token. Generate it at **Settings → API keys** on the tenant. |
### OAuth 2.0 (Client Credentials)
| Field | Required | Default | Notes |
| :-------------- | :------- | :------------- | :---------------------------------------------------------------------------------- |
| `client_id` | Yes | — | OAuth client ID from the Qlik Cloud Management Console. |
| `client_secret` | Yes | — | The client secret that pairs with the client ID. |
| `scope` | No | `user_default` | Scope requested at token exchange. The default covers the standard Qlik Cloud APIs. |
## Troubleshooting
The credential is valid but sees nothing. Grant it the **`apps.read`** scope and add it to the spaces that hold your apps. If `space_filter` is set, check that the IDs or names in it match real spaces — anything else is filtered out silently.
For an API key, confirm it has not been revoked and that `base_url` is the tenant URL, including the region segment. For OAuth, confirm the client ID and secret pair is still active in the Management Console; the token exchange happens against `/oauth/token`.
Discovery can succeed over plain REST while queries need the **WebSocket** endpoint. Check that a proxy or firewall between Bag of words and the tenant allows `wss://` connections.
That app failed to crawl over both REST metadata and QIX. The reason is in the entry's description — usually a permission gap on that specific app, or an app whose model could not be opened.
Measures are Qlik expressions, and field names are **case-sensitive** and must match the schema exactly. Names with spaces need square brackets, as in `Sum([Net Sales])`.
# Qlik Sense on-prem
Source: https://docs.bagofwords.com/data-sources/connectors/qlik-sense-onprem
Connect Qlik Sense Enterprise on Windows with a QMC certificate and let the agent query its apps with hypercubes
Bag of words connects to a **Qlik Sense Enterprise on Windows (QSEoW)** site, discovers its streams and apps through the **Qlik Repository Service (QRS)**, and queries them through the **Qlik Engine API (QIX)** — the same hypercube engine the Qlik front end uses. Dimensions, measures, and selections behave exactly as they do inside Qlik, including the associative model.
This is the on-premises sibling of the [Qlik Sense](/data-sources/connectors/qlik-sense) (Qlik Cloud) connector. The two products share the Engine protocol and little else: discovery, authentication, and the grouping concept all differ, so each has its own connector.
| | Qlik Cloud | Qlik Sense Enterprise on Windows |
| :------------- | :---------------------- | :------------------------------- |
| Discovery | REST `/api/v1/items` | QRS REST on port `4242` |
| Authentication | Bearer token | Client certificate (mutual TLS) |
| Grouping | Space | **Stream** |
| Engine | `wss://tenant/app/{id}` | `wss://host:4747/app/{id}` |
| Identity | the token's own user | `X-Qlik-User` header |
The Qlik Sense on-prem connector is part of the **Enterprise Edition**.
## How it works
1. Streams and apps are enumerated over QRS (`/qrs/stream/full`, `/qrs/app/full`) using the client certificate. Unpublished apps — those still in a user's personal work area — are skipped by default.
2. For each app, Bag of words opens one Engine **WebSocket** session and reads the data model (`GetTablesAndKeys`), the published **master measures with their Qlik expressions**, master dimensions, variables, sheets, and data lineage.
3. Queries run as QIX hypercubes over a WebSocket to `wss://:4747/app/`.
Each table inside an app becomes a schema entry named `Stream/App/Table`. Fields tagged `$key` by Qlik become primary keys, and tables sharing a key are linked as relationships. Every app also contributes a `Stream/App/Master Items` entry — not a physical table, but the app's published measures (each carrying its full expression, set analysis included), dimensions, and variables, so the agent reuses the business logic the app's authors agreed on instead of re-deriving it.
Qlik is queried with **hypercubes, not SQL**. The agent sends dimension field names plus measures written as Qlik expressions (`Sum([Net Sales])`, `Count(distinct [OrderID])`), and filters are applied as **Qlik selections** — they narrow the associative state and propagate across every related table.
The certificate authenticates the *machine*, not a person, so every request also names the account Qlik should evaluate it as (the `X-Qlik-User` header). During discovery each app is opened as its owner, which avoids Section Access refusals; at query time the identity comes from the credential — see [Authentication modes](#authentication-modes).
## Before you start
* **Export the certificates from the QMC**: **Certificates → Export**, machine name of the Bag of words host, format **Platform independent PEM-format**. The bundle contains `client.pem`, `client_key.pem`, and `root.pem`.
* Outbound access from Bag of words to the Qlik central node on ports **4242** (QRS) and **4747** (Engine). On a default Windows install these are open locally but blocked by Windows Defender Firewall for remote hosts — add an inbound rule for both.
* The Server URL should be the hostname the certificates were exported for.
A Qlik client certificate is **admin-equivalent** — it can act as any user on the site. Treat the PEM files like an admin password: store them only in the connection's credentials, and re-export from the QMC if they ever leak.
## Connect in Bag of words
Go to **Settings → Data Sources → Add data source → Qlik Sense (on-prem)**. See [Connecting a data source](/data-sources/connecting) for the general flow.
| Field | Required | Default | Notes |
| :--------------- | :------- | :------ | :------------------------------------------------------------------------------------------------------------------------------------ |
| `server_url` | Yes | — | Central node hostname, e.g. `https://qlik.corp.example.com`. Any port in the URL is ignored — QRS and the Engine use the ports below. |
| `verify_ssl` | No | `true` | Verify the server's TLS certificate. Needs `root.pem` pasted in the credentials — see the TLS note below. |
| `stream_filter` | No | — | Comma-separated stream names or IDs. If empty, every visible stream is crawled. |
| `published_only` | No | `true` | Skip apps still in a user's personal work area. |
| `qrs_port` | No | `4242` | Qlik Repository Service port. |
| `engine_port` | No | `4747` | Qlik Engine Service port. |
**Test Connection** calls `/qrs/about`, lists streams and apps, and reports the Qlik version plus how many of each the credential can see.
**TLS on a default install.** Qlik signs its service certificates with its own root, issued to the machine's **Windows hostname**. If Bag of words reaches the server by that same name, paste `root.pem` into the Root CA field and keep Verify SSL on. If you connect via a different DNS name (a cloud VM's public hostname, for example), verification can never pass — turn **Verify SSL off and leave Root CA empty**. A pasted Root CA takes precedence over the toggle.
## Authentication modes
### Client Certificate (system)
The workspace-wide credential. All three PEM fields are multi-line — paste the full file contents including the `BEGIN`/`END` lines.
| Field | Required | Default | Notes |
| :-------------------- | :------- | :-------------- | :----------------------------------------------------------------------------------------------------------------------------------------------- |
| `client_cert` | Yes | — | Contents of `client.pem`. |
| `client_key` | Yes | — | Contents of `client_key.pem`. |
| `client_key_password` | No | — | Only if the exported key is password-protected. |
| `root_ca` | No | — | Contents of `root.pem`, for TLS verification. |
| `user_directory` | No | `INTERNAL` | Directory of the account Qlik should act as. |
| `user_id` | No | `sa_repository` | Account Qlik should act as. The default service account sees the whole site; set a real user to have Qlik apply that user's permissions instead. |
### Qlik Identity (per user)
When the connection has **Require user authentication** enabled, each person connects with only their Qlik identity — the certificate stays on the connection and is never handed to users. Their queries then run with **their own stream access and Section Access rules**, which is Qlik's row-level security.
| Field | Required | Default | Notes |
| :--------------- | :------- | :------ | :------------------------------------------------------------------------------------- |
| `user_directory` | Yes | — | The user's directory — the part before the backslash in `DOMAIN\user` in the Qlik hub. |
| `user_id` | Yes | — | The user's Qlik account. |
Per-user credentials require Enterprise — see [Authentication](/data-sources/authentication).
## Troubleshooting
Qlik's service certificate is issued to the machine's Windows hostname. If you connect by any other name — a cloud VM's public DNS name is the usual case — hostname verification fails even with the correct `root.pem`. Turn **Verify SSL off and clear the Root CA field** (a pasted root takes precedence over the toggle), or connect via a hostname the certificate actually covers.
The services listen on those ports, but Windows Defender Firewall blocks remote connections by default. Add an inbound rule on the Qlik server for TCP 4242 and 4747, and check any network firewall or cloud security group between Bag of words and the server.
Check `stream_filter` for names or IDs that don't match a real stream, and remember `published_only` (the default) hides apps that were never published to a stream.
An entry with an error in its description failed to crawl — usually a permission gap on that app. An entry described as having **no data model** belongs to an app whose load script has never run; it holds no data and cannot be queried, though its master items are still published if it has any.
That is Qlik's virtual-proxy **host allow list** rejecting the hostname — a Qlik-side setting for browser access on 443. It does not affect this connector, which talks to QRS and the Engine directly. To fix the hub itself, add the hostname in QMC → Virtual proxies → Advanced → Host allow list.
Measures are Qlik expressions, and field names are **case-sensitive**. Names with spaces need square brackets, as in `Sum([Net Sales])`. Prefer the expressions published in the app's `Master Items` entry — they carry the set analysis the app's authors intended.
# Amazon S3
Source: https://docs.bagofwords.com/data-sources/connectors/s3
Expose an S3 bucket (or a prefix within it) to the agent as a searchable file catalog
The **Amazon S3** connector points Bag of words at a bucket, optionally scoped to a key prefix. The agent lists objects, greps them, and reads them — including inside PDF, Word, PowerPoint, Excel and CSV — and can attach an object to a report. Objects too large to load whole can be read in byte-range windows.
This connector is in **beta**. Fields and behavior may change between releases.
S3 appears under the database category in the add-connection grid, but it is a **file** connection: the agent sees files and reads them, it does not write SQL against them.
## How it works
Bag of words builds a file catalog from the bucket. It uses the same parsing and search pipeline as [Files and Directories](/data-sources/connectors/files-and-directories), with object-store-appropriate limits:
* **`list_files`** — a bounded `ListObjectsV2` under the prefix.
* **`read_file`** — `GetObject`, with `.csv`/`.tsv`/`.xlsx`/`.xls` parsed into tables and `.pdf`/`.docx`/`.pptx` text-extracted.
* **Windowed reads** — a byte-range `GetObject` for objects too large to load whole (logs, ndjson, big CSVs).
* **`grep_files`** — line-level grep with an explicit file, byte and time budget, and a resumable cursor.
There is no live full-content search: a content scan over an object store is one `GetObject` per key, so keyword search runs against the indexed catalog instead. Writes are not supported.
Everything is confined to `bucket` + `prefix`. A file id is the key **relative to the prefix**, and any id that escapes it is rejected.
## Before you start
* The bucket exists, and you know its **region** (or the endpoint of your S3-compatible store).
* The credential you will use can call `s3:ListBucket` on the bucket and `s3:GetObject` on the keys you want to expose. Scope the IAM policy to the prefix you are connecting.
* For a non-AWS store (MinIO, Cloudflare R2, Wasabi), you have its endpoint URL and a matching access key pair.
* For **AWS Default Chain** or a role assumed without static keys, the backend host must already carry credentials — an instance profile, IRSA, or the standard environment/config files.
## Connect in Bag of words
Go to **Data Sources → Add data source → Amazon S3** and fill in the form.
| Field | Required | Default | Notes |
| :-------------------- | :------- | :-------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `bucket` | Yes | — | Bucket name, e.g. `my-company-reports`. |
| `prefix` | No | — | Key prefix that scopes the connection, e.g. `reports/2025/`. All listing and reads are confined to it. Blank means the whole bucket. |
| `region` | No | — | AWS region of the bucket, e.g. `us-west-2`. Recommended — it avoids a redirect on the first call. |
| `endpoint_url` | No | — | Custom endpoint for S3-compatible stores (MinIO, Cloudflare R2, Wasabi). Leave blank for AWS. |
| `include_globs` | No | — | Comma- or newline-separated glob patterns relative to the prefix, e.g. `docs/**/*.pdf`, `**/*.csv`, `reports/**`. When set, only matching objects are visible **and** readable. `**` crosses sub-prefixes, `*` matches one segment. |
| `recursive` | No | `true` | Enumerate keys below the prefix when listing and indexing. |
| `max_file_mb` | No | `100` | Reject whole-object reads above this size. Windowed byte-range reads are exempt. |
| `index_mode` | No | `content` | How much is cached from the bucket — see below. |
| `max_catalog_objects` | No | `5000` | Cap on objects indexed into the catalog, so a huge bucket cannot produce an unbounded catalog. |
`allowed_extensions` and `index_content` are **deprecated**. Use `include_globs` with a pattern like `**/*.pdf` instead of `allowed_extensions`, and `index_mode` instead of `index_content`.
### Indexing modes
Reads are always live; `index_mode` only decides what is cached ahead of time.
| Mode | What is cached | Use when |
| :--------- | :------------------------------------------------------------------------------- | :---------------------------------------------- |
| `none` | Nothing — listing and reads go live. | The bucket is huge or highly volatile. |
| `metadata` | The object list only. | You want a fast catalog without content search. |
| `content` | The object list plus extracted keywords, so the agent can find objects by topic. | The default. |
## Authentication modes
All three modes are **system-scope only** — one shared credential serves every user of the connection. There is no per-user sign-in for S3; restrict who can use the connection with access rules instead. See [Authentication and access](/data-sources/authentication).
### AWS Access Key (`aws_keys`)
The default. Static IAM credentials.
| Field | Required | Notes |
| :-------------- | :------- | :---------------------------------------- |
| `access_key` | Yes | AWS access key id. |
| `secret_key` | Yes | AWS secret access key. |
| `session_token` | No | Session token, for temporary credentials. |
### AWS Assume Role (STS) (`aws_role`)
Bag of words calls `sts:AssumeRole` and uses the returned temporary credentials.
| Field | Required | Notes |
| :----------- | :------- | :----------------------------------------------------------------------------------------- |
| `role_arn` | Yes | ARN of the IAM role to assume for bucket access. |
| `access_key` | No | Access key id used to assume the role. Leave blank to use the instance profile / IRSA. |
| `secret_key` | No | Secret access key used to assume the role. Leave blank to use the instance profile / IRSA. |
### AWS Default Chain (`aws_default`)
No fields. Bag of words uses the standard AWS credential chain on the backend host — environment variables, shared config, instance profile, or IRSA. Use this when the deployment already has an AWS identity and you do not want to store keys in the product.
## Troubleshooting
Check `include_globs` — patterns are matched relative to `prefix`, so a pattern that repeats the prefix will never match. Also confirm `recursive` is on if the objects sit below sub-prefixes.
The credential has `s3:ListBucket` but not `s3:GetObject` on those keys, or the object is outside `include_globs` — an off-glob key is denied, not just hidden.
Whole-object reads above `max_file_mb` are rejected. Ask the agent for a windowed read, or raise the limit.
The bucket exceeded `max_catalog_objects`. Narrow the connection with `prefix` or `include_globs` rather than raising the cap.
# SAP
Source: https://docs.bagofwords.com/data-sources/connectors/sap
Connect SAP HANA, SAP BW, SAP Datasphere, and SAP BusinessObjects to Bag of words
Bag of words ships four SAP connectors. They are complementary rather than alternatives: each reaches a different layer of the SAP landscape, with its own catalog, query language, and security model. This page covers all four — pick the one that matches the system you want to query, or connect several.
| Connector | What it reaches | Query language | Per-user security |
| :---------------------- | :------------------------------------------------------------------------------------- | :------------------------------- | :------------------------------------------------------------ |
| **SAP HANA** | HANA, HANA Cloud, and Datasphere Open SQL schemas — tables and views over the SQL port | SQL | HANA analytic privileges, per database user |
| **SAP BW (XMLA)** | BW / BW4HANA InfoProviders and BEx queries as XMLA cubes | MDX | Analysis authorizations, per signed-in SAP user |
| **SAP Datasphere** | The Datasphere semantic layer — analytic models with measures and dimensions | OData query options | Data Access Controls, per user token |
| **SAP BusinessObjects** | On-prem universes (the BOBJ semantic layer) via `/biprws` | Result-object selection (no SQL) | Universe security profiles and CMS rights, per logged-on user |
Server-side row-level security in SAP — Data Access Controls, analytic privileges, analysis authorizations, universe security profiles — is only enforced when the query runs under the end user's own identity. A single shared technical account collapses all of it to one identity. For any protected object, use the connector's **per-user** authentication mode. Per-user authentication on database-style connectors requires an Enterprise license; see [Authentication](/data-sources/authentication).
***
## SAP HANA
Plain SQL against the HANA SQL port via SAP's official `hdbcli` driver. Covers on-premise HANA, HANA Cloud, and SAP Datasphere's **Open SQL** schema — where views marked *Expose for Consumption* appear in the space schema and are queried like any other view.
### How it works
Bag of words connects with the configured database user and introspects `SYS.TABLE_COLUMNS` / `SYS.VIEW_COLUMNS` (joined to `SYS.TABLES` / `SYS.VIEWS` for comments, plus `SYS.CONSTRAINTS` for primary keys). Tables **and views** are both first-class — Datasphere exposes only views. If the enriched introspection fails on a low-privilege user, it falls back to a minimal query without comments or keys.
Unless you scope the connection to specific schemas, HANA's own and SAP-delivered schemas are filtered out of discovery: `SYS`, `SYSTEMDB`, `PUBLIC`, `UIS`, `HANA_XS_BASE`, `SAP_XS_LM`, and anything starting with `_SYS`, `SAP_`, `XSSQLCC`, `HDI_`, or `BROKER_`.
Each object is exposed to the agent as `SCHEMA.OBJECT`. The agent writes HANA SQL; unquoted identifiers fold to uppercase, so mixed-case Datasphere view names have to be double-quoted exactly as the schema shows them.
### Before you start
* The SQL port must be reachable from the Bag of words backend host: `443` for HANA Cloud and Datasphere, `313` or `341` on-premise.
* A database user with `SELECT` on the objects you want. For Datasphere, that is a **space database user** such as `MYSPACE#ANALYST`, created in the space's database-access settings.
* For Datasphere, the views must be marked **Expose for Consumption** — nothing else is readable in the Open SQL schema.
### Fields
| Field | Required | Default | Notes |
| :----------- | :------- | :-------- | :------------------------------------------------------------------------------------------------------------------------------- |
| `host` | Yes | — | SQL endpoint host. For HANA Cloud / Datasphere, the instance hostname (`….hanacloud.ondemand.com`). |
| `port` | No | `443` | `443` for HANA Cloud / Datasphere; `313` or `341` on-premise. |
| `database` | No | *(empty)* | Tenant database name when connecting through the system database of a multitenant HANA. Leave empty for HANA Cloud / Datasphere. |
| `schema` | No | *(empty)* | A schema, or a comma-separated list. For Datasphere, the space schema. Leave empty to discover all non-system schemas. |
| `encrypt` | No | `true` | Connect over TLS. Required for HANA Cloud and Datasphere; disable only for on-premise systems without TLS. |
| `verify_ssl` | No | `true` | Verify the server certificate. Disable for certificates signed by an internal CA the backend host does not trust. |
### Authentication modes
| Mode | Scope | Fields |
| :---------------------- | :------------------ | :------------------------------------------------------------------------------------------ |
| **Username / Password** | System and per-user | `user` — database user (for Datasphere, a space user such as `MYSPACE#ANALYST`); `password` |
Shared (system) use puts one database user behind every query. Per-user use has each person supply their own HANA user, so HANA analytic privileges apply to them individually.
The Open SQL / HANA SQL path authenticates as a **database user**, which is a weaker per-user story than Datasphere's OData consumption API with a per-user OAuth token. If Data Access Controls matter for a model, query it through the **SAP Datasphere** connector instead.
### Troubleshooting
* **Connection fails outright** — the message is the raw driver error. Check host, port, and whether TLS is expected (`encrypt`).
* **No tables discovered** — the user has no `SELECT` anywhere outside the filtered system schemas, or (Datasphere) no views are exposed for consumption. Set `schema` explicitly if your objects live in a schema whose name matches one of the filtered prefixes.
* **Object not found at query time** — mixed-case or dotted names must be double-quoted exactly as shown in the schema, for example `"MySpace"."Sales Orders View"`.
***
## SAP BW (XMLA)
BW / BW4HANA InfoProviders and BEx queries, queried with **MDX** over BW's standard XMLA web service. No RFC SDK is involved — XMLA is plain SOAP over HTTP — and unlike the BW-OData path there is no "one structure per query" limit.
### How it works
Bag of words builds the endpoint URL from the server base URL plus the XMLA ICF path, then speaks the same XMLA contract as every other XMLA source:
1. `DBSCHEMA_CATALOGS` for catalogs, `MDSCHEMA_CUBES` for the InfoProviders and released queries in each.
2. `MDSCHEMA_HIERARCHIES` and `MDSCHEMA_MEASURES` for each cube — BW characteristics become dimension columns, key figures become measure columns.
3. XMLA `Execute` for MDX at query time.
Each InfoProvider/query is a schema table named `Catalog/Cube`. BW technical names are not guessable, so the agent references characteristics and key figures by the `metadata.unique_name` recorded during discovery.
**Analysis authorizations (RSECADMIN) are enforced by BW's OLAP processor for the identity that runs the query.** That only produces correct row-level results when the connection uses per-user credentials.
### Step 1 — Activate the XMLA service in SICF
This is the prerequisite most BW connections trip over. The BW XMLA provider is an **ICF service** that is not necessarily active on a given system — and it is less emphasised in newer BW/4HANA releases, so verify it rather than assume it.
In transaction **SICF**, navigate to the service path and activate it:
```text theme={null}
/sap/bw/xml/soap/xmla
```
Its WSDL is served at the same URL with `?wsdl` appended — a quick way to confirm the node is live.
The connector authenticates with **HTTP Basic** against the ICF node. Make sure the node's logon procedure accepts it.
BEx queries must be released for external access to appear as XMLA cubes. A query that exists in BW but is not released will not be discovered.
Prefer a released BEx query's cube over the raw InfoProvider when one exists — it carries the intended restricted and calculated key figures.
### Fields
| Field | Required | Default | Notes |
| :------------- | :------- | :---------------------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `host` | Yes | — | BW application server base URL, e.g. `https://bw.example.com:44300`. The XMLA path is appended automatically; `https://` is assumed if you omit the scheme. |
| `xmla_path` | No | `/sap/bw/xml/soap/xmla` | ICF path of the XMLA web service. The default suits standard systems. |
| `sap_client` | No | *(empty)* | SAP client/mandant, e.g. `100`. Appended to the endpoint as `sap-client=`. |
| `sap_language` | No | *(empty)* | Logon language, e.g. `EN`. Appended as `sap-language=`. |
| `catalog` | No | *(empty)* | A single InfoProvider/catalog to scope discovery to. Leave empty to discover all visible catalogs. |
| `verify_ssl` | No | `true` | Verify the server certificate. Disable only for internal CAs the backend host does not trust. |
### Authentication modes
| Mode | Scope | Fields |
| :------------------------------ | :------------------ | :------------------------------------- |
| **SAP User / Password (Basic)** | System and per-user | `username` — SAP user name; `password` |
Use **per-user** whenever analysis authorizations matter: each person provides their own SAP credentials, the MDX runs under their named SAP user, and BW restricts the result server-side. A shared system user returns whatever that one account is entitled to see, for everyone.
### Troubleshooting
* **HTTP 404** — reported as *"nothing serves XMLA at this URL path"*, with the hint that the BW path is usually `/sap/bw/xml/soap/xmla`. Activate the node in SICF, or correct `xmla_path`.
* **HTTP 401 / 403** — the endpoint was found but the credentials or the authentication scheme were rejected. Check the SAP user, and that the ICF node accepts Basic authentication.
* **Connected, but 0 catalogs** — reported as *"No InfoProviders/queries visible to this user — check the user's analysis authorizations and that queries are released for external access."*
* **DNS or timeout errors** — the endpoint URL never resolved or nothing answered; these are reported separately from HTTP failures so you can tell a network problem from a path problem.
***
## SAP Datasphere
The Datasphere **semantic layer** — analytic models with measures, dimensions, and server-side aggregation — over the OData Consumption API. This is the governed path; the SAP HANA connector above reaches the same tenant's raw Open SQL views instead.
### How it works
1. Authenticates with OAuth against the tenant's auth server (client credentials for a technical user, or a per-user token from the authorization-code flow).
2. Crawls the catalog `assets` collection — one call spans every authorized space — following `@odata.nextLink` paging, optionally filtered to the spaces you name.
3. Reads each asset's OData `$metadata` and classifies every property as a **measure** (SAP analytics annotation, or a numeric EDM type as fallback) or a **dimension**.
4. Queries the analytical OData endpoint at request time. Measures aggregate **server-side** over the dimensions in `$select`; `$filter`, `$orderby`, and `$top` work as usual, and analytic-model variables are passed as `(P='v')/Set` parameters.
Each model is a schema table named `Space/Model`. The agent writes OData query options — no SQL, DAX, or MDX.
### Before you start
* Objects must be marked **Expose for Consumption** in Datasphere; nothing else appears in the catalog.
* An OAuth client from **Administration → App Integration** in the Datasphere tenant. That page also shows the tenant's **token** and **authorize** URLs — copy them from there rather than constructing them.
* For per-user sign-in, a second OAuth client of purpose **Interactive Usage** whose redirect URI is your Bag of words callback.
### Step 1 — Create the OAuth clients
In **Administration → App Integration**, add an OAuth client for **API Access** with a technical-user (client credentials) purpose. Copy its **client ID** and **client secret**, plus the **Token URL** shown on the page.
Add a second OAuth client with the **Interactive Usage** purpose and this redirect URI:
```text theme={null}
https:///api/connections/oauth/callback
```
Copy its client ID and secret into the **OAuth Client ID / OAuth Client Secret** fields, and the page's **Authorization URL** into `authorization_url`. If you leave the OAuth client fields blank, the technical-user client is used for sign-in instead.
Older tenants serve the consumption APIs under `/api/v1/dwc/…`; newer tenants use `/api/v1/datasphere/consumption/…`. Both are configurable on the connection — see the fields below.
A model protected by **Data Access Controls** returns an *empty* result to a technical user rather than an error. If a model that clearly has data comes back with no rows, query it with per-user authentication.
### Fields
| Field | Required | Default | Notes |
| :------------------ | :------- | :------------------------ | :------------------------------------------------------------------------------------------------------------------------------------------ |
| `host` | Yes | — | Consumption host, e.g. `mytenant.us10.hcs.cloud.sap` — no scheme, no path. |
| `token_url` | Yes | — | Token endpoint from Administration → App Integration, e.g. `https://.authentication..hana.ondemand.com/oauth/token`. |
| `authorization_url` | No | *(empty)* | Authorize endpoint, needed only for per-user sign-in, e.g. `https://.authentication..hana.ondemand.com/oauth/authorize`. |
| `space` | No | *(empty)* | Space ID(s), comma-separated, to scope discovery. Empty discovers every accessible space. |
| `catalog_path` | No | `/api/v1/dwc/catalog` | Base path of the catalog API. Newer tenants may use `/api/v1/datasphere/consumption/catalog`. |
| `consumption_path` | No | `/api/v1/dwc/consumption` | Base path of the consumption (data) API. Newer tenants may use `/api/v1/datasphere/consumption`. |
| `verify_ssl` | No | `true` | Verify the server certificate. Disable only for test endpoints with self-signed certificates. |
### Authentication modes
| Mode | Scope | Fields |
| :-------------------------------------------- | :------------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Technical User (OAuth client credentials)** | System only | `client_id`, `client_secret` — the technical-user client. Optional `oauth_client_id` / `oauth_client_secret` — the Interactive Usage client used for per-user sign-in; blank falls back to the technical-user client. |
| **Sign in with SAP (per-user)** | Per-user only | None — each user signs in through the authorization-code flow and their delegated token is stored for them. |
The technical user drives discovery, indexing, and shared queries. Per-user sign-in is what makes Data Access Controls apply, so use it for anything protected.
### Troubleshooting
* **"Authentication failed"** — the client-credentials grant was refused. Re-check `token_url`, the client ID, and the secret.
* **"Authenticated, but catalog listing failed"** — the token is good but the catalog path is wrong. Try the newer `/api/v1/datasphere/consumption/catalog` prefix.
* **Connected, 0 exposed assets** — the message points at the three causes: the OAuth client's scoped roles, space membership, and whether objects are marked *Expose for Consumption*.
* **A model returns no rows** — most often a Data Access Control filtering everything out for a technical user. Switch that connection to per-user sign-in.
***
## SAP BusinessObjects
On-prem **universes** (the BOBJ semantic layer) through the `/biprws` RESTful Web Service SDK. Each universe becomes one schema table whose columns are its dimensions/attributes and measures; the agent selects **result objects** and BusinessObjects generates and runs the query, applying the universe's security for the logged-on user. There is no SQL to write.
### How it works
1. Logs on at `POST /biprws/logon/long` and caches the returned `X-SAP-LogonToken`, which is resent (double-quoted, as the BI Platform contract requires) on every subsequent call.
2. Enumerates universes with `GET /biprws/sl/v1/universes`, paging by offset.
3. Reads each universe's outline (`GET /biprws/sl/v1/universes/{id}`) and flattens it into columns — measures become `role=measure`, dimensions/attributes/details become `role=dimension`. Filters and predefined conditions are skipped because they are not result objects. A universe whose detail cannot be read still appears, with no columns, rather than failing the whole crawl.
4. Runs queries by posting a query specification naming the universe and its result objects.
### Before you start
* The **RESTful Web Service SDK must be deployed and reachable** on the BusinessObjects web tier — that is what serves `/biprws`. It is a separate web application from the BI Launch Pad; if it was not deployed, no URL under `/biprws` exists and every call 404s. Typical web-tier ports are Tomcat `8080` and WACS `6405`, over TLS.
* Universes must be published to the repository to be discoverable.
* A CMS account resolvable through the authentication plugin you intend to use — or, for **Trusted Authentication**, the shared secret (see below).
### Step 1 — Choose the logon method
Pick the CMS authentication plugin in the `auth_type` field: `secEnterprise` (native), `secLDAP`, `secWinAD` (Active Directory), or `secSAPR3` (SAP). Each resolves to a named CMS user, and that named user drives all security. `secSAPR3` aliases the BO user to an SAP/BW account, which is useful when a universe sits on top of a BW connection.
Trusted Authentication logs a **named user on without their password** — the shared secret authenticates the calling application, and the user to act as is named in the request. Because it bypasses the credential-plugin check, it works no matter which SSO BusinessObjects itself runs (Kerberos/AD, SAML, or SAP).
Enable it in **CMC → Authentication → Enterprise → Trusted Authentication**, then use the generated shared secret (the value distributed as `TrustedPrincipal.conf`).
The shared secret lets Bag of words log on as **any** named user. Treat it as a high-privilege credential, restrict it to the accounts you intend, and rotate it in the CMC if it is ever exposed.
### Fields
| Field | Required | Default | Notes |
| :----------- | :------- | :-------- | :-------------------------------------------------------------------------------------------------------------------------------------- |
| `host` | Yes | — | Web tier base URL, e.g. `https://boserver:6405`. The base path is appended automatically; `https://` is assumed if you omit the scheme. |
| `base_path` | No | `/biprws` | Base path of the RESTful Web Service SDK. The default suits standard deployments. |
| `verify_ssl` | No | `true` | Verify the server certificate. Disable only for internal CAs the backend host does not trust. |
### Authentication modes
| Mode | Scope | Fields |
| :-------------------------------------------------------- | :------------------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Username / Password (secEnterprise / LDAP / AD / SAP)** | System and per-user | `username`; `password`; `auth_type` — one of `secEnterprise` (default), `secLDAP`, `secWinAD`, `secSAPR3`. Any other value is rejected before the logon is attempted. |
| **Trusted Authentication (per-user, no password)** | System and per-user | `trusted_user` — the named BusinessObjects user to log on as; `shared_secret` — from CMC → Authentication → Enterprise → Trusted Authentication. |
Both modes can be shared or per-user. Universe security profiles and CMC object rights are enforced against the logged-on named identity in either case — trusted authentication produces a genuine named-user session, so nothing is bypassed.
### Troubleshooting
* **"Authentication failed: Logon failed: HTTP …"** — the logon call itself was refused. For username/password, check the `auth_type` plugin matches how the account is defined. For trusted auth, check the shared secret and that Trusted Authentication is enabled in the CMC.
* **"Logon succeeded but no X-SAP-LogonToken was returned"** — the endpoint answered but is not the RESTful Web Service SDK. Verify `base_path` and that `/biprws` is deployed on that web tier.
* **"Logged on, but universe listing failed"** — the session is valid but `/sl/v1/universes` failed; the Semantic Layer part of the SDK is the thing to check.
* **Connected, 0 universes** — reported with the causes: the user's rights, and whether universes are published to the repository.
# SharePoint Lists
Source: https://docs.bagofwords.com/data-sources/connectors/sharepoint-lists
Query SharePoint lists as tables — every list on a site becomes a queryable table with typed columns and OData filters
Where the [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) connector reads a site's **document libraries as files**, this connector reads the site's **SharePoint lists as tables**. Every list becomes a catalog table with typed columns, and the agent queries it the way it queries a database — filters, ordering and column selection run server-side through Microsoft Graph, and the rest happens in pandas.
The SharePoint Lists connector is part of the **Enterprise Edition**.
## What the agent sees
The connection points at one site. Every visible list on that site — a site can have many — is discovered as its own table:
* **Columns come from the list's own schema.** Text, choice, number, currency, date, boolean, person and lookup columns are typed accordingly; noise columns (compliance tags, attachments plumbing) are filtered out. `ID`, `Created`, `Modified`, `Created By` and `Modified By` are included.
* **Display names, not internal names.** A SharePoint column displayed as `2017` may internally be `field_2`; one displayed as `Category` may be `field_1`. The agent sees and filters on the display names it recognizes from the SharePoint UI — the connector translates to internal names on the wire and back in the results.
* **Document libraries and hidden system lists are excluded.** Libraries belong to the files connector; hidden lists can be opted back in with `include_hidden`.
Queries map 1:1 to Graph list-item calls with OData:
```json theme={null}
{"list": "2017_Expense_Data",
"filter": "Category ne 'Total Expenses' and 2017 gt 1",
"select": ["Category", "2017"],
"orderby": "Modified desc",
"limit": 1000}
```
The connector sends the `Prefer: HonorNonIndexedQueriesWarningMayFailRandomly` header so filters work on non-indexed columns, and follows `@odata.nextLink` paging up to the row cap.
## Before you start
The prerequisites are the same as for [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive): a **Microsoft Entra ID app registration** with a client secret, admin consent for the Graph permissions, and your Bag of words base URL for the OAuth redirect URI. If you already registered an app for the SharePoint files connector, **reuse it** — SharePoint Lists needs only `Sites.Read.All`, which that app already has.
| Access path | Graph permission needed |
| :----------------------------- | :-------------------------------------------------------------------------------------- |
| Per-user sign-in (recommended) | `Sites.Read.All` **delegated**, plus `User.Read`, `openid`, `profile`, `offline_access` |
| App-only catalog and queries | `Sites.Read.All` **application** permission with admin consent |
Unlike Graph *file* reads, Graph *list* reads work app-only on standard tenants — so a service-principal-only connection can index and query lists without any user signing in, as long as the application permission is granted. With delegated sign-in, each user sees exactly the lists and items their own account can see.
## Connect in Bag of words
Go to **Data Sources → Add data source** and pick **SharePoint Lists**.
### Config fields
| Field | Required | Default | Notes |
| :--------------- | :------- | :------ | :-------------------------------------------------------------------------------------------------------------------------------------------------- |
| `site_url` | Yes | — | Full site URL, e.g. `https://contoso.sharepoint.com/sites/Finance`. |
| `lists` | No | `*` | `*` exposes **all** qualifying lists on the site. Or a comma-separated set of list names to restrict the connection, e.g. `Expenses 2025, Vendors`. |
| `include_hidden` | No | `false` | Also expose lists SharePoint marks as hidden (site plumbing). Usually off. |
| `max_items` | No | `20000` | Safety cap on how many list items a single query may fetch. |
### Authentication modes
Identical to the SharePoint files connector, backed by the same Entra app registration:
* **Entra ID App (Service Principal)** — `tenant_id`, `client_id`, `client_secret` (with optional `oauth_client_id` / `oauth_client_secret` overrides). Backs both the app-only path and the per-user sign-in flow.
* **Sign in with Microsoft** — each user clicks **Connect** and completes the authorization-code flow; queries then run as that user. Entra SSO deployments also get OBO auto-provisioning, so users who log in with Microsoft are connected automatically.
See [Authentication and access](/data-sources/authentication) for shared vs per-user policies.
## Troubleshooting
SharePoint rejects `$filter`/`$orderby` on non-indexed columns once a list crosses the 5,000-item view threshold, even with the Prefer header. Either index the column in SharePoint (List settings → Indexed columns), or drop the filter and let the agent filter in pandas — the connector's error message tells the agent to do exactly that.
Document libraries are excluded by design — use the SharePoint files connector for those. Hidden lists need `include_hidden`. If the connection has a `lists` scope, the list name must match one of the configured names.
With a user-required connection and no `Sites.Read.All` application permission, the admin-side crawl legitimately finds nothing — the catalog populates per user after each user signs in with Microsoft.
Hidden and read-only system columns are filtered out of the catalog on purpose. Person and lookup columns return display values as strings.
## Related
* [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) — the same site's document libraries, as files.
* [Business applications](/data-sources/connectors/business-apps) — other table-shaped application connectors (Salesforce, ServiceNow, NetSuite).
* [Authentication and access](/data-sources/authentication) — shared vs per-user credentials and OAuth.
# SharePoint and OneDrive
Source: https://docs.bagofwords.com/data-sources/connectors/sharepoint-onedrive
Read files from a SharePoint document library or from each user's own OneDrive via Microsoft Graph
Both connectors read files through **Microsoft Graph** and expose them to the agent as a file catalog — Excel, CSV and documents become searchable and readable. They differ in **whose** files they reach:
* **SharePoint** connects to one site and document library that an admin picks. Everyone who can use the connection sees the same library.
* **OneDrive** connects to *each user's own* drive. There is nothing for an admin to pick, and no shared catalog exists.
The SharePoint and OneDrive connectors are part of the **Enterprise Edition**.
## Shared vs per-user catalogs
This is the most important difference between the two, and it changes what you configure.
| | SharePoint | OneDrive |
| :------------------ | :-------------------------------------------------------------------- | :------------------------------------------------------------------------ |
| Catalog ownership | `shared` | `per_user` |
| What the catalog is | The site + library + folder the admin configured | Each signed-in user's own drive |
| Config fields | `site_url`, `drive_name`, `folder_path`, `include_globs`, `recursive` | **None** |
| Who curates it | An admin indexes it once; per-user access filters that one catalog | Nobody — each user's drive *is* their catalog, and no two users share one |
Because OneDrive's catalog is per user, there is no admin-side file list to index or curate, and no "select which files the agent may use" step. Each user connects their own account and the agent works against that drive. See [User context and per-user data](/data-sources/user-context).
## How it works
Bag of words calls Microsoft Graph (`https://graph.microsoft.com/v1.0`) to resolve the site and drive, walk folders, search, and download file content. `.csv`, `.tsv`, `.xlsx` and `.xls` are parsed into tables; `.pdf`, `.docx` and `.pptx` are text-extracted; plain-text formats are read as text.
For SharePoint, `folder_path` is the server-side base — the efficient way to scope a connection — and `include_globs` is the access boundary on top of it. A file outside the globs is **denied**, not merely hidden, including for drive-wide search results.
Graph requires **delegated** (per-user) authentication for file reads on most tenants. The service principal reliably enumerates SharePoint sites and drives, but app-only file reads can be refused depending on tenant policy. Plan on per-user sign-in for the read path.
## Before you start
* A **Microsoft Entra ID app registration** in your tenant, with a client secret.
* A Global Administrator (or Privileged Role Administrator) who can **grant admin consent** for the Graph permissions.
* Your Bag of words base URL, for the OAuth redirect URI.
* For SharePoint: the full site URL, and the name of the document library if it is not the site's default **Documents**.
## Step 1 — Register an Entra ID application
In the [Azure Portal](https://portal.azure.com) → **Microsoft Entra ID** → **App registrations** → **New registration**.
Name it (e.g. `Bag of words - Microsoft 365`). Under **Supported account types**, choose **Accounts in this organizational directory only** unless you specifically need multi-tenant.
From the app's **Overview** page, copy the **Directory (tenant) ID** and the **Application (client) ID**.
**Certificates & secrets** → **New client secret**. Copy the **secret value** immediately — it is shown once.
Under **Authentication** → **Add a platform** → **Web**, add:
```text theme={null}
https:///api/connections/oauth/callback
```
Replace `` with your Bag of words base URL.
## Step 2 — Grant Microsoft Graph permissions
Under **API permissions** → **Add a permission** → **Microsoft Graph**, add the permissions for the connectors you plan to use, then click **Grant admin consent for \**.
| Connector | Delegated permissions requested at sign-in |
| :--------- | :------------------------------------------------------------------------------------- |
| SharePoint | `Files.Read.All`, `Sites.Read.All`, `User.Read`, `openid`, `profile`, `offline_access` |
| OneDrive | `Files.Read.All`, `User.Read`, `openid`, `profile`, `offline_access` |
If you also want the shared service principal to enumerate SharePoint without a signed-in user, add the corresponding **Application** permissions (`Sites.Read.All`, `Files.Read.All`) and grant admin consent for those too — the app-only token is issued for `https://graph.microsoft.com/.default`, so it carries exactly the application permissions the app has been granted.
Without admin consent, sign-in fails or returns a token with no usable Graph scopes. `offline_access` is required for the refresh token — omit it and users have to re-authenticate whenever the access token expires.
## Connect in Bag of words
Go to **Data Sources → Add data source** and pick **SharePoint** or **OneDrive**.
### SharePoint fields
| Field | Required | Default | Notes |
| :-------------- | :------- | :------ | :---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `site_url` | Yes | — | Full site URL, e.g. `https://contoso.sharepoint.com/sites/Finance`. |
| `drive_name` | No | — | Document library (drive) name on the site. Blank uses the site's default **Documents** library. |
| `folder_path` | No | — | Folder within the drive to scope the connection, e.g. `Reports/2025`. This is the server-side base; blank means the drive root. |
| `include_globs` | No | — | Glob patterns relative to `folder_path`, e.g. `Reports/**/*.xlsx`, `**/*.pdf`, `2025/**`. When set, only matching files are visible **and** readable. |
| `recursive` | No | `false` | Walk subfolders. Off by default because the admin usually points at one specific folder. |
`allowed_extensions` is **deprecated** — use `include_globs` with a pattern like `**/*.xlsx` instead.
### OneDrive fields
OneDrive has **no config fields**. Each user's own drive is the catalog, so there is nothing to scope on the admin side. You supply the app registration credentials and the connector does the rest. Internally, OneDrive walks recursively by default, since a user's drive root is almost always folders rather than loose files.
## Authentication modes
Both connectors offer the same two modes.
### Entra ID App (Service Principal) — `service_principal`
Scopes: **system** and **user**. This is where the app registration lives. The same credentials back both the app-only token (client credentials) and the per-user sign-in flow.
| Field | Required | Notes |
| :-------------------- | :------- | :--------------------------------------------------------------------------------- |
| `tenant_id` | Yes | Directory (tenant) ID. |
| `client_id` | Yes | Application (client) ID of the app registration. |
| `client_secret` | Yes | The client secret value from Step 1. |
| `oauth_client_id` | No | A separate app registration client ID for user sign-in. Falls back to `client_id`. |
| `oauth_client_secret` | No | Secret for that separate app. Falls back to `client_secret`. |
### Sign in with Microsoft — `oauth`
Scope: **user** only, and it has no fields — each user clicks **Connect** and completes the Microsoft authorization-code flow against the app registration above. Discovery and reads then run as that user, so people see only what their own account can see.
For OneDrive this is the only meaningful path: the drive being read is the signed-in user's own. For SharePoint it is the recommended read path, because Graph enforces the library's own permissions per user.
See [Authentication and access](/data-sources/authentication) for how to require user sign-in on a connection.
## Troubleshooting
The Graph permissions in Step 2 were added but admin consent was never granted. Grant it in **API permissions**, then have the user click **Connect** again.
The app registration must have `https:///api/connections/oauth/callback` registered as a **Web** platform redirect URI, matching your Bag of words base URL exactly, scheme and trailing path included.
Most tenants require delegated auth for Graph file downloads. Switch the connection to per-user sign-in, or grant the `Files.Read.All` **Application** permission with admin consent.
`include_globs` is the access boundary and is matched relative to `folder_path`. A path outside the patterns is denied by design. Also check `recursive` if the file is in a subfolder.
`offline_access` is missing from the granted delegated permissions, so no refresh token is issued.
## Related
* [SharePoint Lists](/data-sources/connectors/sharepoint-lists) — query the same site's SharePoint **lists** as tables (typed columns, OData filters) instead of its libraries as files.
* [OneNote](/data-sources/connectors/onenote) — read Microsoft OneNote notebooks over the same Entra app registration.
* [Gmail and Outlook Mail](/data-sources/connectors/mail) — the same Entra app registration also backs the Outlook Mail connector.
* [Google Drive](/data-sources/connectors/google-drive) — the Google equivalent of OneDrive.
* [Files and Directories](/data-sources/connectors/files-and-directories) — for shares mounted on the backend host instead.
# SharePoint Server (on-prem)
Source: https://docs.bagofwords.com/data-sources/connectors/sharepoint-server
Read and search on-premises SharePoint Server document libraries over the REST API with NTLM or Kerberos — no Microsoft Graph or Entra app required
The SharePoint Server connector is part of the **Enterprise Edition**.
This connector reads document libraries from a **self-hosted SharePoint Server** farm over SharePoint's own REST API. It is separate from [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) and [SharePoint Lists](/data-sources/connectors/sharepoint-lists), which both go through Microsoft Graph and need an Entra app registration. Here there is no Graph and no app registration — the backend authenticates to the farm directly with Windows credentials or Kerberos.
The connection is **read-only**. The agent browses, searches, and reads documents; it never writes to SharePoint. Report attachments and saved queries live in Bag of words, not in the source library.
## What the agent sees
A searchable file catalog, scoped to what you configure:
* **Library scope** — all visible document libraries, one named library, or the site's default library. With all libraries, returned paths include the library name.
* **Folder scope** — a folder path, recursive or not, narrowed further with include globs and allowed extensions.
* **File handling** — CSV/TSV and XLS/XLSX load as dataframes; PDF, DOCX, PPTX and text files are extracted for reading; JSON is parsed; anything else can be downloaded as its original binary.
Scope is enforced on every read, including when a read is given an absolute server-relative path, and search hits outside the configured origin, site, library, folder or globs are rejected and re-authorized live.
Content search depends on the farm's own crawl. A newly uploaded document is matched by **filename** immediately, but its **contents** are only searchable once SharePoint's Search Service Application has crawled it — indexing the catalog in Bag of words does not trigger that crawl.
## Fields
| Field | Required | Default | Notes |
| :-------------------- | :------- | :------ | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `site_url` | Yes | — | Site URL including the `/sites/` path. **Not** the Central Administration URL. Must be reachable from the backend, and should match your SharePoint alternate access mappings. |
| `drive_name` | No | — | A single document library to expose. Blank uses the site's default library; `*` exposes every visible library. |
| `folder_path` | No | — | Restrict the catalog to a folder within the library. |
| `include_globs` | No | — | Glob patterns narrowing which files are cataloged. |
| `allowed_extensions` | No | — | Restrict the catalog to specific file extensions. |
| `recursive` | No | `true` | Walk subfolders beneath the configured folder. |
| `index_mode` | No | — | Index file metadata up front, or list live on demand. |
| `max_catalog_objects` | No | `5000` | Cap on cataloged files (max `50000`). Narrow the scope instead of raising this for very large libraries. |
| `max_file_size_mb` | No | `50` | Reject oversized downloads before parsing (max `250`), so files are never silently truncated. |
| `allow_http` | No | `false` | Permit unencrypted HTTP. An explicit escape hatch for an isolated test lab — use HTTPS with a trusted certificate everywhere else. |
## Authentication modes
**Windows credentials (NTLM) — `ntlm`** (the default; scopes: system and user)
| Field | Required | Notes |
| :--------- | :------- | :-------------------------------------------------------------------------------------------- |
| `username` | Yes | `DOMAIN\username` or `user@domain`. Use a read-only account scoped to the intended libraries. |
| `password` | Yes | That account's password. |
At **system** scope the whole connection uses one service account. At **user** scope each member supplies their own Windows account, so SharePoint applies that person's permissions — members who have not entered credentials are blocked rather than falling back to the service account.
Per-user NTLM is credential-based Windows authentication, **not** automatic single sign-on. Each member enters and tests their own domain username and password once.
**Kerberos service account — `kerberos`** (scope: system)
| Field | Required | Notes |
| :---------- | :------- | :-------------------------------------------------------- |
| `principal` | No | Optional service-account UPN, e.g. `svc_bow@EXAMPLE.COM`. |
Kerberos authenticates as the **service account**, not as the signed-in Bag of words user — it does not impersonate the caller, and end-user delegation is not implemented by this connector. Choose it for a single shared identity, not for per-person permissions.
The keytab is never uploaded through the connection form. A deployment owner mounts it read-only and points the backend at it (`krb5.conf` plus `KRB5_CLIENT_KTNAME`, or a ticket cache). The backend also needs the `kerberos` extra installed — the shipped Docker image already includes the MIT Kerberos runtime.
## Requirements on the SharePoint side
1. A site URL reachable from the backend, with alternate access mappings configured for it.
2. HTTPS with a trusted certificate. For a private CA, mount a CA bundle and set `REQUESTS_CA_BUNDLE` in the backend environment — certificate validation stays on.
3. A least-privilege account with read access to the selected site and libraries. No Domain Admin or SQL access is needed.
4. For content search: a Search Service Application with a working content source and crawl, and search URLs matching the configured access URL. Verify security trimming with both an allowed and a denied test user.
5. For Kerberos: Windows Integrated Authentication (Negotiate) on the web application, correct unique `HTTP/` SPNs for the IIS service identity, working AD DNS and realm configuration, synchronized clocks, and private backend access to the KDC. Kerberos here uses the **HTTP** SPN — not `MSSQLSvc`.
## Not supported
Arbitrary SharePoint lists (use [SharePoint Lists](/data-sources/connectors/sharepoint-lists)), site pages, attachments on list items, any form of write, and Microsoft Graph OAuth. Servers predating the ResourcePath REST API are unverified; the connector is validated against SharePoint Server Subscription Edition.
## Related
* [SharePoint and OneDrive](/data-sources/connectors/sharepoint-onedrive) — the Microsoft Graph equivalent for SharePoint Online and OneDrive.
* [SharePoint Lists](/data-sources/connectors/sharepoint-lists) — lists as queryable tables, over Graph.
* [Authentication and access](/data-sources/authentication) — shared vs per-user credentials across connectors.
# Sisense
Source: https://docs.bagofwords.com/data-sources/connectors/sisense
Connect Sisense data models and query ElastiCubes with SQL
Bag of words connects to a **Sisense** deployment, discovers every data model (ElastiCube or live model) the credential can reach, and queries them with **SQL**. Dashboards built on a model are attached to it as context, so the agent knows which reports a table already feeds.
The Sisense connector is part of the **Enterprise Edition**.
## How it works
1. Bag of words authenticates and obtains a bearer token.
2. It lists data models from the v2 API (`/api/v2/datamodels`), falling back to the v1 ElastiCubes API on older deployments.
3. For each model it reads the field list (`/api/datasources/{title}/fields`), grouping fields into tables and translating Sisense column type codes into readable types. Relationships defined in the model become foreign keys.
4. Dashboards are listed and indexed against the model they are built on.
5. Queries run as SQL against the model (`/api/datasources/{title}/sql`).
Each table is exposed as a schema entry named `Datamodel/Table` — for example `SalesModel/Customers`. Tables in the same model can be joined; the part after the `/` is the name to use inside the SQL itself.
The SQL endpoint does **not** apply Sisense row-level security. If a model relies on data security rules to restrict what people may see, treat the connection as having full access to that model and control visibility through table selection and [data source access settings](/data-sources/authentication) instead.
## Before you start
* The Sisense server URL, for example `https://sisense.company.com`, reachable from Bag of words.
* A Sisense account with access to the data models you want to expose, or a pre-issued API token for such an account.
* At least one data model the account can query — the connection test fails if the account sees none.
## Connect in Bag of words
Go to **Settings → Data Sources → Add data source → Sisense**. See [Connecting a data source](/data-sources/connecting) for the general flow.
| Field | Required | Default | Notes |
| :----- | :------- | :------ | :------------------------------------------------------ |
| `host` | Yes | — | Sisense server URL, e.g. `https://sisense.company.com`. |
**Test Connection** runs three checks in order: it authenticates, lists the data models, and then runs a trivial query against the first model. Each stage reports separately, so a failure tells you whether the problem is the credential, visibility of models, or query permission on a model.
## Authentication modes
| Mode | Scope | Fields |
| :---------------------- | :------------------ | :---------------------------------- |
| **Username / Password** | `system` and `user` | `username`, `password`, `api_token` |
All three fields are optional individually, but you must supply one of the two combinations:
| Field | Notes |
| :---------- | :------------------------------------------------------------------------------------------------------------------------- |
| `username` | Sisense username (email). Leave blank if you are using an API token. |
| `password` | Sisense password. Leave blank if you are using an API token. |
| `api_token` | A pre-existing Sisense API bearer token. **If provided, `username` and `password` are ignored** and no login call is made. |
Because the mode is available at both scopes, you can configure **one shared service account** for the workspace (`system`), or have **each user supply their own Sisense credential** (`user`). Per-user credentials on a connector like this require Enterprise — see [Authentication](/data-sources/authentication).
## Troubleshooting
If you filled in `api_token`, the username and password are not consulted at all — check the token first. Otherwise verify the username is the account's email address and that `host` points at the Sisense web application, not a load-balancer path that strips `/api`.
The credential authenticated but sees nothing. Give the account access to at least one ElastiCube or live model. On older deployments the v2 datamodels API may be unavailable; Bag of words then falls back to the v1 ElastiCubes API, and the account needs visibility there.
Listing a model and querying it are separate permissions. The test runs a minimal query against the first model it finds — if that step fails, grant the account query access on the model.
The field lookup for that model failed and it was skipped so the rest of the catalog could finish indexing. This is usually a permission gap on that specific model, or a model whose build has never completed.
Sisense SQL uses `LIMIT N`, not `TOP N`, and table names containing spaces must be bracketed, as in `[Order Details]`. Joins only work between tables that belong to the same data model.
# Snowflake
Source: https://docs.bagofwords.com/data-sources/connectors/snowflake
Connect a Snowflake warehouse so the agent can explore its schemas and run SQL
Bag of words connects to Snowflake with the standard Snowflake driver, reads the tables, views, and semantic views in the schemas you point it at, and runs SQL against a warehouse you choose. You can authenticate with a username and password, with **key pair (RSA) authentication** — the option most Snowflake accounts require once MFA is enforced on human users — or per-user with **Sign in with Snowflake** (OAuth), where each person signs in with their own Snowflake account and queries run under their own role and permissions.
## How it works
Bag of words opens a connection scoped to one `database` and one or more `schema` values, using the `warehouse` you specify for compute (and the `role` you specify, if any). During indexing it reads:
* **Tables and views** from `INFORMATION_SCHEMA`, including table and column comments where they exist.
* **Semantic views** — discovered with `SHOW SEMANTIC VIEWS` and described with `DESC SEMANTIC VIEW`. These are exposed to the agent alongside regular tables, and the agent knows to query them through the `SEMANTIC_VIEW()` function rather than as ordinary tables.
Schema names are normalized to uppercase, matching Snowflake's `INFORMATION_SCHEMA` behavior. Queries are read-only.
## Before you start
* A Snowflake **account identifier**, in the organization-account form (for example `ABCDEF-GHIJKL`). This is the identifier from your account URL, not the full hostname.
* A **warehouse** the connecting user can use, and a **database** to query.
* The names of the **schemas** you want indexed. One schema, or several as a comma-separated list.
* A user for Bag of words to connect as. A dedicated service user with a read-only role is the usual pattern.
* Network access from the Bag of words host to your Snowflake account. If your account restricts access by network policy, allow the Bag of words egress IP.
Create a dedicated role with `USAGE` on the warehouse, database, and schemas, plus `SELECT` on the objects you want available, and grant it to the service user. Then set that role in the **Role** field so the connection can never see more than intended.
## Step 1 — Generate a key pair (key-pair auth only)
Skip this step if you are using a username and password.
Snowflake key-pair authentication uses a 2048-bit RSA key. You generate the pair yourself, register the **public** key on the Snowflake user, and paste the **private** key into Bag of words.
For an encrypted key (recommended — `openssl` prompts you for a passphrase):
```bash theme={null}
openssl genrsa 2048 | openssl pkcs8 -topk8 -inform PEM -v2 des3 -out rsa_key.p8
```
For an unencrypted key:
```bash theme={null}
openssl genrsa 2048 | openssl pkcs8 -topk8 -inform PEM -nocrypt -out rsa_key.p8
```
Either form works. Bag of words accepts a PKCS#8 PEM private key and decrypts it with the passphrase you provide.
```bash theme={null}
openssl rsa -in rsa_key.p8 -pubout -out rsa_key.pub
```
If the private key is encrypted, `openssl` asks for the passphrase here.
Open `rsa_key.pub`, and copy the body **without** the `-----BEGIN PUBLIC KEY-----` and `-----END PUBLIC KEY-----` lines and without line breaks. Then, as a user with `SECURITYADMIN` (or ownership of the target user):
```sql theme={null}
ALTER USER BOW_SVC SET RSA_PUBLIC_KEY='MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8A...';
```
Verify it registered:
```sql theme={null}
DESC USER BOW_SVC;
-- the RSA_PUBLIC_KEY_FP property should now hold a fingerprint
```
`rsa_key.p8` is a credential. Store it in your secret manager and delete any working copies. Never register the private key with `ALTER USER` — only the public key goes to Snowflake.
## Step 2 — Create an OAuth security integration (per-user sign-in only)
Skip this step unless you want **Sign in with Snowflake** — per-user OAuth where each person queries as themselves.
Snowflake acts as its own OAuth authorization server: you register Bag of words as a client with a **security integration**, then save the integration's client ID and secret on the connection.
As `ACCOUNTADMIN` (or a role with `CREATE INTEGRATION`):
```sql theme={null}
CREATE SECURITY INTEGRATION BOW_OAUTH
TYPE = OAUTH
ENABLED = TRUE
OAUTH_CLIENT = CUSTOM
OAUTH_CLIENT_TYPE = 'CONFIDENTIAL'
OAUTH_REDIRECT_URI = 'https:///api/connections/oauth/callback'
OAUTH_ISSUE_REFRESH_TOKENS = TRUE
OAUTH_REFRESH_TOKEN_VALIDITY = 7776000; -- 90 days, the maximum
```
The redirect URI must match your Bag of words host exactly and must use HTTPS — for a local or non-TLS deployment, add `OAUTH_ALLOW_NON_TLS_REDIRECT_URI = TRUE`.
```sql theme={null}
SELECT SYSTEM$SHOW_OAUTH_CLIENT_SECRETS('BOW_OAUTH');
```
Copy `OAUTH_CLIENT_ID` and one of the `OAUTH_CLIENT_SECRET` values — they go into the connection's **OAuth Client ID** and **OAuth Client Secret** fields in Step 3.
A Snowflake OAuth session cannot use `ACCOUNTADMIN` or `SECURITYADMIN` (they are on the integration's blocked-roles list by default). With the connection's **Role** field blank, each token is bound to the user's **default role**, so that role needs `USAGE` on the warehouse, database, and schemas. If you set a **Role** on the connection, Bag of words requests the `session:role:` scope so the token authorizes exactly that role — users still need the role granted to them.
`OAUTH_ISSUE_REFRESH_TOKENS = TRUE` is what lets Bag of words renew the short-lived access token (about 10 minutes) without asking the user to sign in again. When the refresh token itself expires — 90 days at most — the user reconnects.
## Step 3 — Add the connection in Bag of words
Go to **Data Sources → Add data source → Snowflake** and fill in the form.
| Field | Required | Default | Notes |
| :---------- | :------- | :------ | :--------------------------------------------------------------------------------------------------------------------------------------------- |
| `account` | Yes | — | Account identifier, for example `ABCDEF-GHIJKL`. Not the full `.snowflakecomputing.com` hostname. |
| `warehouse` | Yes | — | Warehouse used for compute on every query. |
| `database` | Yes | — | Database to connect to. |
| `schema` | Yes | — | Schema to index. Accepts a **comma-separated list** (`SALES, MARKETING, FINANCE`); the first entry is used as the connection's default schema. |
| `role` | No | — | Optional Snowflake role to activate for the connection. Leave blank to use the user's default role. |
Then choose an authentication method (below), click **Test Connection**, and select the tables the agent may use.
## Authentication modes
Snowflake supports three modes. Username/password and key pair can be used as a **shared** credential for the whole workspace (system scope) or as a **per-user** credential where each person supplies their own (user scope). **Sign in with Snowflake** is per-user only: each person authorizes through Snowflake's own sign-in and consent screens, and their token is stored and refreshed for them.
| Field | Required | Notes |
| :--------- | :------- | :-------------------- |
| `user` | Yes | Snowflake login name. |
| `password` | Yes | The user's password. |
Straightforward, but not usable for a user on which your account enforces MFA. For service accounts, prefer key pair.
| Field | Required | Notes |
| :----------------------- | :------- | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `user` | Yes | Snowflake login name the public key is registered on. |
| `private_key_pem` | Yes | The **full** PEM private key, including the `-----BEGIN ... PRIVATE KEY-----` and `-----END ... PRIVATE KEY-----` lines and the newlines between them. Paste the contents of `rsa_key.p8`. |
| `private_key_passphrase` | No | Passphrase that decrypts the key. Leave blank when the key was generated with `-nocrypt`. |
Bag of words parses the PEM, decrypts it with the passphrase if one is given, and hands the key to the Snowflake driver. No passphrase is sent to Snowflake.
Per-user only, and requires the security integration from Step 2. Users fill in **no fields** — clicking **Connect** on the data source sends them to Snowflake's sign-in (password, MFA, and the consent screen), and Bag of words stores and auto-refreshes their token.
The integration's client belongs on the connection's **system credentials**, next to the shared username/password or key pair:
| Field | Required | Notes |
| :-------------------- | :------- | :--------------------------------------------------------- |
| `oauth_client_id` | Yes | `OAUTH_CLIENT_ID` from `SYSTEM$SHOW_OAUTH_CLIENT_SECRETS`. |
| `oauth_client_secret` | Yes | An `OAUTH_CLIENT_SECRET` value from the same call. |
Queries then run as the signed-in person: their Snowflake user, their role (the default role, or the connection's **Role** via the `session:role` scope), their permissions. The shared credential is still used for admin-side indexing and background catalog refresh.
To force everyone to use their own account, enable **Require user authentication** on the connection. With OAuth configured as the only user auth mode, each person's **Connect** click goes straight to Snowflake's sign-in page and back.
Using per-user credentials on a database connector — every person authenticating as themselves rather than through one shared login — requires an Enterprise license. See [Authentication](/data-sources/authentication).
## Troubleshooting
The PEM did not parse. Check that you pasted the whole file including both `-----BEGIN`/`-----END` lines, that no lines were reflowed or truncated, and that the passphrase field matches how the key was generated. An encrypted key with a blank passphrase, or an unencrypted key with a passphrase set, both fail here.
The public key registered on the Snowflake user does not match the private key you supplied. Re-derive the public key with `openssl rsa -in rsa_key.p8 -pubout`, re-run `ALTER USER ... SET RSA_PUBLIC_KEY='...'`, and confirm `DESC USER` shows a new `RSA_PUBLIC_KEY_FP`. Also confirm the `user` field is the Snowflake **login name**, not an email address, unless they are the same.
The role in use has no `USAGE` on the database or schema, or no `SELECT` on the objects. Check the `role` field — with it blank, the user's default role applies, which may be more restrictive than you expect. Also confirm the `schema` names are spelled as they appear in Snowflake; they are matched in uppercase.
The connecting role lacks `USAGE` on the warehouse named in the `warehouse` field, or the warehouse is suspended and the role cannot resume it. Grant `USAGE` (and `OPERATE` if auto-resume is off).
The connection is missing `oauth_client_id`/`oauth_client_secret`, or **Require user authentication** is off. Save the security integration's client ID and secret on the connection credentials and enable the toggle — OAuth is then added to the allowed sign-in methods automatically.
The `OAUTH_REDIRECT_URI` on the security integration must exactly match `https:///api/connections/oauth/callback` — scheme, host, and path. Snowflake also refuses non-HTTPS redirect URIs unless the integration sets `OAUTH_ALLOW_NON_TLS_REDIRECT_URI = TRUE`.
`ACCOUNTADMIN` and `SECURITYADMIN` are blocked for OAuth sessions by default, so a user whose default role is one of those cannot query until a working role is set. And if the connection pins a **Role** the user does not hold, the `session:role` scope fails — grant the role, or clear the field so each user's default role applies. Users must reconnect after their default role or grants change, since the token is bound to the role it was issued for.
## Related
* [Connecting data sources](/data-sources/connecting)
* [Authentication](/data-sources/authentication)
* [SQL databases](/data-sources/connectors/databases)
# Microsoft SQL Server
Source: https://docs.bagofwords.com/data-sources/connectors/sql-server
Connect on-prem or cloud SQL Server, with a SQL login, service-account Kerberos, or per-user Kerberos SSO
Bag of words connects to **Microsoft SQL Server** over ODBC, reads the tables, views, and columns in the schemas you point it at, and runs read-only T-SQL. Beyond the usual SQL login it supports **Kerberos (Windows Integrated)** authentication as the app's service account, and **Kerberos SSO**, where every query runs under the signed-in user's own Active Directory identity through constrained delegation.
The connector's registry type is the uppercase string `MSSQL`. You will see it under **Microsoft SQL Server** in the data source picker.
## How it works
Bag of words connects with the **Microsoft ODBC Driver for SQL Server** (version 18 by default, 17 available for older servers), reads table and column metadata from the database's catalog views, and issues `SELECT` statements at query time. If the enriched metadata read fails on your server it falls back to a basic table and column listing.
Scope the connection with `database` and, optionally, `schema` — which accepts a comma-separated list, so one connection can cover several schemas.
Authentication happens in one of three shapes:
| Auth mode | Registry key | Scope | Identity SQL Server sees |
| :--------------------------------- | :------------------- | :--------------------- | :----------------------------------- |
| Username / Password | `userpass` | Shared **or** per-user | A SQL login |
| Kerberos (Windows Integrated) | `kerberos` | Shared only | The app's AD **service account** |
| Kerberos SSO (per-user delegation) | `kerberos_delegated` | Per-user only | **The signed-in user's** AD identity |
Per-user authentication on a database connector requires an Enterprise license. See [Authentication](/data-sources/authentication).
## Connect in Bag of words
Go to **Data Sources → Add data source → Microsoft SQL Server**.
| Field | Required | Default | Notes |
| :------------------ | :------- | :------ | :--------------------------------------------------------------------------------------------- |
| `host` | Yes | — | Server hostname. Under either Kerberos mode this **must be the FQDN** — see the warning below. |
| `port` | No | `1433` | TCP port. |
| `database` | Yes | — | Database to connect to. |
| `schema` | No | — | Schema to index, or a comma-separated list. Leave blank to index everything visible. |
| `odbc_driver` | No | `18` | ODBC driver major version — `17` or `18` only. Use `17` for SQL Server 2008 compatibility. |
| `encrypt` | No | `true` | Encrypt the connection. Disable only for a SQL Server 2008-era instance with no TLS support. |
| `additional_params` | No | — | Extra ODBC keywords passed through as-is, for example `ApplicationIntent=ReadOnly`. |
`additional_params` cannot weaken the connection. Security-relevant keywords are owned by Bag of words and any attempt to set them here is silently ignored: `Driver`, `Server`, `Database`, `UID`, `PWD`, `Encrypt`, `TrustServerCertificate`, `Trusted_Connection`, `Authentication`, `Integrated Security`, and `APP`. Use it for behavioral hints like read-intent routing, not to change how the connection authenticates or encrypts.
Under either Kerberos mode the ODBC driver derives the target service principal name as `MSSQLSvc/:` from what you type in `host`, and this **cannot be overridden**. Connect by the exact FQDN the SPN is registered for — an IP address or an unregistered CNAME produces `Cannot generate SSPI context`.
***
## Option A — SQL login (`userpass`)
The default. Nothing to configure outside the product.
| Field | Required | Notes |
| :--------- | :------- | :--------------------------------------------------------------------------- |
| `user` | No | SQL login name. Leave blank for anonymous database access. |
| `password` | No | The login's password. Leave blank for anonymous access or an empty password. |
This mode can be used as one shared credential for the whole workspace, or per-user, where each person saves their own SQL login. Grant the login read-only rights — `db_datareader` on the target database, or explicit `GRANT SELECT` on the approved schemas.
***
## Option B — Kerberos (Windows Integrated)
All queries authenticate as **one Active Directory service account**. Bag of words still enforces its own access control on top; SQL Server sees a single Windows login.
This mode requires setup by both your AD/DBA team and whoever operates the Bag of words host.
### Before you start
* An AD **service account** for the app, for example `svc-bow@CORP.EXAMPLE.COM`, with AES key types enabled ("This account supports Kerberos AES 128/256 bit encryption").
* SQL Server's own SPN registered — `setspn -L ` should list `MSSQLSvc/:1433`. This is usually automatic.
* The ability to mount files and set environment variables on the Bag of words host.
* NTP or chrony running on the host. Kerberos fails above **5 minutes** of clock skew.
### Step 1 — Create the keytab (AD team)
On a domain controller or admin workstation:
```text theme={null}
ktpass /princ svc-bow@CORP.EXAMPLE.COM /mapuser svc-bow /pass * ^
/crypto AES256-SHA1 /ptype KRB5_NT_PRINCIPAL /out svc-bow.keytab
```
### Step 2 — Create the SQL Server login (DBA)
```sql theme={null}
CREATE LOGIN [CORP\svc-bow] FROM WINDOWS;
-- then, in the target database, the minimum the app needs:
-- ALTER ROLE db_datareader ADD MEMBER [CORP\svc-bow];
-- or explicit GRANT SELECT on the approved schemas (recommended)
```
Bag of words only ever issues `SELECT`, so read-only rights are sufficient.
### Step 3 — Configure Kerberos on the Bag of words host
The Docker image already ships `krb5-user`, `libgssapi-krb5-2`, and `msodbcsql18`. You mount two files and set one environment variable.
```yaml theme={null}
# docker-compose override (or the Kubernetes equivalent)
services:
bagofwords:
volumes:
- ./krb5.conf:/etc/krb5.conf:ro
- ./svc-bow.keytab:/etc/bagofwords/svc-bow.keytab:ro # readable by the 'app' user
environment:
# GSSAPI initiates from the keytab automatically — no kinit cron needed.
KRB5_CLIENT_KTNAME: /etc/bagofwords/svc-bow.keytab
```
A minimal `/etc/krb5.conf`:
```ini theme={null}
[libdefaults]
default_realm = CORP.EXAMPLE.COM
dns_lookup_kdc = true
forwardable = true
[domain_realm]
.corp.example.com = CORP.EXAMPLE.COM
corp.example.com = CORP.EXAMPLE.COM
```
Keep `forwardable = true`. It is required for per-user SSO (Option C), and harmless otherwise.
Smoke-test from inside the container before touching the app:
```bash theme={null}
kinit -kt /etc/bagofwords/svc-bow.keytab svc-bow@CORP.EXAMPLE.COM && klist
```
### Step 4 — Configure the connection
Create or edit the SQL Server connection and pick **Kerberos (Windows Integrated)** as the authentication method.
| Field | Required | Default | Notes |
| :------------------- | :------- | :------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `use_kerberos` | No | `true` | Authenticate with the app's Kerberos identity instead of a SQL login. |
| `kerberos_principal` | No | — | Client principal to authenticate as, e.g. `svc-bow@CORP.EXAMPLE.COM`. Requires a matching keytab entry. **Leave blank** to use the default credential cache from `KRB5_CLIENT_KTNAME` — set it only when the keytab holds several principals. |
Verify from SQL Server that the connection really is Kerberos:
```sql theme={null}
SELECT auth_scheme FROM sys.dm_exec_connections WHERE session_id = @@SPID;
-- expect: KERBEROS
```
***
## Option C — Kerberos SSO (per-user delegation)
With per-user SSO, queries run as **the signed-in user's AD identity**. No password or token is collected from the user. Bag of words performs *protocol transition* (**S4U2Self** — "issue me a ticket for user X to myself", which needs only the user's UPN) and *constrained delegation* (**S4U2Proxy** — exchange that ticket for one to the SQL Server SPN). SQL-side permissions, row-level security, and auditing all resolve per user.
This builds **on top of** Option B: the service-account Kerberos setup must already be working, because the service identity is still used for schema indexing.
### Additional AD prerequisites
Delegation is configured on the **app's service account**. This is the part your AD team has to approve.
```text theme={null}
setspn -S bow/apphost CORP\svc-bow
```
The KDC only issues an S4U2Self evidence ticket to an account that is itself a service — that is, one that has an SPN.
**Classic KCD (single domain)** — in Active Directory Users and Computers → `svc-bow` → the **Delegation** tab:
1. Select **"Trust this user for delegation to specified services only"**.
2. Select **"Use any authentication protocol"**.
3. Add the SQL Server's `MSSQLSvc/:1433` SPN(s) to the allowed list (this writes `msDS-AllowedToDelegateTo`).
**"Use any authentication protocol" is required.** With "Kerberos only" selected, delegation fails with `KDC_ERR_BADOPTION` — protocol transition is exactly what that setting disables.
**Or resource-based constrained delegation**, which works across domains. On the SQL Server's service account:
```powershell theme={null}
Set-ADUser -PrincipalsAllowedToDelegateToAccount svc-bow
```
Per user or, more practically, per AD group:
```sql theme={null}
CREATE LOGIN [CORP\bi-analysts] FROM WINDOWS;
-- then grant that group read access in the target database
```
The SQL Server host must be **domain-joined** (SSSD or winbind) so it can resolve AD users to SIDs. Verify with `id DOMAIN\user` before creating logins.
Members of **Protected Users**, and accounts flagged **"Account is sensitive and cannot be delegated"**, cannot be impersonated at all. Those people need a personal SQL login (Option A) instead.
Smoke-test the whole AD chain from the container before enabling anything in the app:
```bash theme={null}
kinit -kt /etc/bagofwords/svc-bow.keytab svc-bow@CORP.EXAMPLE.COM
kvno -U jdoe@corp.example.com -P MSSQLSvc/sqldwh01.corp.example.com:1433
```
If `kvno` succeeds, delegation is correctly configured.
### Configure the connection
Per-user delegation needs the `gssapi` Python bindings. The default Dockerfile installs them (`uv sync --extra kerberos`). Service-account Kerberos (Option B) does not need them — the ODBC driver talks to libgssapi directly — so a build without the extra will pass Option B and fail here.
Follow Option B first. The system identity is still what indexes the schema.
On a Kerberos system-auth connection this defaults the allowed per-user modes to **Kerberos SSO**, so per-user delegation becomes automatic with no action from users — nobody has to click **Connect** or enter anything.
The per-user mode's fields:
| Field | Required | Default | Notes |
| :--------------------- | :------- | :------ | :------------------------------------------------------------------------------------------------------------------------- |
| `use_kerberos` | No | `true` | Queries run under the user's own AD identity via constrained delegation. |
| `kerberos_impersonate` | No | — | The user's AD user principal name, e.g. `jdoe@corp.example.com`. **Leave blank** to use their Bag of words login identity. |
The UPN is taken from the user's Bag of words login identity — Entra ID / OIDC `preferred_username` or `upn`, LDAP, or the local email address. If someone's email is not their AD UPN, they can save an explicit principal in `kerberos_impersonate` under the data source's user credentials.
### Optional environment variables
| Variable | Default | Purpose |
| :-------------------- | :-------------- | :-------------------------------------------------------------------------------------------------------------------------- |
| `KRB5_CLIENT_KTNAME` | — | Service keytab. Used both for the app's own identity and as the impersonator for S4U. **Required** for per-user delegation. |
| `BOW_KRB5_CCACHE_DIR` | `/tmp/bow_krb5` | Directory for per-user credential caches. Created with mode `0700`. |
### Operational notes
* **Ticket renewal is automatic.** Delegated tickets are cached per user and re-acquired from the keytab as they near expiry. There is nothing to schedule.
* **Indexing always runs as the service account**, since schema refresh has no user in context.
* `KRB5CCNAME` is process-global on Linux, so the credential-cache switch is serialized around the driver's connect handshake. Concurrent connects by different users queue for milliseconds; established connections are unaffected.
* Under integrated auth every user's ODBC connection string would otherwise be identical, since the identity comes from the credential cache rather than the string — which would let a shared pool hand user B a connection authenticated as user A. Bag of words binds a per-identity `APP=BagOfWords-` token into the string so each impersonated user gets its own pool bucket. Leaving unixODBC pooling off is still worth doing as defence in depth.
* If your SQL Server is **2022 or newer and Azure Arc-enabled**, Entra token authentication is an alternative to constrained delegation and may be easier to get approved than AD delegation changes.
***
## Troubleshooting
| Symptom | Likely cause |
| :-------------------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `Cannot generate SSPI context`, or SPNEGO errors | The SPN is missing, or `host` is an IP or an alias. Connect by the exact FQDN the `MSSQLSvc` SPN is registered for. |
| `KDC_ERR_BADOPTION` during delegation | Delegation is set to "Kerberos only" instead of **"Use any authentication protocol"**, or the `MSSQLSvc` SPN is missing from `msDS-AllowedToDelegateTo`. |
| `KRB5KRB_AP_ERR_SKEW` | Clock skew over 5 minutes. Fix NTP on the host. |
| `kinit` works in the container but the app does not | The keytab is not readable by the container's `app` user, or `KRB5_CLIENT_KTNAME` is unset. |
| Delegated auth fails for exactly one user | They are in **Protected Users** or flagged sensitive/cannot-be-delegated, or their email is not their AD UPN — save an explicit `kerberos_impersonate` principal for them. |
| `auth_scheme` reports `NTLM` or `SQL` | The connection fell back to another path. Confirm the connection is using a Kerberos auth mode. |
| Kerberos support requires the `gssapi` package | Per-user delegation needs the Kerberos extra installed in the image, plus a mounted `krb5.conf` and keytab. |
| TLS handshake failures against an old server | Set `odbc_driver` to `17`, and if the instance has no TLS at all, set `encrypt` to `false`. |
## Related
* [Connecting data sources](/data-sources/connecting)
* [Authentication](/data-sources/authentication)
* [SQL databases](/data-sources/connectors/databases)
# Tableau
Source: https://docs.bagofwords.com/data-sources/connectors/tableau
Connect Tableau published data sources and let the agent query them through VizQL
Bag of words connects to **Tableau Server** or **Tableau Cloud**, discovers the published data sources on a site, and queries them through the **VizQL Data Service** (Headless BI). Field-level descriptions, roles, and calculated-field formulas come from the **Metadata API**, so the agent knows what each field means before it asks a question.
The Tableau connector is part of the **Enterprise Edition**.
## How it works
Bag of words signs in to the site with a Personal Access Token and receives a session token, then:
1. Lists the **published data sources** on the site (paginated REST call), optionally narrowed to one project.
2. For each data source, reads its fields from **VizQL `read-metadata`** and enriches them from the **Metadata API** (`/api/metadata/graphql`) — descriptions, field roles, and calculated-field formulas.
3. Runs queries through **VizQL `query-datasource`**.
Each published data source becomes one schema entry named `Project/Data source` (for example `Finance/Superstore`).
Tableau is **not** queried with SQL. The agent builds VizQL requests — a list of fields with aggregation functions plus filters (`SET`, `TOP`, `QUANTITATIVE`, `DATE`) — and Tableau evaluates them against the published data source, applying the model's joins and calculations.
Re-indexing is incremental: data sources that are already in the catalog are rebuilt from the stored definition, and only new ones pay for a fresh metadata round-trip. Renames and project moves still propagate, because the listing is always re-read.
## Before you start
* The site's server URL and its **site name** (the `contentUrl` that appears in the browser address bar after `/site/`). The Default site has no site name.
* A **Personal Access Token** created by a user with access to the data sources you want to expose.
* The **Metadata API** enabled on the server. Tableau Cloud has it on; on Tableau Server a server administrator must enable metadata services, otherwise field descriptions and formulas come back empty.
* **VizQL Data Service** (Headless BI) available for the site — this is what executes queries.
* Network access from Bag of words to the Tableau server over HTTPS.
## Step 1 — Create a Personal Access Token
In Tableau, open the user menu → **My Account Settings** → **Personal Access Tokens** → **Create Token**.
The **token name** is what you enter as `pat_name` in Bag of words.
Copy the **token secret** immediately — Tableau shows it once. This is `pat_token`.
A Personal Access Token expires if it goes unused for the period set by your server administrator, and it inherits the permissions of the user who created it. Use a service account rather than a personal login for a shared connection.
The token can only see what its owner can see. Give that account at least **Connect/View** on the projects whose published data sources you want the agent to reach.
## Connect in Bag of words
Go to **Settings → Data Sources → Add data source → Tableau**. See [Connecting a data source](/data-sources/connecting) for the general flow.
| Field | Required | Default | Notes |
| :------------------- | :------- | :------ | :------------------------------------------------------------------------------------------------------------ |
| `server_url` | Yes | — | Base URL of the Tableau server, e.g. `https://10ax.online.tableau.com` or `https://tableau.example.com`. |
| `site_name` | No | — | Site `contentUrl`. Leave blank for the Default site. |
| `verify_ssl` | No | `true` | Verify the TLS certificate. Disable only for self-signed test servers. |
| `timeout_sec` | No | `30` | HTTP timeout for sign-in, metadata, and query calls. Raise it for slow on-prem servers or heavy data sources. |
| `default_project_id` | No | — | Restrict discovery to a single project ID. Leave blank to discover every published data source on the site. |
| `api_version` | No | `3.21` | Tableau REST API version. Change only for older on-prem Tableau Server that does not accept the default. |
**Test Connection** signs in, probes the VizQL health endpoint, and tries a query against the first data source it finds. A VizQL query endpoint that answers `404` does not fail the test — it is reported as a feature or permission gap while sign-in is confirmed working.
## Authentication modes
| Mode | Scope | Fields |
| :------------------------ | :------------------ | :---------------------- |
| **Personal Access Token** | `system` and `user` | `pat_name`, `pat_token` |
Supply both fields together — the token name alone cannot sign in.
Because the mode is available at both scopes, you can configure **one shared token** for the whole workspace (`system`), or have **each user supply their own token** (`user`) so Tableau applies that person's own content permissions and row-level security. Per-user credentials on a connector like this require Enterprise — see [Authentication](/data-sources/authentication).
## Troubleshooting
Check `site_name` first: it must be the site's `contentUrl`, not its display name, and must be blank for the Default site. Then confirm the token has not expired or been revoked. On older on-prem servers, lower `api_version` — a server that predates the requested REST API version rejects the sign-in call.
Neither VizQL `read-metadata` nor the Metadata API returned anything for it. Confirm the Metadata API is enabled on the server and that VizQL Data Service is available for the site, and that the token's owner has permission on that data source.
Types come from VizQL and descriptions, roles, and calculated-field formulas come from the Metadata API. If only the descriptive half is missing, the Metadata API is unavailable or the token's owner cannot read that content through it.
If `default_project_id` is set, only that project is discovered — clear it to see the whole site. Otherwise the token's owner simply cannot see the rest of the content.
Raise `timeout_sec`. VizQL evaluates the aggregation on the Tableau side, so a heavy data source can exceed the 30-second default.
# Timbr AI
Source: https://docs.bagofwords.com/data-sources/connectors/timbr
Connect a Timbr ontology and query concepts, relationships, and measures with SQL
Bag of words connects to a **Timbr** server, discovers the concepts, properties, relationships, and measures of an ontology, and queries them with SQL through the Timbr query API. Because Timbr is an ontology-based semantic layer, the agent gets business-level entities and pre-defined measures rather than raw physical tables.
The Timbr AI connector is part of the **Enterprise Edition**.
## How it works
All traffic goes to the Timbr REST API at `/timbr/api`, authenticated with an API key sent in the `x-api-key` header. Every query — including the ones used for discovery — is a `POST` to the API's `query/` endpoint against the ontology you configured.
Discovery is **permission-aware**:
1. Bag of words reads `timbr.sys_permissions` to find the schemas the key can `QUERY`.
2. For concepts it picks the richest accessible schema, preferring `dtimbr` over `etimbr` over `timbr`. If the permissions table lists no schema-level grants, it probes each schema directly instead and uses the first that answers.
3. Concepts come from `timbr.sys_concepts`; each one is described with `DESCRIBE concept` to build its columns.
4. If `vtimbr` is accessible, views are discovered from `timbr.sys_views` and their columns parsed from each view's definition.
Concepts and views are merged into one table list, each named with its schema prefix — `dtimbr.Customer`, `vtimbr.SalesSummary`. Within a concept:
* Properties whose name starts with `measure.` become **measures** (`role=measure`).
* Properties using bracket notation become **relationships**, exposed to the agent as foreign keys to the target concept.
* The internal columns `entity_id`, `entity_type`, and `entity_label` are hidden from the schema.
The `thing` root concept is excluded from discovery.
## Before you start
* A reachable Timbr server URL. The API base `/timbr/api` is appended automatically, so configure the server root.
* The exact **ontology (knowledge graph) name** — the connection test fails, listing the available ontologies, if the name does not match.
* A **Timbr API key** with `QUERY` permission on the schemas you want indexed: at least one of `dtimbr` / `etimbr` / `timbr` for concepts, and `vtimbr` if you want views. Relationship traversal is only available in `dtimbr`, so grant it when you want the agent to follow relationships instead of writing joins.
* If the Timbr server uses a certificate signed by an internal CA the backend host does not trust, turn off **Verify SSL**.
## Connect in Bag of words
Go to **Data Sources → Add data source → Timbr AI** and fill in the form.
| Field | Required | Default | Notes |
| :----------- | :------- | :------ | :------------------------------------------------------------------------------------------------------- |
| `host` | Yes | — | Timbr server URL, e.g. `https://mytimbr.example.com`. The `/timbr/api` base path is added automatically. |
| `ontology` | Yes | — | Name of the Timbr knowledge graph / ontology to connect to. |
| `verify_ssl` | No | `true` | Verify the TLS certificate when connecting. |
**Test Connection** lists the server's ontologies and checks that yours is among them, so a typo in the ontology name is caught before you save.
## Authentication modes
| Mode | Scope | Fields |
| :---------- | :------------------ | :-------------------------------------------------------- |
| **API Key** | System and per-user | `api_key` — Timbr API key, sent as the `x-api-key` header |
This is the only mode. Used at **system** scope, one admin-supplied key indexes and queries for everyone. Used **per-user**, each person supplies their own Timbr key, so Timbr's own permissions decide which schemas and concepts that person can see and query — and discovery for that user reflects it, because schema selection is driven by the key's `QUERY` grants.
Per-user authentication on database-style connectors requires an Enterprise license. See [Authentication](/data-sources/authentication).
## Querying
The agent writes SQL against the ontology, using the schema prefix shown for each table and backticks around schema and table names:
```sql theme={null}
SELECT category, SUM(`measure.total_sales`) AS total_sales
FROM `dtimbr`.`Product`
GROUP BY category
ORDER BY total_sales DESC
LIMIT 100
```
A few behaviors are worth knowing when you review what the agent produced:
* **Measures are preferred over manual aggregation.** If the ontology defines `measure.total_sales`, the agent uses it rather than summing a base column.
* **Views come first.** When a `vtimbr` view already covers the needed columns, the agent uses it — views are pre-optimized flat projections.
* **Relationships beat joins.** In `dtimbr`, related concepts are reached with bracket syntax rather than explicit joins, and the traversal can be multi-hop:
```sql theme={null}
SELECT name, `has_orders[Order].order_date` AS order_date
FROM `dtimbr`.`Customer`
LIMIT 100
```
* Table names are case-sensitive, schemas are never mixed within one query, and every query carries a `LIMIT`.
## Troubleshooting
The host and API key are fine; the ontology name does not match. The error lists the ontologies the key can see — copy one of those exactly.
The API key resolved but has access to nothing. Check the key's permissions in Timbr.
A network-level failure. Check that the backend host can reach the server URL, that the port is open, and — for an internal CA — whether **Verify SSL** needs to be off.
The key has no `QUERY` permission on any concept schema (`dtimbr`, `etimbr`, `timbr`) and none on `vtimbr`. Grant at least one concept schema; without it the ontology indexes as empty even though the connection succeeds.
The `DESCRIBE concept` call for that concept returned nothing or failed. The concept is still listed so it is visible in the catalog — check the key's permission on that specific concept in Timbr.
Relationship properties only exist in the `dtimbr` schema. If the key can only reach `etimbr` or `timbr`, concepts and measures index normally but no foreign keys appear, and the agent will fall back to explicit joins.
# Custom API Connections
Source: https://docs.bagofwords.com/data-sources/custom-api
Turn any REST API into agent tools by describing its endpoints
A **Custom API** connection lets the agent call any REST API without an MCP server in between. You describe the endpoints you want to expose; each one becomes a tool with a typed input schema, governed by the same approval policies as [MCP tools](/data-sources/mcp).
Use this when the service you need has a plain HTTP API and no MCP server — an internal microservice, a vendor REST API, a webhook receiver.
Custom API connections are **beta**. Field names may change.
## Connection fields
| Field | Required | Default | Notes |
| ----------- | -------- | ------- | ------------------------------------------------------------- |
| `base_url` | Yes | — | Every endpoint path is appended to this |
| `headers` | No | `{}` | Sent with every request; these override the generated headers |
| `endpoints` | No | `[]` | The endpoint definitions that become tools |
## Authentication
| Mode | Scope | Fields |
| ------------ | ------------------ | -------------------------------------------------------------------------------------------------------------- |
| None | Shared | — |
| Bearer token | Shared or per-user | `token` |
| API key | Shared or per-user | `api_key`, `api_key_header` (default `X-API-Key`) |
| OAuth app | Shared or per-user | `authorize_url`, `token_url`, `client_id`, `client_secret`, `scopes`, `audience`, `token_endpoint_auth_method` |
Bearer and OAuth modes send `Authorization: Bearer `. API-key mode sends the key in the header you name. Choosing OAuth makes the connection [per-user](/data-sources/authentication), so each person signs in with their own account — no Enterprise license required for tool connections.
## Defining endpoints
Each endpoint becomes one tool. Build them in the visual editor, or paste JSON directly:
```json theme={null}
{
"name": "get_customer",
"description": "Fetch a customer by id",
"method": "GET",
"path": "/customers/{id}",
"parameters": [
{ "name": "id", "in": "path", "type": "string", "required": true,
"description": "Customer id" },
{ "name": "include", "in": "query", "type": "string", "required": false,
"description": "Comma-separated related objects to include" }
]
}
```
| Key | Notes |
| ------------- | ------------------------------------------------------------------------------------------------------------------------------------ |
| `name` | Becomes the tool name the agent sees — make it descriptive |
| `description` | How the agent decides when to call it. Worth writing carefully |
| `method` | `GET`, `POST`, `PUT`, `PATCH`, or `DELETE` |
| `path` | Appended to `base_url`; `{name}` placeholders are filled from path parameters |
| `parameters` | Each has `name`, `in` (`query`, `path`, or `body`), `type` (`string`, `number`, `integer`, `boolean`), `required`, and `description` |
| `confirm` | Optional. `true` forces user confirmation; `false` opts out of the write-method default |
The `description` fields are not decoration — they are the entire basis on which the model chooses a tool and fills its arguments. Vague descriptions produce wrong calls.
## Write endpoints require confirmation by default
Any endpoint using `POST`, `PUT`, `PATCH`, or `DELETE` defaults to the `ask` policy: the agent proposes the call and a human confirms before anything happens. `GET` endpoints default to `allow`.
Override per endpoint with `confirm`, or change the policy later on the connection's tools view. The [three-layer policy model](/data-sources/mcp) applies here identically, including the rule that an admin `deny` cannot be overridden.
Think carefully before setting a destructive endpoint to `allow`. The agent will call it without asking.
## Responses
Bag of words classifies each response so the agent can use it well:
* A JSON array of objects is treated as **tabular** data and can be charted or joined with other results.
* Other JSON is passed through as structured data.
* Anything else is treated as text.
Requests time out after 30 seconds. `GET` and `DELETE` send parameters in the query string; other methods send a JSON body.
## Presets
One preset ships today — **X (Write)**, which exposes `POST /2/tweets` as a `create_post` tool with confirmation required. It is a good reference for how a write-capable connection should look.
## Adding a connection
1. Go to **Settings → Data Sources**, add a connection, and choose **Custom API**.
2. Enter the `base_url` and any static headers.
3. Choose an authentication mode.
4. Define your endpoints.
5. **Test**, then save. Each endpoint appears as a tool.
6. Review the tool policies, then attach the connection to an agent.
# MCP Connections
Source: https://docs.bagofwords.com/data-sources/mcp
Connect any MCP server, then govern which tools the agent may call and when
An **MCP connection** points Bag of words at a Model Context Protocol server. The server's tools become tools the agent can call during a conversation — creating a Monday item, searching Notion, opening a GitHub issue, querying an internal service.
This is the opposite direction from [the Bag of words MCP server](/using-bow/mcp), which lets Claude or Cursor query *your* data. Here, BOW is the client and the external server provides the tools.
MCP connections are **beta**. Field names may change.
## Presets vs custom servers
Bag of words ships one-click **presets** for common servers — Monday, Notion, Linear, Atlassian, GitHub, Sentry, Google Drive, and X. A preset fills in the server URL, transport, and OAuth settings; you just sign in. Presets create an ordinary MCP connection, so everything on this page applies to them too.
For anything else, add a **custom MCP server** and supply the details yourself.
## Connection fields
| Field | Required | Default | Notes |
| -------------------- | -------- | ------- | ------------------------------------------------------------------------------------------------------ |
| `server_url` | Yes | — | The MCP endpoint URL |
| `transport` | No | `sse` | `sse` or `streamable_http` — must match what the server speaks |
| `headers` | No | `{}` | Static headers sent on every request |
| `header_injection` | No | `[]` | Per-user identity headers — see [User context forwarding](/data-sources/user-context) |
| `metadata_injection` | No | `{}` | Per-user identity passed as tool arguments — see [User context forwarding](/data-sources/user-context) |
## Authentication
| Mode | Scope | Fields |
| ---------------------------- | ------------------ | -------------------------------------------------------------------------------------------------------------- |
| None | Shared | — |
| Bearer token | Shared or per-user | `token` |
| API key | Shared or per-user | `api_key`, `api_key_header` (default `X-API-Key`) |
| OAuth app | Shared or per-user | `authorize_url`, `token_url`, `client_id`, `client_secret`, `scopes`, `audience`, `token_endpoint_auth_method` |
| OAuth (dynamic registration) | Per-user | — (discovered from the server) |
**Dynamic client registration** is the easiest path when a server supports it: BOW discovers the server's OAuth metadata and registers itself automatically, so you supply no client ID or secret at all. Each user then signs in with their own account.
Dynamic registration is restricted to an allowlist of known hosts (the preset servers plus their auth domains). A custom server at an arbitrary URL must use an OAuth app, bearer token, or API key instead. This is a deliberate guard against server-side request forgery.
Choosing an OAuth mode makes the connection [per-user](/data-sources/authentication) automatically — each person signs in individually, and the agent calls tools as them. Per-user auth on MCP connections does **not** require an Enterprise license.
When testing an OAuth-based server before anyone has signed in, a `401` or `403` from the server counts as healthy — it proves the endpoint is reachable and challenging for credentials.
## OAuth MCP integration
OAuth connects an MCP server without turning a shared secret into a shared identity. Each user authorizes the connection with their own account, and tool calls use that user's token and the policies configured in Bag of words.
The setup flow is:
1. Add an MCP preset or enter a custom server URL and transport.
2. Choose **OAuth (dynamic registration)** when the server and host allow it, or provide the metadata for an **OAuth app**.
3. Save and discover the server's tools.
4. Each user selects **Sign in** and completes the provider's authorization flow.
5. Review tool policies and attach the connection to the appropriate agent.
6. The agent can call approved tools as the signed-in user; expired tokens are refreshed through the configured token endpoint.
Use dynamic registration for supported preset servers when you do not want to create and maintain a client ID. Use an OAuth app for a custom server where you control the authorization URL, token URL, client credentials, scopes, audience, and token-endpoint authentication method.
OAuth authenticates the caller; it does not bypass governance. Connection access, agent scope, tool policy, admin denies, and the MCP server's own authorization rules still apply to every call.
## Tool discovery
When you save the connection, Bag of words asks the server for its tools and stores each one with its name, description, and input schema. Re-run discovery any time from the connection's tools view — after the server ships new tools, for example.
Discovery never silently empties your tool list: if a refresh returns nothing (usually a transient outage), the existing tools and their policies are left untouched.
Servers that expose MCP **resources** as well as tools get those surfaced too, so the agent can list and read them.
## Tool policies
Every tool carries a policy that decides what happens when the agent wants to call it:
| Policy | Behavior |
| ------- | ------------------------------------------------------------------- |
| `allow` | Runs immediately |
| `ask` | The user must confirm before it runs |
| `deny` | Never runs |
| `auto` | A model judges each call and decides whether confirmation is needed |
Read-only tools generally default to `allow`. Anything that writes should be `ask` or `deny`.
Policies are resolved in three layers, most specific first:
1. **The user's own preference** for that tool
2. **The agent-level override** — the same tool can be `allow` on one data source and `ask` on another
3. **The connection default** set by the admin
with one hard rule: **an admin `deny` is absolute** and cannot be relaxed by an agent override or a user preference. Users can only make their own experience *stricter* than the admin's setting, never looser.
Admins set connection defaults and agent overrides; any user with access can set their own preference for a tool they use.
MCP tools can be turned off organization-wide with a single setting under **Settings → AI**. When disabled, no MCP tool runs regardless of policies.
## Per-user identity
Many internal MCP servers need to know *who* is asking — to apply their own permissions or to write audit records. Bag of words can inject the caller's identity into every call, as headers or as tool arguments, without the model being able to influence it. See [User context forwarding](/data-sources/user-context).
## Adding a connection
1. Open **Agents**, choose **New → Connection** (or **Connect data**), and pick an MCP preset or **MCP Server**.
2. Enter the `server_url` and choose the transport.
3. Choose an authentication mode and fill in its fields.
4. **Test**, then save. Tools are discovered on save.
5. Review the discovered tools and set each one's policy before exposing the connection to users.
6. Attach the connection to an agent so people can use it in chat.
# Data Sources Overview
Source: https://docs.bagofwords.com/data-sources/overview
Every connector Bag of words supports, and the three kinds of connections you can make
A **data source** is how Bag of words reaches your data. Connect a database, file share, application, custom MCP server, or custom API; choose the tables, folders, and tools that matter; and let agents investigate data in place—without copying it into a separate warehouse.
A connection is one building block of an **agent**. An agent can combine multiple data sources with selected tables, files, tools, instructions, and evaluations. See [Managing agents](/agents/overview) for the full model.
## Three kinds of connections
Databases, warehouses, BI and semantic layers, observability platforms, and business applications. The agent sees **tables** and writes queries against them.
File shares, object storage, and document libraries. The agent sees **files**, searches them, and reads their contents.
MCP servers and custom REST APIs. The agent sees **tools** it can call, each governed by an approval policy.
The distinction matters in three practical ways:
* **What the agent sees.** Table-shaped sources produce SQL; file-shaped sources produce search and reads; tool-shaped sources produce tool calls that can require confirmation before they run.
* **Who owns the catalog.** Most connections have one shared catalog an admin curates. Personal sources — OneDrive, Google Drive, a mailbox — have no shared catalog at all: each user's own account *is* the catalog.
* **What per-user authentication costs.** Per-user sign-in is included for file and tool connections. On database-style connections it requires an Enterprise license. See [Authentication and access](/data-sources/authentication).
## Data connectors
Databases, warehouses, BI tools, observability platforms, and business applications.
| | Connector | Kind | Edition |
| :------ | :------------------------------------------------------------------------ | :------------------- | :---------------- |
| ![]() | [Apache Druid](/data-sources/connectors/databases) | Database / warehouse | Beta |
|
![]() | [Apache Pinot](/data-sources/connectors/databases) | Database / warehouse | Beta |
|
![]() | [AWS Athena](/data-sources/connectors/databases) | Database / warehouse | Beta |
|
![]() | [AWS CloudWatch](/data-sources/connectors/observability) | Observability | Beta |
|
![]() | [AWS Cost Explorer](/data-sources/connectors/observability) | Observability | Beta |
|
![]() | [AWS Redshift](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Azure Data Explorer](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [ClickHouse](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Databricks SQL](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [DuckDB](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Elasticsearch](/data-sources/connectors/observability) | Observability | Beta |
|
![]() | [Google BigQuery](/data-sources/connectors/bigquery) | Database / warehouse | |
|
![]() | [Infor OLAP](/data-sources/connectors/infor-olap) | BI / semantic layer | Enterprise |
|
![]() | [Jaeger](/data-sources/connectors/observability) | Observability | Beta |
|
![]() | [Mariadb](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Microsoft Analysis Services](/data-sources/connectors/analysis-services) | BI / semantic layer | Enterprise |
|
![]() | [Microsoft Fabric](/data-sources/connectors/microsoft-fabric) | BI / semantic layer | |
|
![]() | [Microsoft SQL Server](/data-sources/connectors/sql-server) | Database / warehouse | |
|
![]() | [Monday data](/data-sources/connectors/business-apps) | Business application | Beta |
|
![]() | [MongoDB](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [MySQL](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [NetSuite](/data-sources/connectors/business-apps) | Business application | |
|
![]() | [OpenSearch](/data-sources/connectors/observability) | Observability | Beta |
|
![]() | [Oracle BI](/data-sources/connectors/oracle-bi) | BI / semantic layer | Enterprise |
|
![]() | [Oracle Database](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [PostgreSQL](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [PostHog](/data-sources/connectors/business-apps) | Business application | Beta |
|
![]() | [Power BI](/data-sources/connectors/power-bi) | BI / semantic layer | Enterprise |
|
![]() | [Power BI Report Server](/data-sources/connectors/power-bi-report-server) | BI / semantic layer | Enterprise |
|
![]() | [Prometheus](/data-sources/connectors/observability) | Observability | Beta |
|
![]() | [Qlik Sense](/data-sources/connectors/qlik-sense) | BI / semantic layer | Enterprise |
|
![]() | [Qlik Sense on-prem](/data-sources/connectors/qlik-sense-onprem) | BI / semantic layer | Enterprise |
|
![]() | [Salesforce](/data-sources/connectors/business-apps) | Business application | |
|
![]() | [SAP BusinessObjects](/data-sources/connectors/sap) | BI / semantic layer | |
|
![]() | [SAP BW (XMLA)](/data-sources/connectors/sap) | BI / semantic layer | |
|
![]() | [SAP Datasphere](/data-sources/connectors/sap) | BI / semantic layer | |
|
![]() | [SAP HANA](/data-sources/connectors/sap) | Database / warehouse | |
|
![]() | [ServiceNow](/data-sources/connectors/business-apps) | Business application | Beta |
|
![]() | [SharePoint Lists](/data-sources/connectors/sharepoint-lists) | Business application | Enterprise |
|
![]() | [Sisense](/data-sources/connectors/sisense) | BI / semantic layer | Enterprise |
|
![]() | [Snowflake](/data-sources/connectors/snowflake) | Database / warehouse | |
|
![]() | [Spark](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Splunk](/data-sources/connectors/observability) | Observability | Enterprise · Beta |
|
![]() | [SQLite](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Sybase SQL Anywhere](/data-sources/connectors/databases) | Database / warehouse | Enterprise |
|
![]() | [Tableau](/data-sources/connectors/tableau) | BI / semantic layer | Enterprise |
|
![]() | [Teradata Vantage](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Timbr AI](/data-sources/connectors/timbr) | BI / semantic layer | Enterprise |
|
![]() | [Trino](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Vertica](/data-sources/connectors/databases) | Database / warehouse | |
|
![]() | [Zabbix](/data-sources/connectors/observability) | Observability | Enterprise |
## File connectors
File shares, object storage, and document libraries.
| | Connector | Kind | Edition |
| :------ | :------------------------------------------------------------------------ | :------------------- | :--------- |
|
![]() | [Amazon S3](/data-sources/connectors/s3) | Database / warehouse | Beta |
|
![]() | [CSV](/data-sources/connectors/file-formats) | Files | |
|
![]() | [Files and Directories](/data-sources/connectors/files-and-directories) | Files | |
|
![]() | [Google Drive](/data-sources/connectors/google-drive) | Files | Enterprise |
|
![]() | [OneDrive](/data-sources/connectors/sharepoint-onedrive) | Files | Enterprise |
|
![]() | [OneNote](/data-sources/connectors/onenote) | Files | Enterprise |
|
![]() | [Qlik (QVD)](/data-sources/connectors/file-formats) | Files | Enterprise |
|
![]() | [SharePoint](/data-sources/connectors/sharepoint-onedrive) | Files | Enterprise |
|
![]() | [SharePoint Server (on-prem)](/data-sources/connectors/sharepoint-server) | Files | Enterprise |
## Integrations and tools
MCP servers, custom REST APIs, and mailbox connectors. Tool connections are governed by per-tool approval policies — see [MCP connections](/data-sources/mcp).
| | Connector | Kind | Edition |
| :------ | :-------------------------------------------- | :------------------- | :--------- |
| | [Custom API](/data-sources/custom-api) | Tools | Beta |
|
![]() | [Gmail](/data-sources/connectors/mail) | Business application | Enterprise |
|
![]() | [MCP Server](/data-sources/mcp) | Tools | Beta |
|
![]() | [Outlook Mail](/data-sources/connectors/mail) | Business application | Enterprise |
Bag of words also ships **MCP presets** — one-click tiles for Monday, Notion, Linear, Atlassian, GitHub, Sentry, Google Drive, and X. They all create a standard MCP connection with the server URL and OAuth settings pre-filled.
## Editions
Connectors marked **Enterprise** require a license key ([how to activate](/enterprise/license)). Without one, they appear in the catalog with a lock. Connectors marked **Beta** work but may change; treat their field names as less stable than the rest.
Missing a connector? Open an issue or a PR at [github.com/bagofwords1/bagofwords](https://github.com/bagofwords1/bagofwords).
## Where to go next
The setup flow: connect, choose tables, add context, and control access.
Shared vs per-user credentials, OAuth, Kerberos SSO, and what needs Enterprise.
Connect any MCP server and govern its tools.
Pass the caller's identity to an MCP server on every call.
# User Context Forwarding
Source: https://docs.bagofwords.com/data-sources/user-context
Pass the caller's identity to an MCP server on every tool call, without the model being able to change it
Internal services usually need to know *who* is asking. When Bag of words calls an MCP tool on a user's behalf, **user context forwarding** attaches that person's identity to the request — as HTTP headers, as tool arguments, or both.
This is what lets a shared MCP connection stay permission-aware: one connection, one set of server credentials, but every call carries the real caller's identity so the server can apply its own rules and write meaningful audit records.
Available on [MCP connections](/data-sources/mcp). Configured under **Advanced → User context forwarding** on the connection form. No Enterprise license required.
## Two ways to forward
**Headers** — the identity travels in HTTP headers, invisible to the model:
```text theme={null}
X-User-Email: dana@acme.com
X-Employee-Id: acme\1234
```
**Tool arguments** — the identity is merged into a named argument on every tool call, for servers that expect it in the payload rather than the transport:
```json theme={null}
{ "custom_metadata": { "user_email": "dana@acme.com", "role": "analyst" } }
```
## Available sources
Each forwarded field draws its value from one of these — and only these:
| Source | Value |
| ----------------------- | -------------------------------------------------------------- |
| `user.email` | The caller's email address |
| `user.name` | Their display name |
| `user.id` | Their Bag of words user id |
| `membership.role` | Their role in the organization |
| `membership.attr:` | A directory attribute, e.g. `membership.attr:employeeId` |
| `static:` | A fixed string, with `{...}` placeholders for any of the above |
The `static:` form is how you build composite values a service expects:
```text theme={null}
static:acme\{membership.attr:employeeId}
```
Placeholders use single braces — `{membership.attr:employeeId}`, not `{{ }}`.
## Where directory attributes come from
`membership.attr:` reads from the profile attributes synced from your identity provider when the user signs in. Entra ID profile sync supports: `jobTitle`, `department`, `companyName`, `officeLocation`, `employeeId`, `employeeType`, `employeeHireDate`, `employeeOrgData`, `mobilePhone`, `city`, `state`, `country`, `usageLocation`, and `preferredLanguage`.
Enable and pick which attributes to sync under **Settings → Identity**. Only synced attributes are available for forwarding — the connection form autocompletes from the list you configured.
The same attributes are also given to the planner as user profile context, so the agent can reason about who it is helping — not just forward it.
## Locked vs AI fields
Each forwarded field is one of two modes:
* **Locked** (default) — the value is set by the server and the field is **removed from the tool schema the model sees**. The model cannot read it, guess it, or override it. This is the correct choice for anything security-relevant, because the model cannot spoof a field it doesn't know exists.
* **AI** — the field stays visible to the model, which may fill it; Bag of words supplies the value only when the model leaves it empty.
If a server trusts a forwarded field for authorization, keep it locked. An AI field is a hint, not a guarantee.
## When a value is missing
Not every user has every attribute. Each field chooses what happens then:
| On missing | Behavior |
| ----------------- | ------------------------------- |
| `empty` (default) | Send an empty value |
| `omit` | Drop the field from the request |
| `block` | Refuse the tool call |
Use `block` for fields a service genuinely requires — the agent stops with `Missing required user context: ` instead of making a call that would fail or, worse, be treated as someone else.
Empty headers are always omitted rather than sent blank.
## How it behaves at call time
Injection happens **before** the user is asked to confirm a tool call, so what a person approves is exactly what goes on the wire. Locked fields are stripped from the schema during tool discovery as well as execution, so they never appear to the model at any stage.
## Setting it up
1. Open the MCP connection and expand **Advanced → User context forwarding**.
2. Add a header or metadata field.
3. Pick the source (user email, name, id, role, a directory attribute, or a static value).
4. Choose **Locked** or **AI**, and the missing-value behavior.
5. Save, then test with a real user account — not just an admin — to confirm the server sees what it expects.
# License Key
Source: https://docs.bagofwords.com/enterprise/license
Activate Enterprise Edition by configuring your license key
Bag of words Enterprise Edition (EE) is activated with a license key. Without a key, the platform runs in Community Edition.
## Set the license key
Provide the key via the `BOW_LICENSE_KEY` environment variable:
```bash theme={null}
export BOW_LICENSE_KEY="bow_lic_..."
```
Then reference it in `bow-config.yaml`:
```yaml theme={null}
license:
key: ${BOW_LICENSE_KEY}
```
The `license` block is commented out by default in `bow-config.yaml`. Uncomment it and restart the backend to pick up the key.
## Verify activation
After restarting, open **Settings → License** in the app. A valid key shows:
* Tier (`team` or `enterprise`)
* Organization name
* License ID
* Expiration date
If the key is invalid or expired, the app falls back to Community Edition.
## Getting a license
Contact [hi@bagofwords.com](mailto:hi@bagofwords.com) to request a license key.
# Open source and Enterprise
Source: https://docs.bagofwords.com/enterprise/overview
Compare the self-hosted open-source platform with Enterprise governance and scale controls.
Bag of Words is self-hosted and open source. Enterprise adds controls for organizations that need deeper governance, identity, performance, and operational safeguards.
The exact availability of a connector or feature is shown in the product and its documentation. Use this page as a planning guide, then confirm your license and deployment configuration before relying on an Enterprise capability.
| Capability | Open source | Enterprise |
| --------------------------------------------------------------------------- | -------------------- | ------------------------ |
| Self-hosted agentic analytics, agents, connections, instructions, and evals | Included | Included |
| Bring your own LLM and OpenAI-compatible endpoints | Included | Included |
| Core data connectors | Included | Included |
| Enterprise-gated connectors and per-user database access | — | Included where supported |
| Advanced model routing, fallback, and access control | — | Included |
| Custom Query acceleration and row-level security | — | Included |
| PII protection | — | Included |
| Advanced identity, directory, and service-account controls | — | Included |
| Audit and organization governance controls | Deployment-dependent | Expanded controls |
| Usage quotas and monthly spend limits | — | Included |
| Air-gapped and enterprise deployment options | — | Available |
See [License](/enterprise/license) for activation, [Quotas and usage limits](/observe-and-govern/quotas-and-usage-limits) for spend and consumption controls, and [Connect any data](/data-sources/overview) for connector-level availability.
# Embed BOW Chat
Source: https://docs.bagofwords.com/guides/embed
Add a BOW-powered report and streaming completion experience to your product with OAuth
Use the Bag of Words API to add a BOW-powered chat or completion panel to your own product. Your UI creates or reuses a report, streams a completion with `fetch`, and renders Server-Sent Events as they arrive.
This guide is for internal tools, trusted admin panels, and backend-proxied production apps.
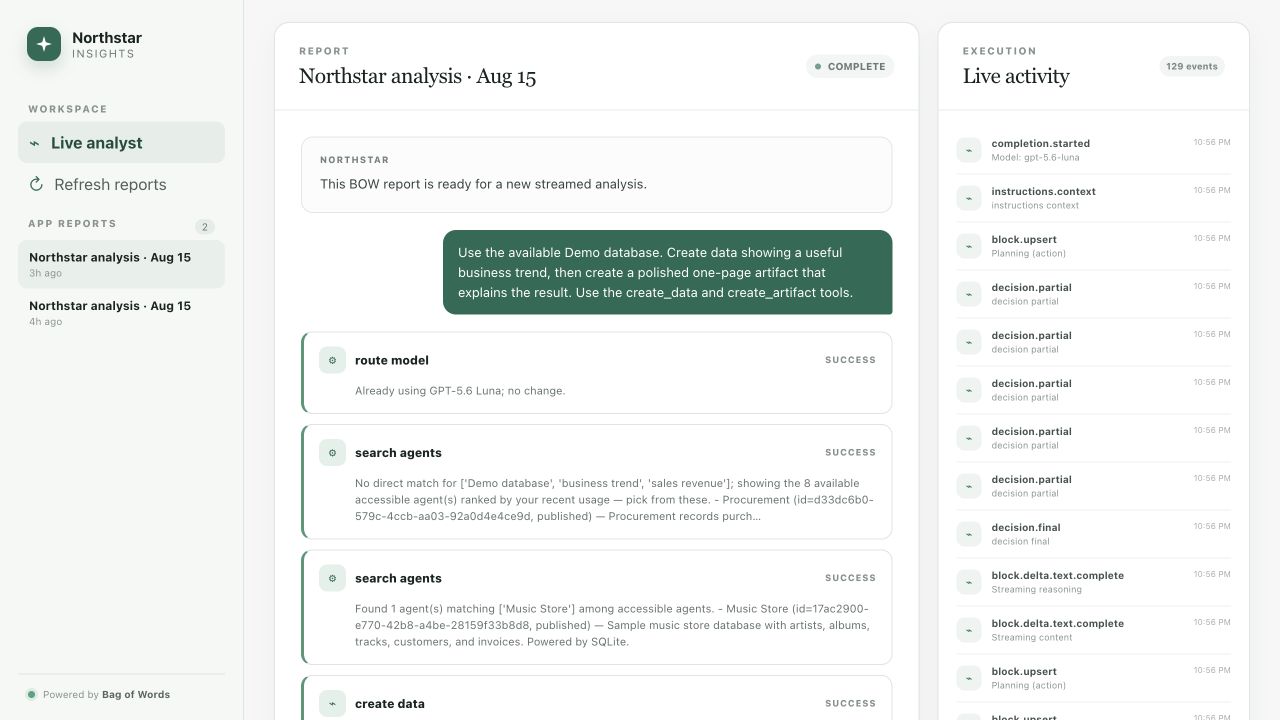
***
## What You Need
* A Bag of Words base URL — for example `https://bow.example.com`
* An OAuth app registered with the `app` scope
* An exact callback URL controlled by your application
* Optional data source or agent IDs to attach to the report
* A backend that can hold the user's OAuth tokens and proxy the BOW stream
Do **not** include `/api` in the user-facing base URL. Build the API base internally:
```ts TypeScript theme={null}
const bowUrl = inputBowUrl.replace(/\/+$/, "").replace(/\/api$/i, "");
const apiBase = `${bowUrl}/api`;
```
```python Python theme={null}
bow_url = input_bow_url.rstrip("/")
if bow_url.lower().endswith("/api"):
bow_url = bow_url[: -len("/api")]
api_base = f"{bow_url}/api"
```
## Set up OAuth
OAuth is the default credential for a user-facing embedded app. Every person signs in to BOW, and the resulting token calls the API with that person's existing organization membership and permissions.
1. In BOW, open **Settings → Channels → OAuth Apps**.
2. Register an app with the **BOW app** access surface.
3. Add your exact callback URL.
4. Copy the client ID.
5. Implement Authorization Code with PKCE `S256`.
See [OAuth Apps](/channels/oauth-apps) for the complete authorize, callback, token exchange, refresh, trust, and revocation flow.
A minimal browser redirect looks like this:
```ts TypeScript theme={null}
const state = crypto.randomUUID();
const verifierBytes = crypto.getRandomValues(new Uint8Array(32));
const verifier = base64url(verifierBytes);
const challengeBytes = await crypto.subtle.digest(
"SHA-256",
new TextEncoder().encode(verifier),
);
const challenge = base64url(new Uint8Array(challengeBytes));
sessionStorage.setItem("bow.oauth.state", state);
sessionStorage.setItem("bow.oauth.verifier", verifier);
const authorize = new URL(`${bowUrl}/api/oauth/authorize`);
authorize.search = new URLSearchParams({
response_type: "code",
client_id: clientId,
redirect_uri: callbackUrl,
scope: "app",
state,
code_challenge: challenge,
code_challenge_method: "S256",
}).toString();
window.location.assign(authorize.toString());
function base64url(bytes: Uint8Array) {
return btoa(String.fromCharCode(...bytes))
.replace(/\+/g, "-")
.replace(/\//g, "_")
.replace(/=+$/, "");
}
```
```python Python theme={null}
import base64
import hashlib
import secrets
from urllib.parse import urlencode
state = secrets.token_urlsafe(32)
verifier = secrets.token_urlsafe(64)
challenge = (
base64.urlsafe_b64encode(hashlib.sha256(verifier.encode()).digest())
.rstrip(b"=")
.decode()
)
# Keep both server-side. You need them again at the callback.
session["bow_oauth_state"] = state
session["bow_oauth_verifier"] = verifier
authorize = f"{bow_url}/api/oauth/authorize?" + urlencode(
{
"response_type": "code",
"client_id": client_id,
"redirect_uri": callback_url,
"scope": "app",
"state": state,
"code_challenge": challenge,
"code_challenge_method": "S256",
}
)
return redirect(authorize, code=302)
```
In Python, strip the base64 padding with `.rstrip(b"=")`. BOW compares the challenge against an unpadded base64url digest, and `base64.urlsafe_b64encode` pads by default — leaving the `=` produces a valid-looking authorize request that fails later at the token endpoint with `invalid_grant`.
At the callback, verify `state` before exchanging the code. A backend application should perform the exchange on its server and keep the access and refresh tokens in the user's encrypted session. A public browser client can exchange without a client secret, but should keep its short-lived tokens in `sessionStorage`, not persistent storage.
The API examples below assume you have the resulting `bow_oauth_...` access token.
## Local and Entra ID sign-in
Your app does not implement separate local and Microsoft sign-in flows. It always redirects to BOW.
If the user has no BOW session, BOW presents its own sign-in page. The user can enter a local BOW email and password or select a configured provider such as **Sign in with Entra**. BOW preserves the OAuth request across the sign-in round trip and returns the user to your callback.
For BOW deployment configuration, see [Microsoft Entra ID sign-in](/install#for-microsoft-entra-id-azure-ad).
A regular OAuth app shows consent after sign-in. A **Trusted** internal app skips the consent screen and returns automatically; it still requires the user to authenticate when no BOW session exists. If the user selects **Deny**, your callback receives `error=access_denied` with the original `state`, and no token is issued.
## Recommended Architecture
Use a backend-for-frontend for production applications:
```text theme={null}
Browser UI → Your backend → Bag of Words API
```
Your backend should:
* start the OAuth flow and store `state` plus the PKCE verifier
* exchange the authorization code
* keep access and refresh tokens out of browser JavaScript
* enforce your application's own authorization rules
* proxy BOW API requests and stream SSE responses to the browser
* rotate the stored refresh token after every successful refresh
This default architecture requires no BOW CORS setup.
## Browser-only apps and CORS
A browser-only app can use OAuth as a public PKCE client, but direct cross-origin API calls also require a BOW server allowlist.
Set exact origins on the BOW deployment and restart it:
```bash theme={null}
BOW_CORS_ALLOWED_ORIGINS=https://app.example.com,http://localhost:5173
```
Match scheme, host, and port exactly, with no trailing slash. Do not use `*`.
CORS is not involved when your backend calls BOW. Leave `BOW_CORS_ALLOWED_ORIGINS` unset for proxied and same-origin deployments.
## When to use a service account instead
Use a service-account API key only for an unattended integration with no signed-in person, such as a scheduled backend job. Create it under **Settings → Service Accounts** and keep it server-side.
Do not put a personal or service-account API key in browser code.
***
## Minimum Streaming Flow
1. Create a report with the data sources your chat should use.
2. `POST` a streaming completion to that report.
3. Parse SSE frames from the response body.
4. Render assistant text, reasoning, tool progress, and errors from the events.
Reports are the scope for data sources. Attach data sources when creating or updating the report — not in the completion prompt mentions.
***
## Create a Report
Create a report when the user starts a new chat session or when you need a temporary scratch report.
```http theme={null}
POST /api/reports
Authorization: Bearer bow_oauth_...
Content-Type: application/json
{
"title": "Customer Support Chat",
"data_sources": ["agent-or-data-source-id"]
}
```
```ts TypeScript theme={null}
async function createReport(apiBase: string, accessToken: string, dataSourceIds: string[]) {
const response = await fetch(`${apiBase}/reports`, {
method: "POST",
headers: {
Authorization: `Bearer ${accessToken}`,
"Content-Type": "application/json",
Accept: "application/json",
},
body: JSON.stringify({
title: "Embedded Bow Chat",
data_sources: dataSourceIds,
}),
});
if (!response.ok) throw new Error(`Create report failed: ${response.status}`);
return response.json() as Promise<{ id: string }>;
}
```
```python Python theme={null}
import httpx
def create_report(api_base: str, access_token: str, data_source_ids: list[str]) -> dict:
response = httpx.post(
f"{api_base}/reports",
headers={
"Authorization": f"Bearer {access_token}",
"Content-Type": "application/json",
"Accept": "application/json",
},
json={
"title": "Embedded Bow Chat",
"data_sources": data_source_ids,
},
)
response.raise_for_status()
return response.json()
```
***
## Stream a Completion
Use `fetch`, not `EventSource`, because the completion stream is a `POST` request with custom headers.
The same endpoint serves streaming and non-streaming responses. It streams when **any** of these is true — send `stream: true` and the `Accept` header together for clarity:
* `stream: true` in the request body
* `Accept: text/event-stream`
* `?stream=true` in the query string
```http theme={null}
POST /api/reports/{report_id}/completions
Authorization: Bearer bow_oauth_...
Content-Type: application/json
Accept: text/event-stream
{
"prompt": {
"content": "Show me the top customers this month",
"mentions": [],
"mode": "chat"
},
"stream": true
}
```
```ts TypeScript theme={null}
async function streamCompletion(params: {
apiBase: string;
accessToken: string;
reportId: string;
prompt: string;
signal?: AbortSignal;
onEvent: (event: BowSseEvent) => void;
}) {
const response = await fetch(
`${params.apiBase}/reports/${encodeURIComponent(params.reportId)}/completions`,
{
method: "POST",
headers: {
Authorization: `Bearer ${params.accessToken}`,
"Content-Type": "application/json",
Accept: "text/event-stream",
},
body: JSON.stringify({
prompt: { content: params.prompt, mentions: [], mode: "chat" },
stream: true,
}),
signal: params.signal,
},
);
if (!response.ok) {
const detail = await response.text();
throw new Error(`Completion failed: ${response.status} ${detail}`);
}
if (!response.body) throw new Error("Streaming response body is unavailable.");
const reader = response.body.getReader();
const decoder = new TextDecoder();
const parser = createSseParser(params.onEvent);
while (true) {
const { done, value } = await reader.read();
if (done) break;
parser.feed(decoder.decode(value, { stream: true }));
}
parser.feed(decoder.decode());
parser.flush();
}
```
```python Python theme={null}
from urllib.parse import quote
import httpx
def stream_completion(
api_base: str,
access_token: str,
report_id: str,
prompt: str,
on_event,
) -> None:
# timeout=None matters: a run can think for a long stretch between frames,
# and httpx's default read timeout would abort the stream mid-answer.
with httpx.Client(timeout=None) as client:
with client.stream(
"POST",
f"{api_base}/reports/{quote(report_id, safe='')}/completions",
headers={
"Authorization": f"Bearer {access_token}",
"Content-Type": "application/json",
"Accept": "text/event-stream",
},
json={
"prompt": {"content": prompt, "mentions": [], "mode": "chat"},
"stream": True,
},
) as response:
if response.status_code >= 400:
response.read()
raise RuntimeError(
f"Completion failed: {response.status_code} {response.text}"
)
parse_sse(response.iter_lines(), on_event)
```
***
## SSE Format
Bow sends standard Server-Sent Events:
```text theme={null}
event: completion.started
data: {"event":"completion.started","data":{"system_completion_id":"..."}}
event: block.delta.token
data: {"event":"block.delta.token","data":{"block_id":"...","field":"content","token":"Hello"}}
data: [DONE]
```
A blank line ends an event. Multiple `data:` lines belong to the same event and should be joined with `\n`.
The `data:` payload is an envelope — parse it like this:
```ts TypeScript theme={null}
const parsed = JSON.parse(dataString);
const payload = parsed.data ?? parsed;
```
```python Python theme={null}
parsed = json.loads(data_string)
payload = parsed.get("data") if isinstance(parsed, dict) else None
if payload is None:
payload = parsed
```
`data: [DONE]` means the stream is complete.
***
## Tiny SSE Parser
```ts TypeScript theme={null}
type BowSseEvent = {
event: string;
payload: unknown;
raw: string;
receivedAt: string;
done?: boolean;
malformed?: boolean;
};
function createSseParser(onEvent: (event: BowSseEvent) => void) {
let buffer = "";
let eventName = "message";
let dataLines: string[] = [];
let rawLines: string[] = [];
function dispatch() {
if (dataLines.length === 0) {
// Comment-only frames carry no event. BOW sends ": ping" heartbeats
// during quiet stretches of a run, and dispatching those would surface
// a bogus malformed event on every heartbeat.
eventName = "message";
rawLines = [];
return;
}
const dataString = dataLines.join("\n");
const raw = `${rawLines.join("\n")}\n\n`;
const receivedAt = new Date().toISOString();
if (dataString === "[DONE]") {
onEvent({ event: "[DONE]", payload: "[DONE]", raw, receivedAt, done: true });
} else {
try {
const parsed = JSON.parse(dataString);
onEvent({ event: eventName, payload: parsed.data ?? parsed, raw, receivedAt });
} catch (error) {
onEvent({
event: eventName,
payload: { error: String(error), data: dataString },
raw,
receivedAt,
malformed: true,
});
}
}
eventName = "message";
dataLines = [];
rawLines = [];
}
return {
feed(chunk: string) {
buffer += chunk;
while (true) {
const newlineIndex = buffer.search(/\r\n|\n|\r/);
if (newlineIndex === -1) break;
const line = buffer.slice(0, newlineIndex);
const newline = buffer.slice(newlineIndex).match(/^\r\n|\n|\r/)?.[0] ?? "\n";
buffer = buffer.slice(newlineIndex + newline.length);
if (line === "") { dispatch(); continue; }
rawLines.push(line);
if (line.startsWith(":")) continue;
const colonIndex = line.indexOf(":");
const field = colonIndex === -1 ? line : line.slice(0, colonIndex);
const value = colonIndex === -1 ? "" : line.slice(colonIndex + 1).replace(/^ /, "");
if (field === "event") eventName = value || "message";
if (field === "data") dataLines.push(value);
}
},
flush() {
if (buffer) { rawLines.push(buffer); buffer = ""; }
dispatch();
},
};
}
```
```python Python theme={null}
import json
from datetime import datetime, timezone
def parse_sse(lines, on_event) -> None:
event_name = "message"
data_lines: list[str] = []
raw_lines: list[str] = []
def dispatch() -> None:
nonlocal event_name, data_lines, raw_lines
if not data_lines:
# Comment-only frames carry no event. BOW sends ": ping" heartbeats
# during quiet stretches of a run, and dispatching those would
# surface a bogus malformed event on every heartbeat.
event_name = "message"
raw_lines = []
return
data_string = "\n".join(data_lines)
raw = "\n".join(raw_lines) + "\n\n"
received_at = datetime.now(timezone.utc).isoformat()
if data_string == "[DONE]":
on_event({
"event": "[DONE]",
"payload": "[DONE]",
"raw": raw,
"received_at": received_at,
"done": True,
})
else:
try:
parsed = json.loads(data_string)
payload = parsed.get("data") if isinstance(parsed, dict) else None
if payload is None:
payload = parsed
on_event({
"event": event_name,
"payload": payload,
"raw": raw,
"received_at": received_at,
})
except json.JSONDecodeError as error:
on_event({
"event": event_name,
"payload": {"error": str(error), "data": data_string},
"raw": raw,
"received_at": received_at,
"malformed": True,
})
event_name = "message"
data_lines = []
raw_lines = []
for line in lines:
if line == "":
dispatch()
continue
raw_lines.append(line)
if line.startswith(":"):
continue
field, _, value = line.partition(":")
if value.startswith(" "):
value = value[1:]
if field == "event":
event_name = value or "message"
elif field == "data":
data_lines.append(value)
# Flush a trailing frame that arrived without a final blank line.
dispatch()
```
The Python version is shorter because `httpx`'s `iter_lines()` already handles chunk reassembly and `\r\n` line endings, and yields the blank separator lines the framing depends on. The TypeScript version buffers bytes itself, so it has to do that work by hand.
***
## Event Reference
Handle unknown events gracefully — the API may add events over time. A minimal chat only needs `completion.started`, `block.upsert`, `block.delta.token`, `block.delta.text`, the `tool.*` events, and `completion.finished`; the rest are available when you want to render more of the run.
Every frame carries the same envelope — `event`, `data`, `timestamp`, `completion_id`, `agent_execution_id`, `seq` — so `seq` gives you a stable ordering within a run.
### Run lifecycle
| Event | Meaning | UI suggestion |
| ----------------------- | --------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------- |
| `completion.started` | The run has started. `data` carries `system_completion_id`, `user_prompt`, and the resolved `model` | Mark the chat as streaming and store `system_completion_id` — you need it to resume or stop the run |
| `completion.resumed` | Sent first on a re-attached stream instead of `completion.started` | Treat exactly like `completion.started` |
| `instructions.context` | The instructions loaded into this run's context | Optional; useful for a "what did the agent know" debug panel |
| `completion.follow_ups` | Suggested next questions, sent after the answer | Render as clickable chips |
| `completion.finished` | The run finished. `data.status` is `success`, `error`, or `stopped` | Mark the chat done. **May arrive more than once** for a single run — make this handler idempotent and ignore repeats |
| `completion.error` | The run failed at the completion level | Stop streaming and show the error message |
| `llm.error` | The LLM provider or model call failed | Stop streaming and show the error message |
| `[DONE]` | The SSE stream ended | Close the stream and re-enable input |
### Text and blocks
| Event | Meaning | UI suggestion |
| --------------------------- | ----------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------- |
| `block.upsert` | A block was created or updated. `data.block` holds the full block, including `title`, `icon`, and `status` | Insert or update the matching assistant, reasoning, or tool block |
| `block.delta.token` | A token-level delta. Always branch on `data.field` — `content` is the visible answer, `reasoning` is the thinking trace | Append `data.token` to that field |
| `block.delta.text` | A full replacement for a block field | Replace the field with `data.text` |
| `block.delta.text.complete` | That field is finished streaming | Stop any typing indicator on the block |
| `block.delta.artifact` | Incremental changes to a chart or table attached to the block | Optional; re-render the artifact preview |
| `decision.partial` | An intermediate reasoning/action decision | Show provisional reasoning or the planned tool call |
| `decision.final` | The decision was finalized. `data.metrics` carries timings and token usage | Mark the decision block complete |
### Tools and artifacts
| Event | Meaning | UI suggestion |
| ------------------------------------------------- | -------------------------------------------------------------------------- | ---------------------------------------------------------------- |
| `tool.started` | A tool call started (`tool_name`, `arguments`, `tool_call_id`, `block_id`) | Show a compact running tool row |
| `tool.progress` | Progress within a tool call — expect many per call | Update the tool row summary |
| `tool.finished` | A tool call finished (`status`, `result_summary`, `result_json`) | Mark the row success/error; keep result JSON behind a disclosure |
| `query.created` | The agent created a saved query on the report | Optional; link to it |
| `visualization.created` / `visualization.updated` | A chart or table was created, then filled in once the query ran | Optional; render the visualization inline |
***
## Rendering a Chat UI
This section stays in TypeScript whatever your backend is written in. With a backend-for-frontend, your Python service parses the BOW stream and forwards events to the browser, where this reducer runs.
Keep the UI reducer small:
* Store `status`: `idle`, `streaming`, `success`, or `error`
* Store blocks by `id`
* Append `block.delta.token` for assistant text
* Replace text on `block.delta.text`
* Show reasoning inside a collapsible disclosure
* Show tools as compact rows with name, status, and summary
* Keep raw JSON behind a disclosure for tool payloads
* Keep the raw SSE log available in a debug tab
```ts theme={null}
function applyBowEvent(state: ChatState, event: BowSseEvent) {
const payload = event.payload as Record;
switch (event.event) {
case "completion.started":
state.status = "streaming";
state.systemCompletionId = payload.system_completion_id;
break;
case "block.delta.token": {
const blockId = payload.block_id ?? "streaming";
const block = state.blocks[blockId] ??= { content: "" };
if (payload.field === "content") block.content += payload.token ?? "";
if (payload.field === "reasoning") block.reasoning = `${block.reasoning ?? ""}${payload.token ?? ""}`;
break;
}
case "tool.started":
case "tool.progress":
case "tool.finished":
state.tools[payload.tool_call_id ?? payload.tool_name ?? "tool"] = payload;
break;
case "completion.error":
case "llm.error":
state.status = "error";
state.error = payload.message ?? payload.error ?? JSON.stringify(payload);
break;
// Both can arrive more than once — keep this branch idempotent.
case "completion.finished":
if (payload.status === "error") state.status = "error";
else if (state.status !== "error") state.status = payload.status ?? "success";
break;
case "[DONE]":
if (state.status === "streaming") state.status = "success";
break;
}
}
```
***
## Resume and Stop a Run
A dropped connection does not stop the agent — the run continues server-side. Two endpoints cover the rest of the lifecycle.
**Re-attach to a run in progress** (page refresh, network drop, a second tab). Pass the `system_completion_id` you stored from `completion.started`. The endpoint is idempotent and side-effect free, so it is safe to retry with backoff. It replays the run's blocks, then continues live:
```http theme={null}
GET /api/reports/{report_id}/completions/{system_completion_id}/stream
Authorization: Bearer bow_oauth_...
Accept: text/event-stream
```
**Actually stop a run.** `AbortController` only closes your side of the socket; the agent keeps working and keeps spending tokens. To cancel the run itself, call:
```http theme={null}
POST /api/completions/{system_completion_id}/sigkill
Authorization: Bearer bow_oauth_...
```
Wire your Stop button to both: `sigkill` to end the run, `AbortController` to release the reader. The run then finishes with `status: "stopped"`.
***
## Non-Streaming and History
Omit the streaming triggers and the same `POST` returns JSON once the run completes, which suits scheduled jobs and server-side summaries. Add `?background=true` to return immediately and let the run continue in the background.
Sending a second prompt while a run is still going starts a **second concurrent run** on the report. If you want the chat to behave like one turn at a time instead, send `"queue": true` — the prompt is stored with `status: "queued"` and starts automatically when the current run finishes. Queued prompts never stream; drop one with `DELETE /api/completions/{completion_id}/queued` while it is still queued.
Both that response and `GET /api/reports/{report_id}/completions` return the **whole conversation envelope**, not a single completion:
```json theme={null}
{
"report_id": "...",
"completions": [{ "id": "...", "role": "system", "status": "success", "completion_blocks": [] }],
"latest_completion": "...",
"has_more": false,
"next_before": null,
"total_completions": 4
}
```
Read the answer from the last `role: "system"` entry. For history, page with `?limit=` and `?before=` (an ISO timestamp cursor) and follow `has_more` / `next_before`.
***
## Optional API Requests
**Validate the OAuth session:**
```http theme={null}
GET /api/users/whoami
Authorization: Bearer bow_oauth_...
```
**Load data sources or agents for a picker:**
```http theme={null}
GET /api/mentions/available?categories=data_sources
Authorization: Bearer bow_oauth_...
```
**Update a report when the user changes selected data sources:**
```http theme={null}
PUT /api/reports/{report_id}
Authorization: Bearer bow_oauth_...
Content-Type: application/json
{
"data_sources": ["agent-or-data-source-id"]
}
```
***
## Error Handling
| Status | Meaning |
| -------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- |
| `400` | Invalid request, or no default LLM model configured — *"No default LLM model configured. Please go to Settings > LLM and set a default model."* |
| `401` | Missing, invalid, expired, or revoked OAuth access token |
| `403` | The signed-in user does not have permission for this resource |
| `404` | Report not found or not visible to the signed-in user |
| Network / CORS | The browser could not reach BOW, or a browser-only app's origin is not in `BOW_CORS_ALLOWED_ORIGINS` |
| Abort | User stopped the stream — treat as controlled cancellation, not a crash |
| Malformed SSE | Keep the raw frame and show a debug-friendly parse error |
Failures **after** the stream opens do not change the HTTP status — the response is already `200`. A run that fails mid-flight reports it as a `completion.error` or `llm.error` frame, or as `completion.finished` with `status: "error"`. Handle those events, not just `response.ok`.
***
## Copy-Paste cURL with an OAuth token
```bash theme={null}
BOW_URL='https://bow.example.com'
# Obtain this from the OAuth callback/token exchange above.
BOW_ACCESS_TOKEN=''
API_BASE="$BOW_URL/api"
REPORT_ID="$(curl -sS -X POST "$API_BASE/reports" \
-H "Authorization: Bearer $BOW_ACCESS_TOKEN" \
-H "Content-Type: application/json" \
--data-raw '{
"title": "Embedded Bow Chat",
"data_sources": []
}' | jq -r '.id')"
curl -N -X POST "$API_BASE/reports/$REPORT_ID/completions" \
-H "Authorization: Bearer $BOW_ACCESS_TOKEN" \
-H "Content-Type: application/json" \
-H "Accept: text/event-stream" \
--data-raw '{
"prompt": {
"content": "Show me a summary of this report",
"mentions": [],
"mode": "chat"
},
"stream": true
}'
```
***
## Production Checklist
* Register an OAuth app with the `app` scope and exact callback URLs
* Use Authorization Code with PKCE `S256`; verify `state` at the callback
* Keep OAuth tokens server-side behind a backend proxy
* Replace the stored refresh token after every refresh
* Set `BOW_CORS_ALLOWED_ORIGINS` only if browser JavaScript calls BOW directly
* Wire the Stop button to `sigkill` **and** `AbortController` — aborting alone leaves the run going
* Persist the report ID for the conversation and the `system_completion_id` for the run in flight, so a refresh can re-attach
* Attach data sources through report creation or update
* Keep `mentions: []` unless your integration intentionally supports Bow prompt mentions
* Treat `completion.finished` as idempotent — it can arrive more than once
* Log raw SSE frames for support and debugging
* Render unknown future events without crashing
# Git Workflow
Source: https://docs.bagofwords.com/guides/git
Manage instructions as code with Git integration and CI/CD automation
## Why Manage Instructions as Code?
Your analytics knowledge—business definitions, calculation formulas, SQL patterns—shouldn't live in a UI or people's heads. Treating instructions as code brings the same rigor you use for data pipelines:
* **Version control**: Full history of what changed, when, and why
* **Code review**: Team members review instruction changes before they go live
* **Automated testing**: Run evals on every PR to catch regressions
* **Single source of truth**: Documentation stays in sync with your data models
* **Collaboration**: Data engineers, analysts, and AI work from the same definitions
If you already manage dbt models, LookML, or documentation in Git, Bow fits right into that workflow. Your existing docs become instructions automatically.
![Git Workflow]() ***
## Connecting a Repository
Connect your Git repository in [Data Sources](/data-sources/overview). Bow supports:
| Source | Default Load Mode |
| :----------------------------- | :---------------- |
| Markdown files (.md) | Always |
| dbt models, metrics, sources | Intelligent |
| dbt seeds | Intelligent |
| dbt macros, tests | Disabled |
| LookML views, models, explores | Intelligent |
### Repository Settings
| Setting | Description |
| :-------------------- | :---------------------------------------- |
| **Branch** | Which branch to sync from |
| **Auto Publish** | Automatically approve synced instructions |
| **Default Load Mode** | Auto, Always, Intelligent, or Disabled |
***
## Writing Instructions in Markdown
Create `.md` files in your repository with YAML frontmatter to control how Bow loads them.
### Basic Example
```markdown theme={null}
---
alwaysApply: true
references:
- customers
- orders
---
# Customer Lifetime Value
CLV = SUM(order_total) WHERE customer_id = X AND status = 'completed'
Use 12-month lookback window from analysis date.
```
### Frontmatter Options
| Field | Type | Description |
| ------------- | ------- | ---------------------------------------------------- |
| `alwaysApply` | boolean | `true` → Load mode = Always, `false` → Intelligent |
| `references` | list | Tables/views this instruction references |
| `status` | string | `published` (default), `draft`, `archived` |
| `category` | string | `general`, `code`, `data_modeling`, `visualizations` |
***
## Git CI/CD Integration
Automate your instruction workflow: create instructions in Git, run evals on PR, and deploy on merge.
### Prerequisites
1. **Git Repository** connected to Bow with a Personal Access Token (PAT)
2. **API Key** from Bow Settings → API Keys
3. **Test Suite** with test cases configured in Bow
### API Reference
| Endpoint | Method | Description |
| ----------------------------- | ------ | ----------------------------------- |
| `/git/{repo_id}/sync` | POST | Sync a branch → creates DRAFT build |
| `/tests/runs/batch` | POST | Run evals against a build |
| `/tests/runs/{run_id}/status` | GET | Get eval results |
| `/builds/{build_id}/publish` | POST | Publish build to main |
Base API URL should be with `/api` suffix. i.e `https://app.bagofwords.com/api`
***
## GitHub Actions Setup
### 1. Add Repository Secrets
| Secret | Description |
| -------------- | -------------------------- |
| `BOW_API_KEY` | Your Bow API key |
| `BOW_REPO_ID` | Git repository ID from Bow |
| `BOW_SUITE_ID` | Test suite ID for evals |
### 2. Add Repository Variable
| Variable | Description |
| ------------- | -------------------------------------------------------------- |
| `BOW_API_URL` | Your Bow instance URL (e.g., `https://app.bagofwords.com/api`) |
### 3. Create Workflow File
Create `.github/workflows/bow.yml`:
```yaml theme={null}
name: Bow CI/CD
on:
pull_request:
paths:
- '**/*.md'
- 'bow/**'
push:
branches: [main]
paths:
- '**/*.md'
- 'bow/**'
env:
BOW_API_URL: ${{ vars.BOW_API_URL }}
BOW_REPO_ID: ${{ secrets.BOW_REPO_ID }}
BOW_API_KEY: ${{ secrets.BOW_API_KEY }}
jobs:
# ============================================
# On Pull Request: Sync + Run Evals
# ============================================
test:
if: github.event_name == 'pull_request'
runs-on: ubuntu-latest
steps:
- name: Sync branch to Bow
id: sync
run: |
echo "Syncing branch '${{ github.head_ref }}' to Bow..."
RESPONSE=$(curl -sf -X POST "$BOW_API_URL/git/$BOW_REPO_ID/sync" \
-H "Authorization: Bearer $BOW_API_KEY" \
-H "Content-Type: application/json" \
-d '{"branch": "${{ github.head_ref }}"}')
BUILD_ID=$(echo $RESPONSE | jq -r '.build_id')
BUILD_NUM=$(echo $RESPONSE | jq -r '.build_number')
echo "build_id=$BUILD_ID" >> $GITHUB_OUTPUT
echo "✅ Created draft build #$BUILD_NUM"
- name: Run evals
id: evals
run: |
echo "Starting evals against build ${{ steps.sync.outputs.build_id }}..."
# Start test run
RUN_RESPONSE=$(curl -sf -X POST "$BOW_API_URL/tests/runs/batch" \
-H "Authorization: Bearer $BOW_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"suite_id": "${{ secrets.BOW_SUITE_ID }}",
"build_id": "${{ steps.sync.outputs.build_id }}",
"trigger_reason": "github_pr"
}')
RUN_ID=$(echo $RUN_RESPONSE | jq -r '.id')
echo "run_id=$RUN_ID" >> $GITHUB_OUTPUT
# Poll for completion
echo "Waiting for evals to complete..."
while true; do
STATUS_RESPONSE=$(curl -sf "$BOW_API_URL/tests/runs/$RUN_ID/status" \
-H "Authorization: Bearer $BOW_API_KEY")
STATUS=$(echo $STATUS_RESPONSE | jq -r '.run.status')
if [[ "$STATUS" == "completed" || "$STATUS" == "failed" ]]; then
PASSED=$(echo $STATUS_RESPONSE | jq -r '.run.summary_json.passed // 0')
FAILED=$(echo $STATUS_RESPONSE | jq -r '.run.summary_json.failed // 0')
echo "passed=$PASSED" >> $GITHUB_OUTPUT
echo "failed=$FAILED" >> $GITHUB_OUTPUT
break
fi
sleep 10
done
- name: Post results to PR
uses: actions/github-script@v7
with:
script: |
const passed = '${{ steps.evals.outputs.passed }}';
const failed = '${{ steps.evals.outputs.failed }}';
const buildId = '${{ steps.sync.outputs.build_id }}';
const status = failed > 0 ? '❌' : '✅';
github.rest.issues.createComment({
owner: context.repo.owner,
repo: context.repo.repo,
issue_number: context.issue.number,
body: `## ${status} Bow Eval Results\n\n| Passed | Failed |\n|--------|--------|\n| ${passed} | ${failed} |\n\n[View in Bow](${process.env.BOW_API_URL}/evals?build=${buildId})`
});
- name: Fail if evals failed
if: steps.evals.outputs.failed > 0
run: exit 1
# ============================================
# On Merge to Main: Publish Build
# ============================================
publish:
if: github.event_name == 'push' && github.ref == 'refs/heads/main'
runs-on: ubuntu-latest
steps:
- name: Get build for merged branch
id: get_build
run: |
# Get the most recent draft build from git source
RESPONSE=$(curl -sf "$BOW_API_URL/builds?status=draft&limit=1" \
-H "Authorization: Bearer $BOW_API_KEY")
BUILD_ID=$(echo $RESPONSE | jq -r '.items[0].id')
if [[ "$BUILD_ID" == "null" || -z "$BUILD_ID" ]]; then
echo "No draft build found to publish"
exit 0
fi
echo "build_id=$BUILD_ID" >> $GITHUB_OUTPUT
- name: Publish build
if: steps.get_build.outputs.build_id
run: |
echo "Publishing build ${{ steps.get_build.outputs.build_id }}..."
curl -sf -X POST "$BOW_API_URL/builds/${{ steps.get_build.outputs.build_id }}/publish" \
-H "Authorization: Bearer $BOW_API_KEY"
echo "✅ Build published to main"
```
***
## How It Works
### On PR Open/Update
1. **Sync**: `POST /git/{repo_id}/sync` pulls your branch and creates a **draft build**
2. **Eval**: `POST /tests/runs/batch` runs your test suite against the draft build
3. **Report**: Results are posted as a PR comment
### On PR Merge
1. **Publish**: `POST /builds/{build_id}/publish` promotes the draft build to main
2. Your instructions are now live in Bow
***
## Unlinking from Git
If you need to modify a Git-synced instruction directly in Bow:
1. Edit the instruction in Bow
2. Save changes
3. Confirm "Unlink from Git" when prompted
The instruction becomes user-owned and will no longer sync from the repository.
# Deployment Options
Source: https://docs.bagofwords.com/install
Install Bag of Words on your own server using Docker or Kubernetes
## Install with Docker
***
You can install Bag of Words with a single docker command. By default, it will use SQLite as the database.
You can also configure it to use PostgreSQL by passing `BOW_DATABASE_URL` environment variable.
```bash theme={null}
docker run --pull always -d -p 3000:3000 bagofwords/bagofwords
```
To use PostgreSQL, you need to set the `BOW_DATABASE_URL` environment variable.
For example: `BOW_DATABASE_URL=postgresql://postgres:postgres@localhost:5432/bagofwords`
### Update
* Re-run the same `docker run --pull always ...` command to fetch and start the latest image.
* Optionally, pull explicitly and restart:
```bash theme={null}
docker pull bagofwords/bagofwords:latest
# stop/remove your existing container if needed, then start again
# docker stop && docker rm
docker run --pull always -d -p 3000:3000 bagofwords/bagofwords
```
## Install with Docker Compose
***
Run Bag of Words with Docker Compose and Caddy (built-in TLS on port 443). We recommend using the canonical files from the repo to avoid drift:
* `docker-compose.yaml`: [https://github.com/bagofwords1/bagofwords/blob/main/docker-compose.yaml](https://github.com/bagofwords1/bagofwords/blob/main/docker-compose.yaml)
* `Caddyfile`: [https://github.com/bagofwords1/bagofwords/blob/main/Caddyfile](https://github.com/bagofwords1/bagofwords/blob/main/Caddyfile)
### Steps
1. Make sure Docker and Docker Compose are installed.
2. Clone the repo:
```bash theme={null}
git clone https://github.com/bagofwords1/bagofwords
cd bagofwords
```
3. Create a `.env` file (for domain and credentials). Example:
```env theme={null}
# Domain used by Caddy for HTTPS (must resolve to your server's public IP)
DOMAIN=yourdomain.com
# PostgreSQL (use stronger values for production)
POSTGRES_USER=bow
POSTGRES_PASSWORD=your_secure_pw
POSTGRES_DB=bagofwords
# Optional but recommended: encryption key (Fernet, 44 chars incl. '=')
# Generate with OpenSSL: openssl rand -base64 32 | tr '+/' '-_'
BOW_ENCRYPTION_KEY=
```
Generate `BOW_ENCRYPTION_KEY` with OpenSSL:
```bash theme={null}
openssl rand -base64 32 | tr '+/' '-_'
```
4. Start services:
```bash theme={null}
docker compose up -d
```
5. Point your domain to the server's public IP:
* Create an A record for `yourdomain.com` → your instance public IP.
* Caddy will automatically obtain/renew the TLS certificate and serve on port 443.
6. Open `https://yourdomain.com`
Caddy is included by default as a reverse proxy on port 443. If you prefer to run without Caddy, remove the `caddy` service from `docker-compose.yaml` and expose the app directly on port 3000. For local, no-SSL testing, you can also use `docker-compose.dev.yaml`.
### Update
```bash theme={null}
# pull latest images and recreate containers
docker compose pull
docker compose up -d
```
## Other configurations
***
You can also configure additional settings in the bow-config.yaml file.
```yaml theme={null}
# bow-config.yaml
# Deployment Configuration
base_url: http://0.0.0.0:3000
database:
url: ${BOW_DATABASE_URL}
# Feature Flags
features:
allow_uninvited_signups: false
allow_multiple_organizations: false
verify_emails: false
google_oauth:
enabled: false
client_id: ${BOW_GOOGLE_CLIENT_ID}
client_secret: ${BOW_GOOGLE_CLIENT_SECRET}
smtp_settings:
host: "smtp.resend.com"
port: 587
username: "resend"
password: ${BOW_SMTP_PASSWORD}
encryption_key: ${BOW_ENCRYPTION_KEY}
intercom:
enabled: true
```
To use the custom config file, you can run the following command:
```bash theme={null}
docker run --pull always -d -p 3000:3000 -v $(pwd)/bow-config.yaml:/app/bow-config.yaml bagofwords/bagofwords
```
## Install with Kubernetes
***
You can install Bag of Words on a Kubernetes cluster. The Helm chart can deploy the app with a bundled PostgreSQL instance **or** connect to an external managed database such as AWS Aurora with IAM authentication.
### 1. Add the Helm Repository
```bash theme={null}
helm repo add bow https://helm.bagofwords.com/
helm repo update
```
### 2. Install or Upgrade the Chart
Here are a few examples of how to install or upgrade the Bag of Words Helm chart:
**Deploy with a bundled PostgreSQL instance:**
```bash theme={null}
helm upgrade -i --create-namespace \
-nbowapp-1 bowapp bow/bagofwords \
--set postgresql.auth.username= \
--set postgresql.auth.password= \
--set postgresql.auth.database=
```
**Deploy without TLS with a custom hostname:**
```bash theme={null}
helm upgrade -i --create-namespace \
-nbowapp-1 bowapp bow/bagofwords \
--set host= \
--set postgresql.auth.username= \
--set postgresql.auth.password= \
--set postgresql.auth.database= \
--set ingress.tls=false
```
**Deploy with TLS, cert-manager, and Google OAuth:**
```bash theme={null}
helm upgrade -i --create-namespace \
-nbowapp-1 bowapp bow/bagofwords \
--set host= \
--set postgresql.auth.username= \
--set postgresql.auth.password= \
--set postgresql.auth.database= \
--set config.googleOauthEnabled=true \
--set config.googleClientId= \
--set config.googleClientSecret=
```
### Deploy with AWS Aurora and IAM Authentication
When using a managed database like AWS Aurora PostgreSQL, the chart skips the bundled PostgreSQL subchart and connects directly to your Aurora cluster. Passwords are never stored — short-lived IAM tokens are generated at runtime for every new database connection.
**Prerequisites:**
* An Aurora PostgreSQL cluster with **IAM database authentication** enabled
* A database user created with: `GRANT rds_iam TO `
* An IAM role/policy with `rds-db:connect` permission
* In EKS: an **IRSA** (IAM Roles for Service Accounts) annotation on the pod's service account so the app can assume the IAM role
```bash theme={null}
helm upgrade -i --create-namespace \
-nbowapp-1 bowapp bow/bagofwords \
--set host= \
--set database.auth.provider=aws_iam \
--set database.auth.region=us-east-1 \
--set database.auth.sslMode=require \
--set database.host= \
--set database.port=5432 \
--set database.username= \
--set database.name= \
--set serviceAccount.annotations.'eks\.amazonaws\.com/role-arn'=arn:aws:iam:::role/
```
Or use a values file:
```yaml theme={null}
# aurora-values.yaml
host: bow.example.com
database:
auth:
provider: aws_iam
region: us-east-1
sslMode: require
host: my-cluster.cluster-xxx.us-east-1.rds.amazonaws.com
port: 5432
username: bow_user
name: postgres
serviceAccount:
name: bowapp
annotations:
eks.amazonaws.com/role-arn: arn:aws:iam::123456789012:role/bow-rds-role
config:
encryptionKey: ""
baseUrl: "https://bow.example.com"
```
```bash theme={null}
helm upgrade -i --create-namespace \
-nbowapp-1 bowapp bow/bagofwords \
-f aurora-values.yaml
```
When `database.auth.provider` is set to `aws_iam`, the bundled PostgreSQL subchart is automatically skipped. The app uses `boto3` to call `generate_db_auth_token()` before each new connection, so tokens rotate automatically and no static database password is needed.
### Update
```bash theme={null}
# Restart the Bag of Words deployment(s) to pick up the latest image
# Adjust namespace (-n) and selector if you used different names
kubectl rollout restart deployment -n bowapp-1 -l app.kubernetes.io/instance=bowapp
kubectl rollout status deployment -n bowapp-1 -l app.kubernetes.io/instance=bowapp
```
## AWS Aurora Configuration
***
Bag of Words supports connecting to **AWS Aurora PostgreSQL** using IAM database authentication. This eliminates static database passwords entirely — the application generates short-lived tokens (valid for 15 minutes) at connection time using AWS IAM.
### How it works
1. The app's service account assumes an IAM role (via IRSA in EKS, or instance profile on EC2)
2. On every new database connection, the app calls `generate_db_auth_token()` to get a temporary password
3. The token is used as the PostgreSQL password — established connections are not affected when it expires
4. SSL is required (`require` or `verify-full`)
### AWS Setup
**1. Enable IAM authentication on the Aurora cluster:**
```bash theme={null}
aws rds modify-db-cluster \
--db-cluster-identifier \
--enable-iam-database-authentication \
--apply-immediately
```
**2. Create the database user with IAM grants:**
```sql theme={null}
CREATE USER bow_user;
GRANT rds_iam TO bow_user;
GRANT ALL PRIVILEGES ON DATABASE postgres TO bow_user;
```
**3. Create an IAM policy allowing `rds-db:connect`:**
```json theme={null}
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": "rds-db:connect",
"Resource": "arn:aws:rds-db:::dbuser:/"
}
]
}
```
**4. For EKS — create an IRSA-enabled service account:**
```bash theme={null}
eksctl create iamserviceaccount \
--name bowapp \
--namespace bowapp-1 \
--cluster \
--attach-policy-arn arn:aws:iam:::policy/bow-rds-connect \
--approve
```
Then set the IRSA annotation in the Helm chart:
```bash theme={null}
--set serviceAccount.annotations.'eks\.amazonaws\.com/role-arn'=arn:aws:iam:::role/
```
### bow-config.yaml for Aurora (non-Kubernetes)
If you are running Bag of Words on EC2 or ECS (not Kubernetes), you can configure Aurora IAM auth directly in `bow-config.yaml`:
```yaml theme={null}
database:
host: "my-cluster.cluster-xxx.us-east-1.rds.amazonaws.com"
port: 5432
name: "postgres"
username: "bow_user"
auth:
provider: "aws_iam"
region: "us-east-1"
ssl_mode: "require"
```
The EC2 instance or ECS task must have an IAM role with the `rds-db:connect` policy attached.
## Google OAuth
To enable Google OAuth authentication, configure the following parameters in your bow config (or in env/k8s configmap):
```yaml theme={null}
google_oauth:
enabled: true
client_id: ${BOW_GOOGLE_CLIENT_ID}
client_secret: ${BOW_GOOGLE_CLIENT_SECRET}
```
You should also set the following in your Google OAuth configurations:
1. Callback URL: `https://yourbaseurl.com/api/auth/google/callback`
2. Scopes: `/auth/userinfo.email`, `/auth/userinfo.profile`, `openid`
3. Enable People API
## OpenID Connect (OIDC)
```yaml theme={null}
oidc_providers:
- name: okta
enabled: true
issuer: https://***********.okta.com/oauth2/default
client_id: ${OKTA_CLIENT_ID}
client_secret: ${OKTA_CLIENT_SECRET}
scopes: ["openid", "profile", "email"]
pkce: true
client_auth_method: basic
discovery: true
uid_claim: sub
```
### For Okta
1. Set a new OIDC application: web
2. Set callback URL `https://your-base-bow-url.com/api/auth/okta/callback`
### For Microsoft Entra ID (Azure AD)
```yaml theme={null}
oidc_providers:
- name: entra
enabled: true
issuer: https://login.microsoftonline.com/${ENTRA_TENANT_ID}/v2.0
client_id: YOUR_CLIENT_ID
client_secret: ${BOW_ENTRA_CLIENT_SECRET}
scopes: ["openid", "profile", "email", "api://YOUR_CLIENT_ID/access_as_user"]
pkce: true
client_auth_method: post
discovery: true
uid_claim: sub
sync_groups: true
group_claim: "groups"
resolve_group_names: true
```
1. In the Azure portal, register a new application under **Microsoft Entra ID → App registrations**.
2. Set the redirect URI (type: Web) to `https://your-base-bow-url.com/api/auth/entra/callback`.
3. Copy the **Directory (tenant) ID** into `${ENTRA_TENANT_ID}` and the **Application (client) ID** into `${BOW_ENTRA_CLIENT_ID}`.
4. Under **Certificates & secrets**, create a client secret and set it as `${BOW_ENTRA_CLIENT_SECRET}`.
5. Use `client_auth_method: post` — Entra ID expects credentials in the request body rather than the `Authorization` header.
**Group sync**
When `sync_groups: true`, group memberships from the `groups` claim are synced to Bag of Words on each login. To make Entra ID emit the claim, edit the app's **Token configuration → Add groups claim** and select the group types you want.
* `group_claim` — the token claim that carries group membership (default `groups`).
* `resolve_group_names: true` — by default Entra ID emits group **object IDs**, not display names. Enabling this resolves the IDs to human-readable names via Microsoft Graph (requires the app to have the `GroupMember.Read.All` or `Directory.Read.All` permission granted).
## LDAP / Active Directory
For environments that authenticate against an on-premises directory, enable the LDAP provider:
```yaml theme={null}
ldap:
enabled: true
url: ldaps://ad.company.com:636
bind_dn: cn=service-account,ou=Services,dc=company,dc=com
bind_password: ${BOW_LDAP_BIND_PASSWORD}
```
* `url` — the directory endpoint. Use `ldaps://` (port 636) for TLS; avoid plain `ldap://` (port 389) outside a trusted network.
* `bind_dn` — the distinguished name of a read-only service account used to look up users.
* `bind_password` — the service account password, supplied via the `${BOW_LDAP_BIND_PASSWORD}` environment variable rather than committed to the config.
## SMTP Settings
Configure an outbound mail server to enable email features — dashboard and conversation share notifications, scheduled report and prompt results (with optional PDF attachments), password-reset and email-verification links, and the AI `send_email` tool.
Define the `smtp_settings` block in `bow-config.yaml`:
```yaml theme={null}
smtp_settings:
host: "smtp.resend.com"
port: 587
username: "resend"
password: ${BOW_SMTP_PASSWORD}
from_name: "Bag of words"
from_email: "hi@bagofwords.com"
use_tls: true
use_ssl: false
use_credentials: true
validate_certs: true
```
| Key | Default | Env var | Notes |
| ----------------- | ------------------- | -------------------------- | -------------------------------- |
| `host` | `smtp.resend.com` | `BOW_SMTP_HOST` | SMTP server |
| `port` | `587` | `BOW_SMTP_PORT` | |
| `username` | — | `BOW_SMTP_USERNAME` | |
| `password` | — | `BOW_SMTP_PASSWORD` | Sensitive — supply via env var |
| `from_name` | `Bag of words` | `BOW_SMTP_FROM_NAME` | Display name on outgoing mail |
| `from_email` | `hi@bagofwords.com` | `BOW_SMTP_FROM_EMAIL` | From address |
| `use_tls` | `true` | `BOW_SMTP_USE_TLS` | STARTTLS |
| `use_ssl` | `false` | `BOW_SMTP_USE_SSL` | SSL at connect |
| `use_credentials` | `true` | `BOW_SMTP_USE_CREDENTIALS` | Set `false` for anonymous relays |
| `validate_certs` | `true` | `BOW_SMTP_VALIDATE_CERTS` | |
Email is enabled only when credentials are present (or `use_credentials: false` for anonymous relays). If no mail client can be built at startup, email features are silently inert — outgoing notifications are skipped and the `send_email` tool stays disabled.
# Bag of words
Source: https://docs.bagofwords.com/introduction
Governed AI agents for any model and any data.
Bag of words gives teams a governed **agentic analytics** system: use the LLMs you choose, connect the data you already have, and let agents investigate, validate, and explain work that ranges from a quick question to a deep root-cause analysis.
![An executive dashboard artifact beside the prompt, validation steps, sharing, and schedule that created it]() Agents can work across databases, services, APIs, tables, semantic objects, documents, and files. They do not just produce a one-shot answer: they plan, use tools in parallel, inspect evidence, reflect on what is missing, and repair their approach when needed—all within the access and policy boundaries you define.
Sign in, create your workspace, and ask a first question.
Use a catalog connector, a custom MCP server, or a custom API.
Shape agents with data, tools, files, instructions, and evals.
## From question to defensible result
Bag of words runs a governed agentic loop. An agent plans the investigation, explores independent evidence in parallel, calls only the data and tools it is allowed to use, validates what it finds, and reflects or repairs when the evidence is incomplete. The same system can answer a focused business question or coordinate a challenging financial analysis or production root-cause investigation.
![A current Chat-mode root-cause analysis with parallel tool work, an investigation note, and a Mermaid incident map]() Its **Knowledge Harness** is the context that makes the loop useful: scoped connections, tables and semantic objects, files, tools, instructions, identity, permissions, and prior evidence. Evals and feedback close the self-improvement loop, so teams can review and promote better instructions rather than giving an agent unchecked authority to change its own rules.
## What you can build
* **Business analysis:** revenue and financial analysis, operating reviews, and self-serve exploration.
* **Technical investigation:** production root-cause analysis across observability systems, services, and databases.
* **Knowledge work:** research and synthesis across structured records and unstructured files.
* **Repeatable workflows:** training agents with scoped instructions and evaluations, then tracking quality, usage, and cost.
Learn Chat mode, Training mode, and the analysis workflow.
Inspect runs, traces, quality, usage, and cost.
# Observe and govern
Source: https://docs.bagofwords.com/observe-and-govern/overview
Trace agent work, understand quality and cost, and operate Bag of Words with confidence.
Bag of Words makes agent behavior inspectable. Monitoring connects aggregate adoption and cost trends with the individual runs, plans, context, tool calls, and outcomes that created them.
## What to observe
* **Runs and traces** — the request, plan, tool calls, observations, approvals, failures, and produced artifacts.
* **Usage and cost** — model and provider usage, tokens, latency, and cost over time.
* **Quality** — user feedback, eval outcomes, and judge signals.
* **Context** — the agent, instructions, data scope, files, and tools that informed a run.
## Diagnose and improve
When a result needs investigation, start from its trace. Determine whether the root cause is the data, the available context, an instruction, a tool, an access boundary, or the model’s behavior. Then create the appropriate fix and add or update an eval so the same regression is caught again.
## Governance
Control who can access agents, connections, models, and settings. Use approvals for sensitive tools; audit activity where required; and apply organization controls such as PII protection, identity integration, and service accounts.
Follow one agent run from request to outcome.
Understand adoption, spend, latency, and reliability trends.
# Quotas and usage limits
Source: https://docs.bagofwords.com/observe-and-govern/quotas-and-usage-limits
Cap monthly LLM tokens, spend, queries, and data volume per user, group, or role.
Usage policies let administrators cap how much a person can consume in a calendar month — LLM tokens, dollar spend, data-source queries, and data volume. Use them to protect budgets, contain runaway automations, and give teams predictable limits without turning agents off.
Quotas are an **Enterprise** capability (the `usage_limits` license feature). In Community Edition the quota screens are hidden and no limits are enforced. See [License Key](/enterprise/license) to activate Enterprise Edition.
## What you can limit
A usage policy sets an optional monthly cap for each of these metrics. Any field you leave blank is **unlimited** for that metric.
| Limit | Applies to | Unit in the admin UI |
| ------------------- | ------------------------------------------------------------------------------------ | -------------------- |
| Monthly token limit | Total LLM tokens (prompt + completion) across all agent activity | Tokens |
| Monthly spend limit | LLM dollar cost, computed per call from the same per-model rates as the Cost console | USD |
| Monthly query limit | Number of queries run against data connections | Queries |
| Monthly data limit | Volume of data read from connections | MB |
### Per-connection overrides
Within a policy you can override the **query** and **data volume** limits for a specific connection. This is useful when one data source is far more expensive than the rest — for example, a small default limit on all connections plus a tighter override on a metered warehouse. When both a policy-wide limit and a connection override apply, the **lower** of the two is enforced for that connection.
## The monthly window
Usage is measured over the current **calendar month in UTC**. The window opens at `00:00 UTC` on the first day of the month and counters reset automatically when the next month begins. There is no rolling window and no manual reset.
## How enforcement works
Limits are checked **before** work runs, so a request that would cross a cap is stopped rather than partially billed:
* Before each LLM call, the agent checks the token and spend caps. When a cap is reached, the run stops with an `HTTP 429` error identifying the metric, the limit, and current usage.
* Before each data query, the query-count and data-volume caps (including any per-connection override) are checked the same way.
Token and spend usage is metered per agent run and flushed when the run finishes, so a single in-flight run may edge slightly past a cap before the next request is blocked. Once a cap is hit, further requests are blocked until the next monthly window or until an administrator raises the limit.
## Create and assign a policy
Quotas are managed under **Settings → Members → Quotas**. Managing policies requires the **Manage settings** permission.
In **Settings → Members → Quotas**, choose **New quota**. Give it a name and description, then set any of the monthly limits — tokens, spend (USD), queries, and data (MB). Leave a field blank to keep that metric unlimited.
Add a per-connection override to set a different query or data limit for a specific connection within the policy.
Assign the policy to a **user**, **group**, or **role**. A member's usage is then measured against whichever policy applies to them. You can also pre-assign a policy to a pending invite from the **Members** tab or the invite dialog — it is applied automatically when the person registers.
## How the effective limit is resolved
A member may be covered by more than one policy — directly, or through their groups and roles. The effective limit is resolved in two steps:
1. **Direct assignment wins.** If one or more policies are assigned directly to the user, only those apply. Group- and role-based policies are ignored.
2. **Otherwise, inherited policies apply.** If there is no direct assignment, policies assigned to the user's groups and roles are combined.
When several policies apply at the same level, the **most restrictive** value is enforced for each metric independently — the effective cap is the lowest non-blank limit across those policies. A member with no direct, group, or role policy has **no limits** (the default).
Full administrators are subject to policies assigned to them like any other member. Assign no policy to keep an account unlimited.
## What members see
Each member can review their own consumption for the current month on their profile's **Usage** tab: used, limit, and remaining for each metric, plus a per-day breakdown from the start of the month. This is self-serve — members can see their own usage without an admin permission — and it updates as agents run.
## Auditing
Creating, updating, deleting, and assigning usage policies are recorded in the audit trail (`usage_policy.created`, `usage_policy.updated`, `usage_policy.deleted`, and `usage_policy.assigned`), capturing who made the change and when.
## Related controls
Quotas cap *cumulative monthly* consumption. To limit *burst* traffic against a single connection, use per-connection request rate limits (requests per minute, hour, or day), which are configured on the connection itself. The two controls are complementary: rate limits smooth short-term load, quotas bound the monthly total.
See also [Usage, cost, and quality](/observe-and-govern/usage-cost-quality) for the monitoring views that show where spend and volume are going before you decide where to set caps.
# Runs, traces, and diagnostics
Source: https://docs.bagofwords.com/observe-and-govern/runs-and-traces
Inspect the evidence and decisions behind an agent outcome.
Open **Monitoring** to investigate an individual run. A trace shows how the agent turned a request into an outcome: its plan, research steps, tool calls, results, clarifications, approvals, and final artifact.
Use a trace to answer practical questions:
* Which agent, data scope, instruction build, and model handled the request?
* What did the agent inspect or call in parallel?
* Which tool, query, source, or approval delayed or failed the run?
* Which evidence supported the final recommendation?
* What should be changed to prevent the issue from recurring?
For an incident investigation, traces connect the RCA narrative to the underlying logs, metrics, service tools, and database evidence rather than leaving a conclusion as an unexplained summary.
After diagnosing a recurring issue, add an [eval](/agents/evals) and improve the relevant [instruction](/agents/instructions) or agent configuration.
# Usage, cost, and quality
Source: https://docs.bagofwords.com/observe-and-govern/usage-cost-quality
Measure adoption, latency, spend, and reliability across your agent fleet.
Use the Monitoring views to understand how agents are used and how they perform over time.
Track:
* Message and run volume by agent, user, model, and time period.
* Model and provider usage, token consumption, and cost.
* Latency, tool activity, and failure rates.
* Eval outcomes, judge signals, and user feedback.
Start with aggregate trends to identify a change in adoption, spend, or reliability. Then drill into the relevant run traces to find the concrete source of the change. This is the operational feedback loop for self-improvement: observe a pattern, diagnose the cause, make a governed change, and verify it with evals.
Once you know where spend and volume are going, use [Quotas and usage limits](/observe-and-govern/quotas-and-usage-limits) to cap monthly consumption per user, group, or role.
# Quickstart
Source: https://docs.bagofwords.com/quickstart
Get started with Bag of words in minutes. Install, configure, and start chatting with your data.
## Install with Docker
You can install Bag of words with a single docker command. By default, it will use SQLite as the database.
You can also configure it to use PostgreSQL by passing `BOW_DATABASE_URL` environment variable.
```bash theme={null}
docker run --pull always -d -p 3000:3000 bagofwords/bagofwords
```
To use PostgreSQL, you need to set the `BOW_DATABASE_URL` environment variable.
For example: `BOW_DATABASE_URL=postgresql://postgres:postgres@localhost:5432/bagofwords`
## Onboarding
After installation, complete the onboarding flow to set up your AI analyst.
### 1. Welcome
Start by clicking **Next** to begin the setup process.
![Welcome to Bag of words]() ### 2. Configure LLM
Connect to any LLM provider and bring your own API key. Choose from OpenAI, Anthropic, Azure OpenAI, or Google.
![Configure LLM]() ### 3. Connect Data Source
Select one of the available data sources: PostgreSQL, Snowflake, BigQuery, MySQL, AWS Athena, Salesforce, and more.
![Connect data source]() Enter your connection details (host, port, database, credentials) and test the connection.
### 4. Select Tables
Choose which tables the AI can access and query during conversations. You can select all or specific tables based on your needs.
![Select tables]() ### 5. Add Context
Add custom instructions and enrich context to help the AI make better decisions. You can:
* **Suggest Instructions**: Add business-specific context, glossary, and code guidelines
* **Enrich Context**: Connect Git repos to load dbt/markdown resources, then toggle items to include them in AI context
![Add context]() ### 6. Start Asking Questions
Setup complete! You can now start asking questions in natural language. Create reports, dashboards, and get the data you need.
![AI Analyst ready]() Use the conversation starters or type your own questions to begin analyzing your data.
## Next Steps
**Learn how to use Bag of words:**
Learn how to ask questions and iterate on results
Build visual stories with charts and tables
Guide your AI with custom business rules
**Understand how it works:**
Learn about the governed reasoning loop and Knowledge Harness
Configure the data, tools, files, instructions, and evals for every run
# Sign-in and SSO
Source: https://docs.bagofwords.com/sign-in-and-sso
Auth modes, OIDC and Entra ID, Google, and LDAP / Active Directory
This page is about how people sign in **to Bag of words**. For how a connection authenticates to a *data source* — shared credentials versus per-user sign-in — see [Authentication and Access](/data-sources/authentication).
## Auth modes
One setting decides which sign-in methods the login page offers:
| `auth.mode` | Password form | SSO buttons |
| ------------ | ------------- | ----------- |
| `hybrid` | yes | yes |
| `local_only` | yes | no |
| `sso_only` | no | yes |
```yaml theme={null}
auth:
mode: "hybrid" # local_only | sso_only | hybrid
```
**`?local=true` is the escape hatch.** On an `sso_only` deployment, visiting `/users/sign-in?local=true` shows the password form anyway. Keep one local administrator who can use it — otherwise a misconfigured or unreachable identity provider locks everyone out, including you.
### Single-provider auto-start
When the mode is `sso_only` **and exactly one provider is enabled**, there is nothing for the user to choose, so BOW starts the round trip for them: the login page redirects straight to the provider instead of rendering a single button.
The redirect is suppressed when `?local=true` is set, or when the provider bounced back with an error — so a failed sign-in can always show you why, rather than looping.
An embedding application that already knows whose session it is opening can pass `login_hint`, which is forwarded to the provider so a browser holding several accounts doesn't stop on a chooser:
```text theme={null}
/users/sign-in?login_hint=person@company.com
```
## OIDC providers
Any OIDC-compliant provider works. Entra ID (Azure AD) and Okta are the common ones.
```yaml theme={null}
oidc_providers:
- name: entra
enabled: true
issuer: https://login.microsoftonline.com//v2.0
client_id:
client_secret: ${BOW_ENTRA_CLIENT_SECRET}
scopes: ["openid", "profile", "email"]
pkce: true
client_auth_method: post
discovery: true
uid_claim: sub
```
The `name` is the routing slug, and it determines the callback path — **register this exact URL as a redirect URI on the provider**, or sign-in fails before the login form appears:
```text theme={null}
https:///api/auth//callback
```
The sign-in button shows the provider's real name and logo — "Continue with Microsoft", not "entra". That is derived from the `issuer` URL, not from `name`, so a provider called `corp-sso` pointing at `login.microsoftonline.com` still renders as Microsoft. Issuers that aren't recognised get a neutral lock icon and their configured label.
Put `client_secret` in an environment variable or a Kubernetes Secret and reference it with `${VAR}`. Never commit it to `bow-config.yaml`.
### Group sync
Set `sync_groups: true` with a `group_claim` to map provider groups onto BOW roles. `resolve_group_names: true` turns group object IDs into readable names where the provider supports it.
## Google
```yaml theme={null}
google_oauth:
enabled: true
client_id: ${BOW_GOOGLE_CLIENT_ID}
client_secret: ${BOW_GOOGLE_CLIENT_SECRET}
```
Google appears alongside the OIDC providers in the same button list and counts toward the single-provider auto-start rule above.
## LDAP and Active Directory
LDAP requires an **Enterprise license**. See [License Key](/enterprise/license).
LDAP authenticates users against your directory and can keep group membership in sync. It is designed to **fail closed** — every condition below is required, and none of them can be turned off.
```yaml theme={null}
ldap:
enabled: true
url: ldaps://ad.company.com:636
bind_dn: cn=service-account,ou=Services,dc=company,dc=com
bind_password: ${BOW_LDAP_BIND_PASSWORD}
ca_certs_file: /run/bow/directory-ca.pem
organization_id:
admission_group_dn: cn=BOW Users,ou=Groups,dc=company,dc=com
kerberos_realm: COMPANY.COM
auto_provision_users: true
allow_local_superuser_login: false
base_dn: dc=company,dc=com
```
**A service account is required.** `bind_dn` and `bind_password` must be set — anonymous bind is not accepted. Give the account read-only lookup rights and nothing more.
**TLS is always verified.** Certificate checking cannot be disabled. Use `ldaps://` on 636, or `start_tls: true` on 389 — the connection is verified before either bind is attempted. If your directory presents a private CA, point `ca_certs_file` at the mounted bundle; leave it empty to use the system trust store.
**Admission is explicit.** A user may sign in only if they are a member of `admission_group_dn`, and each deployment admits exactly one BOW organization via `organization_id`. Nested AD group membership is resolved by AD itself, so nested groups work as your directory defines them.
**An LDAP login cannot take over a local account** that happens to share the same email address; the collision is rejected rather than merged.
**There is no password fallback during an outage.** If the directory is unreachable, directory users cannot sign in — BOW will not silently fall back to a local password. `allow_local_superuser_login: true` is the one deliberate recovery path, and it applies only to local superusers that are not linked to a directory identity.
### Group sync
Sync is scoped to the organization named by `organization_id` and only touches memberships it owns. An empty or partial directory response will not delete invited members, and a reconciliation that fails partway rolls back rather than applying half of itself.
### Delegated SQL identity
When a SQL Server connection uses per-user Kerberos delegation, the impersonated principal comes **only from a verified directory identity** — the provider, the account's SID and its subject must all match. It is never inferred from the signed-in user's email address.
`kerberos_realm` sets the AD realm explicitly, so it stays correct when your users' email or UPN suffixes differ from the realm name. See [SQL Server](/data-sources/connectors/sql-server) for the delegation setup itself.
## Sessions
Session tokens are revocable. Signing out, changing or resetting a password, and an administrator's force-signout all invalidate every token already issued to that user.
SSO does not return the session token in the redirect URL. The callback returns a single-use code, valid for 60 seconds, which the application exchanges for the token over POST — so the token never lands in a browser history, a proxy log, or a `Referer` header.
## Related
Shared credentials versus per-user sign-in, for connections rather than logins.
Where `bow-config.yaml` lives, and the Helm values that mirror it.
# Dashboard artifacts
Source: https://docs.bagofwords.com/using-bow/dashboards
Ask an agent to create, refine, share, and schedule a complete dashboard artifact.
A dashboard is an **artifact created through the conversation**. Describe the operating view you need, the agent validates the underlying evidence, and the finished dashboard opens beside the chat that produced it.
![A dashboard artifact beside the populated conversation, validation steps, share action, and weekly schedule]() ## Create a dashboard
Ask for the audience, decisions, metrics, comparisons, and operating cadence in one prompt. For example:
> Build an executive revenue and retention command center for the weekly operating review. Validate Snowflake against Power BI; show ARR, NRR, expansion, churn risk, trajectory, and regional mix; highlight actionable risks; share it with Finance; and schedule a Monday 08:00 refresh.
The agent can inspect data, reconcile measures, create the artifact, and complete sharing or scheduling steps in the same run. The conversation remains visible on the left, so the request, evidence, and changes stay attached to the result.
## Refine the artifact in chat
Continue the conversation to change the dashboard. Ask the agent to:
* add or remove a KPI, chart, table, or explanatory section;
* change the audience or level of detail;
* investigate an anomaly before updating the narrative;
* compare a different period, segment, or scenario;
* improve the visual hierarchy or presentation;
* publish a new version after the underlying logic changes.
Each change is described in natural language and applied to the artifact through the conversation.
## Review and present
Use the artifact toolbar to refresh the view, inspect versions, open it in a larger view, or share it. Keep the chat open when you need the evidence trail; use the expanded artifact view for operating reviews and presentations.
## Share and schedule
Share an artifact with the people who need the operating view and choose the appropriate visibility. Schedule recurring refreshes or delivery so the view stays current without rebuilding it each week.
When the source data or business definition changes, ask the agent to validate the difference before publishing an updated version. The report preserves the prompt and tool history behind the dashboard.
## Add interactive filters
Ask the agent to make a field a filter — "let the viewer filter by region", "add a customer selector" — and it adds a control to the top of the dashboard backed by a [parameterized query](/using-bow/parameterized-queries). Changing the control re-runs the affected queries at the source and refreshes those visualizations in place; the rest of the dashboard is untouched. Choices for a control come from a fixed list or from another query in the report, never from the rows the control filters.
## Personalize a dashboard per viewer
A dashboard can show each person their own data while everyone opens the same artifact. Bind a filter to the viewer's identity — "scope this to the signed-in user's team" — and it becomes an **identity parameter**: resolved on the server per viewer, never editable, never sent from the browser. One dashboard, and each viewer sees only their slice.
How results and credentials resolve when you share a personalized dashboard:
* **Run identity.** Choose whose credentials the viewer-triggered queries use. **Viewer** (the default for personalized dashboards) runs them under each viewer's own identity — so a source that enforces its own row-level security filters per person. **Creator** runs them under your credentials, for a dashboard everyone should see identically.
* **Per-viewer results.** Each viewer's data is computed and cached for them. Your saved snapshot is **withheld** from other viewers — no one sees the rows you last ran with.
* **Fresh on open.** Personalized dashboards re-run for the viewer when opened, so each person lands on their own current data rather than a stale shared snapshot.
* **Hide the underlying data.** You can hide the **Data** tab on a shared report so viewers see the dashboard without the raw query results behind it.
For a source that already models per-user visibility (a Power BI tenant with RLS, a warehouse with row-level security), personalize with a **per-user connection** and **Viewer** run identity, so the source filters under each person's own credentials. An identity parameter alone scopes by a value Bag of words resolves from the profile — use it for application-level slicing, not as a replacement for source-enforced security. See [Authentication](/data-sources/authentication).
## Preview as another viewer
Before you share, check what someone else will see. **View as** re-renders the dashboard as another organization member — searchable by name or email — or as an anonymous viewer, so you can confirm a personalized dashboard is scoped the way you intended.
On a **per-user (delegated)** source such as Power BI or Fabric, View-as swaps the identity used for parameter binding but keeps **your** source credentials — using the target's stored token would be impersonation. So the preview shows *your* source-level rows under their identity binding. To verify the exact rows another person gets from a delegated source, have them open the shared dashboard themselves. Bag of words shows an amber caveat on the control in this case.
Ask for the “so what,” not only the charts. A strong dashboard prompt requests exceptions, risk signals, decisions, and recommended actions alongside the metrics.
# BOW for Excel
Source: https://docs.bagofwords.com/using-bow/excel
Ask Bag of words questions from inside Excel and drop AI-generated results straight into cells
## Overview
Bag of words ships a built-in Excel add-in that runs entirely from your own instance. Users can ask BOW questions about their data from inside an Excel taskpane and paste AI-generated results directly into the spreadsheet — with headers, formatting, and borders applied automatically.
The add-in works in Excel for Windows, Excel for Mac, and Excel on the web.
## How It Works
Your BOW instance serves the add-in from two endpoints:
| Endpoint | Description |
| ---------------------- | --------------------------------------------------------------------------- |
| `/excel/manifest.xml` | The Office Add-in manifest, dynamically configured with your instance's URL |
| `/excel/taskpane.html` | The add-in UI that loads BOW inside Excel's task pane |
Icon assets are served from `/icons/excel/`. Because the manifest is generated per-instance, each BOW deployment hosts its own add-in — there's no central plugin catalog to register with.
## Setup
### 1. Download the Manifest
Go to **Settings** → **Integrations** → **Excel Add-in** and click **Download manifest.xml**.
### 2. Upload It in Excel
Open Excel (desktop or web), go to **Home** → **Add-ins** → **More Add-ins**, then click **Upload My Add-in** and pick the `manifest.xml` you just downloaded.
### 3. Open BOW from the Ribbon
A **BOW** button appears in the **Home** tab. Click it to open the taskpane and sign in with your normal BOW credentials.
## Tenant-wide Deployment
For organization-wide rollout, your Microsoft 365 admin can upload the manifest via **Admin Center** → **Settings** → **Integrated apps** — no per-user sideloading needed. Every user in the tenant gets the BOW button in their Excel ribbon automatically.
## What the Add-in Does
* **Opens BOW in Excel's side panel** — the full web app, embedded in the taskpane
* **Sends the current cell selection to BOW** for context-aware analysis
* **Pastes AI-generated results into the spreadsheet** with headers, formatting, and borders applied automatically
Users can override the BOW URL via the settings gear in the taskpane if they need to point the add-in at a different instance.
## Configuration
The add-in reads `base_url` from your BOW config (`bow-config.yaml`) to generate all URLs in the manifest. No additional configuration is needed — deploy and go.
# Models and LLM providers
Source: https://docs.bagofwords.com/using-bow/llm
Bring your preferred models, route work intentionally, and keep a reliable fallback path.
Bag of words is model-flexible. Add the providers and models your organization approves, configure credentials, set access, and choose how the platform selects a model for each task.
## Choose a model strategy
Your organization can use one model for everything, or offer a governed catalog with different strengths and cost profiles. Model settings expose the capabilities that matter for agent work, including context window, vision, reasoning support, and structured output.
* **Automatic routing** selects an appropriate available model for the task.
* **Explicit selection** lets people choose from the models they are allowed to use.
* **Fallback chains** keep work moving when a preferred model is unavailable.
The active model is visible in the chat experience. Administrators manage the catalog and credentials in the LLM settings area.
![The current model selector inside a chat session]() ## Route models inside a chat
The composer shows the model that will handle the next turn. Select it to choose from the models enabled for your organization. The selection stays with the report, so follow-up work uses the intended model unless you change it or use automatic routing.
Use **Auto** when routing is enabled and you want Bag of words to choose from the approved catalog for the task. Use an explicit model when the session needs a predictable reasoning, latency, or cost profile. Organization defaults and fallback behavior still apply if the preferred model is unavailable.
## Add providers and credentials
1. Open **Settings → LLMs**.
2. Add an approved provider and its API credentials, or configure an organization endpoint.
3. Enable the models you want to make available and review their capability metadata.
4. Set organization-wide defaults, routing, and fallback behavior.
5. Assign access so people see only the models they are permitted to use.
The exact models shown in the interface depend on your deployment and the providers your administrator has enabled. Keep model and credential access under the same governance standards as your data connections.
## Custom headers and identity forwarding
If your LLM traffic goes through a gateway or proxy (for routing, cost attribution, or audit), each provider can attach extra HTTP headers to every request it sends. Open the provider from **Settings → LLMs** and expand **Custom headers**. The section is not shown on the initial onboarding form — edit the provider after it is created.
There are two kinds of headers:
* **Static headers** are fixed key/value pairs sent on every request to that provider — for example a gateway routing key or a cost-center tag.
* **Identity forwarding** rules send the signed-in user's identity as headers, so a gateway can attribute cost or apply policy per user. Each rule names a header and picks a source.
Sources are drawn from a fixed list — never arbitrary user input:
| Source | Value |
| ----------------------- | --------------------------------------------------------------------------------------------------------------- |
| `user.email` | The user's email address |
| `user.name` | Their display name |
| `user.id` | Their Bag of words user id |
| `membership.role` | Their role in the organization |
| `membership.attr:` | An SSO profile attribute, e.g. `membership.attr:department` |
| `static:` | A fixed string, with `{...}` placeholders for any of the above, e.g. `static:acme\{membership.attr:employeeId}` |
### SSO profile metadata
`membership.attr:` reads the profile metadata synced from your identity provider when the user signs in. Enable profile sync and choose which fields to store under **Settings → Identity**; only synced fields have a value at request time.
| Identity provider | Fields available |
| ------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Microsoft Entra ID | `jobTitle`, `department`, `companyName`, `officeLocation`, `employeeId`, `employeeType`, `employeeHireDate`, `employeeOrgData`, `mobilePhone`, `city`, `state`, `country`, `usageLocation`, `preferredLanguage` |
| Google | `displayName`, `jobTitle`, `department`, `organization`, `location`, `locale`, `hostedDomain` |
For example, to let a gateway split spend by department and person:
```text theme={null}
X-User-Email: user.email
X-Department: membership.attr:department
X-Cost-Center: static:{membership.attr:companyName}/{membership.attr:department}
```
How the headers are resolved:
* Static headers are applied first, then forwarding rules. A rule that targets the same header name as a static header wins.
* A rule whose value is empty for the current user (for example, an attribute that was never synced) is left out rather than sent blank.
* Forwarding rules only resolve inside a user-triggered run. Requests made outside one — testing the connection, scheduled jobs — carry the static headers only.
* Header names must be valid HTTP tokens, values are trimmed to a single line, and a provider can have at most 24 headers and rules combined.
The same identity sources are available for [MCP connections](/data-sources/user-context), so a gateway that already receives them from MCP tool calls can reuse the same header names here.
## Use the right model for the work
Use high-reasoning models for complex investigations and root-cause analysis, faster models for straightforward exploration, and capable multimodal models when the task includes files or images. Agent tools, instructions, data access, and evaluations stay independent of the selected model, so you can improve or change the model layer without rebuilding your agent design.
See how models fit alongside an agent's tools, data, instructions, and evaluations.
# MCP
Source: https://docs.bagofwords.com/using-bow/mcp
Connect Claude, Cursor, or any MCP client to query your data via the Bag of words MCP Server
## Overview
Bag of words exposes an MCP (Model Context Protocol) server that allows you to connect external AI tools like Claude Desktop, Cursor, or any MCP-compatible client directly to your data sources. This enables you to query your data using natural language from your favorite AI tools.
With the MCP Server, you can:
* **Query data from Claude Desktop**: Ask questions about your data directly in Claude
* **Use Cursor for data analysis**: Leverage your IDE's AI capabilities with your connected data sources
* **Integrate with any MCP client**: Build custom workflows using the standardized MCP protocol
## Available Tools
The Bag of words MCP Server exposes the following tools for AI assistants to interact with your data:
| Tool Name | Description |
| -------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `create_report` | Creates a new analysis session (report). Call this at the start of a conversation to get a report\_id for subsequent tool calls. Auto-attaches all active data sources. |
| `get_context` | Retrieves available data sources, tables, and metadata resources. Useful for understanding what data is available before running queries. Supports optional regex pattern filtering. |
| `inspect_data` | Quick, ephemeral data inspection for exploration and debugging. Previews data (head/tail), checks column types, and validates assumptions. Results are logged but not saved as persistent visualizations. Returns a sample of 3 rows. |
| `create_data` | Creates tracked, reproducible data visualizations (chart or table) with Query/Step/Visualization persistence. Results are saved to the report and can be shared/added to dashboards. Tables are auto-discovered from the prompt if not provided. |
| `list_instructions` | Lists instructions from the current live build. Instructions are organizational knowledge that guide AI behavior. Supports filtering by status, category, and text search. |
| `create_instruction` | Creates a new instruction that guides AI code generation and data analysis. Auto-versioned with build integration. Admins get instant approval; non-admins go to pending approval. |
## Enable MCP Server
Administrators can enable or disable the MCP endpoint from **Settings** → **Integrations**.
![MCP Server Integration Toggle]() Toggle the **BOW MCP Server** switch to enable MCP endpoint for integration with AI assistants like Cursor, Claude, or others.
## Getting Started
### 1. Access the MCP Configuration
Click **MCP** in the left navigation menu to open the MCP Server configuration popup.
![MCP Server Configuration]() ### 2. Generate an Access Token
Click **Regenerate Token** to create a new access token. This token authenticates your MCP client with Bag of words.
Keep your access token secure. Anyone with this token can query your data sources through the MCP server.
### 3. Configure Your MCP Client
Copy the configuration snippet and add it to your MCP client's configuration file. The configuration looks like this:
```json theme={null}
{
"mcpServers": {
"bagofwords": {
"url": "https:///mcp",
"headers": {
"Authorization": "Bearer "
}
}
}
}
```
Replace `` with your Bag of words instance URL and `` with your actual access token.
## Client Configuration
### Claude Desktop
Add the configuration to your Claude Desktop settings file:
**macOS**: `~/Library/Application Support/Claude/claude_desktop_config.json`
**Windows**: `%APPDATA%\Claude\claude_desktop_config.json`
### Cursor
Add the configuration to your Cursor MCP settings to enable data querying directly from your IDE.
### Custom MCP Clients
Any client that supports the MCP protocol can connect using the URL and authorization header shown in your configuration panel.
## MCP Reports
Reports created through MCP connections are automatically tracked in your Reports page and marked with an MCP icon for easy identification.
![MCP Reports]() When you open an MCP-generated report, you'll see a banner indicating it was created via MCP. The report displays the generated data and visualizations from the tool calls made by the external AI assistant.
![MCP Report View]() **Important**: For MCP-generated reports, the actual LLM completion/prompt content is **not saved**, but all tool usage is **tracked 100%**.
This means you can see exactly what data was queried and which tools were used, while the conversational context from the external client (Claude, Cursor, etc.) remains private.
## Managing API Tokens
You can manage multiple access tokens from the MCP configuration panel:
* **View active tokens**: See all tokens created for your workspace with their creation dates
* **Regenerate tokens**: Create new tokens when needed
* **Revoke tokens**: Remove tokens that are no longer needed for security
## Use Cases
### Data Analysis in Claude
Once connected, you can ask Claude questions about your data:
* "What were our top 10 customers by revenue last month?"
* "Show me the trend of user signups over the past year"
* "Which products have the highest return rate?"
### Development Workflows in Cursor
Use the MCP integration while coding to:
* Validate data assumptions while building features
* Generate test data based on production patterns
* Debug data-related issues with real-time queries
* Build data models with full context of the data warehouse
# Parameterized queries
Source: https://docs.bagofwords.com/using-bow/parameterized-queries
Declare inputs on a query so a dashboard can filter it, and bind inputs to the viewer's identity for per-person data.
A parameterized query is a tracked query that declares one or more **inputs**. Instead of hard-coding a region or a customer into the SQL, the query leaves a slot the dashboard fills in — from a control the viewer changes, or from **who the viewer is**. The query re-runs at the source with the new value, so the numbers are always computed on live data, not filtered client-side.
This is the mechanism behind [interactive and personalized dashboards](/using-bow/dashboards#personalize-a-dashboard-per-viewer): a control on the dashboard sets a parameter, and every artifact bound to that parameter re-runs.
## Declaring a parameter
Ask the agent for it in plain language — "make region a filter", "scope this to the signed-in user's team" — and it declares the parameter when it builds the query. You can also review and adjust declarations in the query editor's **Params** panel, beside the SQL.
Each parameter has:
| Field | What it is |
| ------------ | -------------------------------------------------------------------------------------- |
| **name** | The identifier used in the SQL placeholder, e.g. `region`. |
| **type** | `string`, `number`, `boolean`, or `list` (a multi-select that binds an array). |
| **label** | The human label shown on the control. |
| **required** | Whether a value must be present for the query to run. |
| **default** | The value used when the viewer hasn't chosen one. |
| **source** | Where the value comes from — see [the three sources](#where-a-value-comes-from) below. |
## Using a parameter in SQL
Reference a parameter with a colon placeholder — `:region`. Bag of words binds the value safely (never string-substituted), so a parameter can't be used for SQL injection.
```sql theme={null}
SELECT id, region, amount
FROM sales
WHERE (:region IS NULL OR region = :region)
```
The `(:region IS NULL OR region = :region)` shape is the idiom for an **optional** filter: when the control is set to a value, only those rows return; when it's cleared (`NULL`), all rows return. A `list` parameter uses `IN` instead:
```sql theme={null}
WHERE (:regions IS NULL OR region = ANY(:regions))
```
Each connector binds parameters in its own dialect — a DAX measure filter for Power BI, a bound parameter for SQL sources. You write the query in the source's language; the placeholder is the same `:name` everywhere.
## Where a value comes from
Every parameter draws its value from one of three sources. This is the setting that turns an ordinary filter into a personalized one.
The viewer sets it from a control on the dashboard. A plain interactive filter.
The value is bound to the viewer's identity and resolved server-side per person. It is never editable and never sent from the browser.
Defaults to the viewer's identity, but the viewer can override it with a control — personal by default, explorable when allowed.
An **identity** parameter is what makes one shared dashboard show each person their own slice: bind `team` to the viewer's team and everyone opens the same artifact but sees only their team's rows. Because identity parameters resolve on the server, a viewer cannot read or change another person's value. See [personalization](/using-bow/dashboards#personalize-a-dashboard-per-viewer).
An identity parameter scopes data by a value Bag of words resolves from the viewer's profile. It is **not** a substitute for source-enforced security on sources that already model per-user visibility (a Power BI tenant with RLS, a warehouse with row-level security). For those, use a [per-user connection](/data-sources/authentication) so the source filters under each viewer's own credentials.
## Giving a control its choices
A control that offers a fixed set of values needs to know that set. There are two ways to supply it, and one rule.
* **Static options** — a list you declare on the parameter (`Rock`, `Jazz`, `Classical`).
* **Options source** — another query in the same report supplies the choices: point the parameter at that query and name its value and label columns. A `Genres` query can feed the genre control of an `Albums by Genre` query.
A control must **never** derive its choices from the rows it filters. Selecting a value would then collapse the list to just that value. Always supply choices from a static list or a separate options-source query — the "filter-space" pattern — so the full set of choices stays stable as the viewer selects.
## What the viewer experiences
On a dashboard, each declared `input` parameter renders as a control at the top of the artifact. Changing it re-runs the consuming queries and refreshes the affected visualizations in place — the rest of the dashboard is untouched. Identity parameters render as a read-only "scoped to you" note rather than a control.
Results are cached per viewer and per set of values, so re-opening a dashboard with the same inputs is instant, while a new combination runs fresh.
## Related
Interactive controls, per-viewer personalization, and View-as.
Per-user connections, so a source enforces its own row-level security.
# Chat with your data
Source: https://docs.bagofwords.com/using-bow/reports
Prompt governed agents for questions, advanced analysis, root-cause investigation, and artifacts.
Reports are persistent conversations with governed agents. A report keeps your prompts, tool activity, results, artifacts, and follow-up context together so you can refine the work without starting over.
![A detailed root-cause prompt followed by parallel investigation, a note tool, and a Mermaid dependency map]() ## Choose the mode
* **Chat** is for doing production work with approved instructions and access.
* **Training** is for learning sources, clarifying business rules, and proposing reviewable instruction changes.
Switch modes in the composer. Training changes do not silently become production behavior; review and accept the proposed instruction edits first.
## Write a strong prompt
A useful prompt states the outcome, evidence boundary, validation standard, and deliverable. You do not need to prescribe every query or tool call.
> Show weekly net revenue retention for enterprise customers in Q2. Use the approved account and fiscal-period definitions, exclude test accounts, compare the result with the Power BI executive measure, and return a table plus a short explanation of any mismatch.
> Act as a senior finance analyst. Explain why enterprise ARR growth slowed in Q2 despite higher bookings. Compare plan versus actual by region and segment; separate volume, price, churn, timing, and FX effects; identify the five accounts driving the variance; validate every number against Snowflake and Power BI; and finish with an executive summary and recommended actions.
> Investigate the checkout failures that began this morning. Correlate deployments, traces, logs, and SQL Server telemetry in parallel. Keep an investigation note, draw the dependency path, quantify impact, rule out plausible alternatives, and finish with the root cause and prevention actions.
> Build an executive revenue and retention command center for the weekly operating review. Validate Snowflake against Power BI; show ARR, NRR, expansion, churn risk, trajectory, and regional mix; highlight actionable risks; share it with Finance; and schedule a Monday 08:00 refresh.
## Follow the agentic loop
The run timeline shows how the agent moves from request to result:
1. It plans the investigation and selects scoped context.
2. It runs independent checks in parallel where possible.
3. It observes tool results, validates evidence, and records useful intermediate state.
4. It reflects, retries, or asks for clarification when evidence is incomplete.
5. It returns a conclusion, data result, or artifact with its work visible.
For complex work, ask for a **note** to maintain hypotheses, open questions, and next actions. Ask for a **Mermaid** diagram to make dependencies, flows, or incident timelines explicit.
## Iterate without repeating context
Follow up in the same report to narrow a period, add a comparison, challenge an assumption, or change the deliverable. Useful follow-ups include:
* “Re-run this at constant currency and explain what changed.”
* “Rule out the payment provider with trace evidence.”
* “Turn the conclusion into an executive dashboard artifact.”
* “Save the clarified service-start rule as a proposed instruction.”
## Select a model in the conversation
The composer shows the active model. Choose another enabled model for the session when you want a different speed, cost, or reasoning profile; automatic routing can select for you when it is enabled by an administrator.
![The current in-chat model selector with configured reasoning and fast models]() Use business language and desired outcomes. The agent uses scoped schemas, semantic objects, files, APIs, tools, and [instructions](/agents/instructions) to determine the implementation details.
# AI Settings
Source: https://docs.bagofwords.com/using-bow/settings
Configure AI capabilities and behavior for your organization
Control how the AI agent behaves across your organization. These settings are available to admins only.
* **Allow LLM to See Data**: Enable the AI to view sample data from tables for better context and more accurate analysis.
If false, the system will use metadata only
* **Allow File Upload**: Let users upload spreadsheets (xls/csv) and PDFs. The AI will parse and incorporate the data into analysis.
When file upload is allowed, the LLM will see the data of the file (for indexing) - this cannot be avoided.
* **Allow Users to Edit and Execute LLM Generated Code**: Users can view, edit, and run the SQL or Python code generated by the AI. Useful for advanced users who want more control.
* **Enable LLM Judge**: The AI evaluates query quality for accuracy, efficiency, and best practices. Provides feedback to improve results over time.
* **Autogenerate Instructions**: Automatically suggest saving user clarifications as instructions. For example: "Active users should exclude test accounts" becomes a suggested instruction.
Suggested instructions require admin approval before becoming active.
* **Validate Code**: Automatically validate AI-generated code for syntax errors, security issues, and schema correctness before execution.
* **Limit Analysis Steps** (Default: 6): Controls how many sequential steps (queries, visualizations, calculations) the AI can take to answer a question.
* **Limit Code Retries** (Default: 3): Limits how many times the AI can retry code generation after failures to prevent infinite loops.
* **Top K schema**: Set how many schema tables are expanded and included in the initial system prompt.
* **Top K metadata resources**: Set how many metadata resources (dbt, markdown, etc.) are expanded and shown in the initial system prompt.
# Work with agents
Source: https://docs.bagofwords.com/work-with-agents
Use governed agents for everyday questions, advanced investigations, recurring workflows, and shareable artifacts.
Use Bag of Words agents wherever work begins: in the web app, through scheduled and event-driven workflows, in team channels, from Excel, or through the BOW MCP gateway.
## Chat mode
Use **Chat** mode for production work: answer a focused question, investigate an exception, perform advanced analysis, or create an artifact such as a dashboard or document. The agent selects relevant context, runs tools, and shows its work in the conversation.
For challenging work, give the agent the decision, evidence boundary, validation standard, and desired output. It can split independent checks across tools, keep a note as a scratchpad or to-do list, reflect on gaps, and render Mermaid diagrams when relationships are easier to understand visually.
![A production root-cause investigation with parallel tool work, an investigation note, and a rendered Mermaid dependency map]() ## Training mode
Use **Training** mode to teach and improve an agent safely. Ask it to learn connected sources, inspect table grains and joins, reconcile important calculations, clarify ambiguous business rules, and propose a comprehensive instruction set. Proposed changes remain reviewable before they affect Chat mode.
![Training mode inspecting Snowflake and Power BI before proposing a comprehensive, reviewable instruction set]() Chat uses approved knowledge to do the work. Training inspects evidence and proposes changes to the knowledge harness. Keep production questions in Chat and agent-improvement work in Training.
## Advanced analysis and RCA
For a complex question, describe the decision or incident rather than prescribing every query. The agent can assemble evidence across scoped sources and deliver a structured, defensible conclusion.
For example, a revenue review can combine invoicing, cash collection, budgets, and customer concentration. A production root-cause analysis can correlate deployment history, service logs, metrics, traces, tickets, and database evidence to identify impact, timeline, cause, and prevention actions.
Use **notes** as an investigation scratchpad: record hypotheses, evidence still needed, and next actions while the agent works. For relationships and incident timelines, ask the agent to render a **Mermaid** diagram alongside the written conclusion and dashboard artifacts.
![Advanced financial analysis with a detailed prompt, visible tool steps, validated findings, and recommended actions]() ## A strong prompt pattern
Include four things when the result matters:
1. **Goal:** the decision, question, or incident to resolve.
2. **Evidence:** the sources and dimensions to inspect, plus any exclusions.
3. **Validation:** how to reconcile results and what uncertainty to surface.
4. **Deliverable:** the format, level of detail, audience, and next actions.
For example:
> Act as a senior finance analyst. Explain why enterprise ARR growth slowed in Q2 despite higher bookings. Compare plan versus actual by region and segment; separate volume, price, churn, timing, and FX effects; identify the five accounts driving the variance; validate every number against Snowflake and Power BI; and finish with an executive summary and recommended actions.
## Turn work into repeatable workflows
Save and share reports, add results to dashboards, organize work in projects, and schedule recurring tasks. Triggers can start an investigation from an event or webhook. Use channels and the BOW MCP gateway when people need the same governed agents outside the web app.
Ask questions, analyze evidence, and create artifacts.
Assemble and share visual operating views.