> ## Documentation Index
> Fetch the complete documentation index at: https://docs.bagofwords.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Root cause analysis across observability tools
> Build one agent that searches Elasticsearch, Prometheus, Kubernetes and Splunk from an alert: train it on how your data fits together, give it a playbook, and get a root cause with evidence from every source.
When an alert fires, the answer is usually spread across several tools: the deploy in one, the crashing pods in another, the errors in a third. This guide builds one agent that searches all of them, knows how they connect, and follows your team's playbook. You paste the alert and get a timeline, a root cause and the evidence for it.
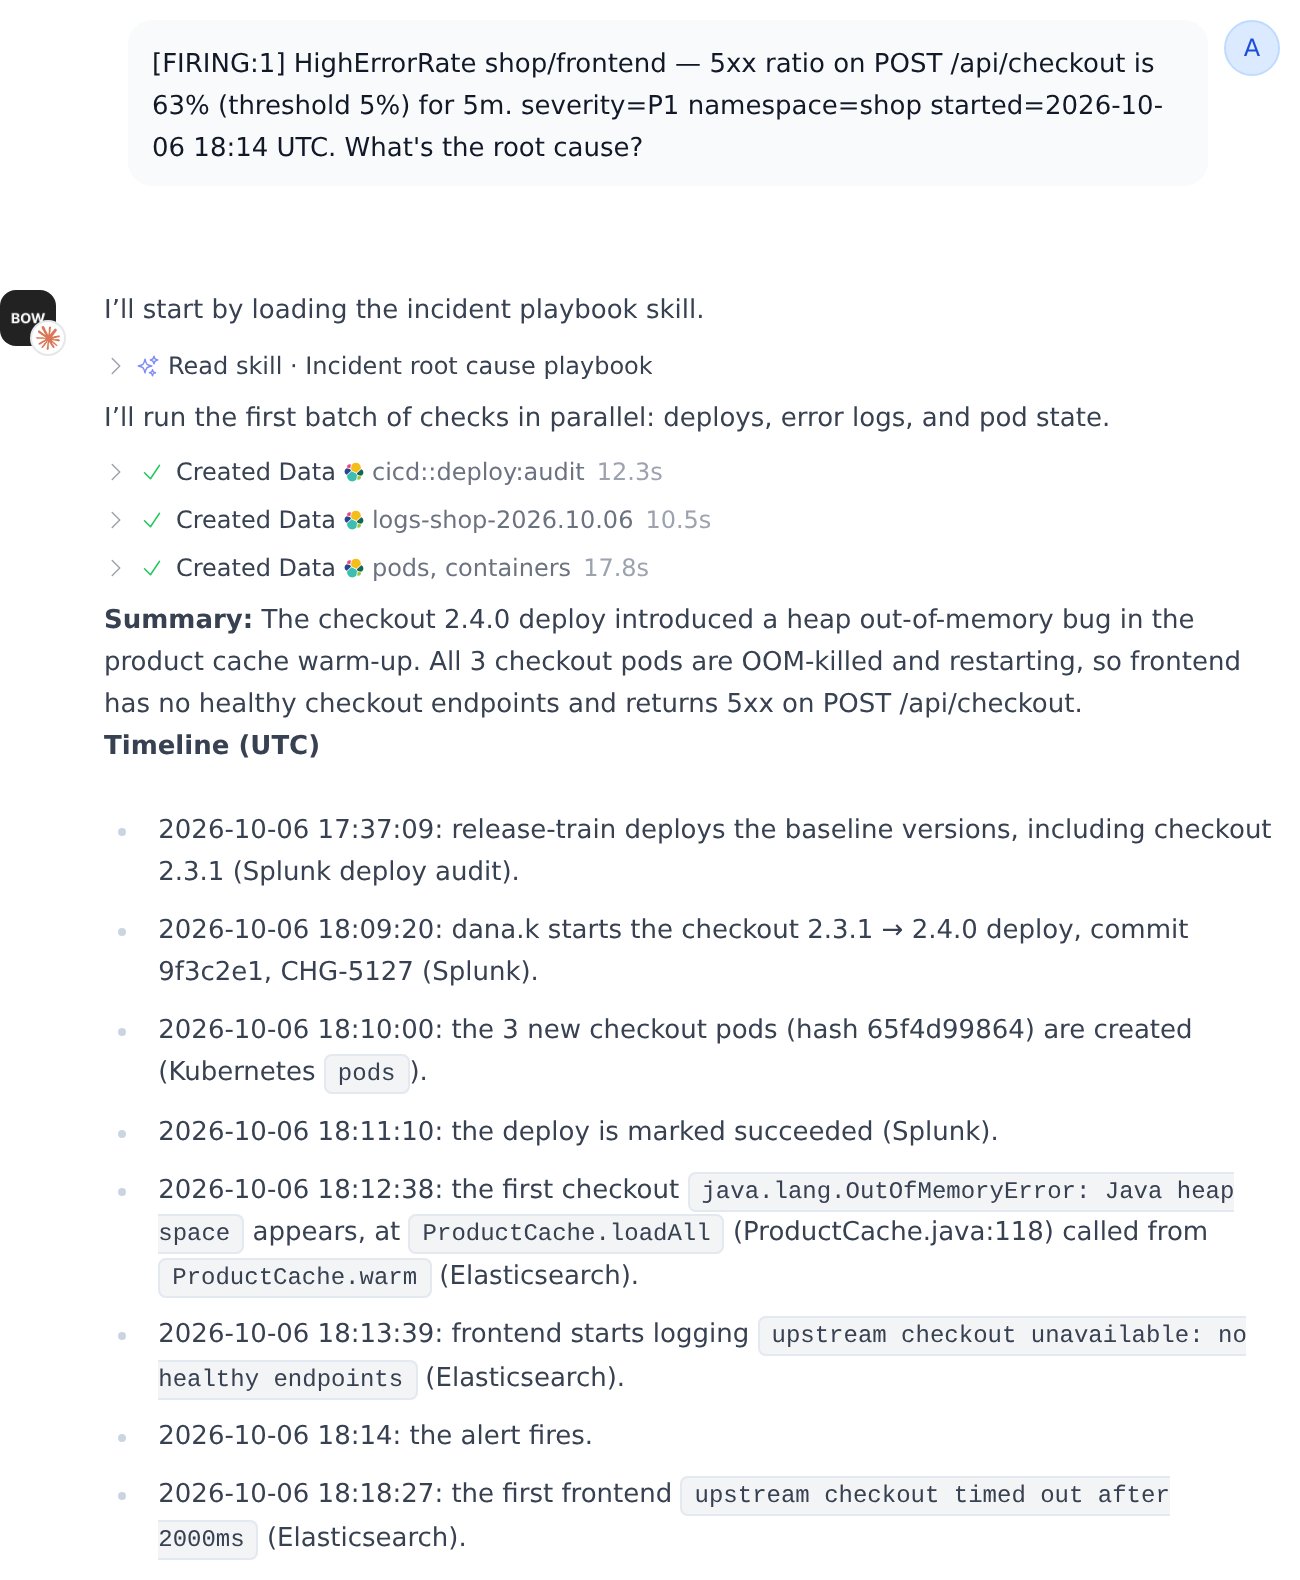 The example uses a shop running on Kubernetes, with application logs in Elasticsearch, metrics in Prometheus, and ingress logs and a deploy audit log in Splunk. A new checkout release ran out of memory, and the frontend started returning 5xx errors. The same steps work with any mix of the [observability connectors](/data-sources/connectors/observability) and [Kubernetes](/data-sources/connectors/kubernetes).
The agent learns two kinds of knowledge, from two places:
| Knowledge | Example | Where it comes from |
| - | - | - |
| **Structure** | "A pod has the same name in Elasticsearch, Prometheus and Kubernetes." | The agent samples your data in a training session. |
| **Procedure** | "For 5xx errors, group the error logs first, then check the upstream's pods." | You write it once, as a playbook every agent can use. |
## Before you start
* **You can connect each tool read-only.** Each connector page lists the credentials it needs. The Kubernetes connector uses a read-only service account; the others take an API key, a token or a read-only user.
* **You manage agents.** Creating agents and accepting training changes needs the manage permission on the agent.
## Step 1: Create the agent and pick its data
Add a connection for each tool, then create one agent that uses all of them. One agent matters here: following an alert from the deploy to the pods to the logs only works if a single agent can see every source.
Open **Agents → New → Agent**. Enter a **Name**, such as *Incident RCA*, and pick all four connections under **Connections**. You can create a missing connection from the same picker with **Create new connection**.
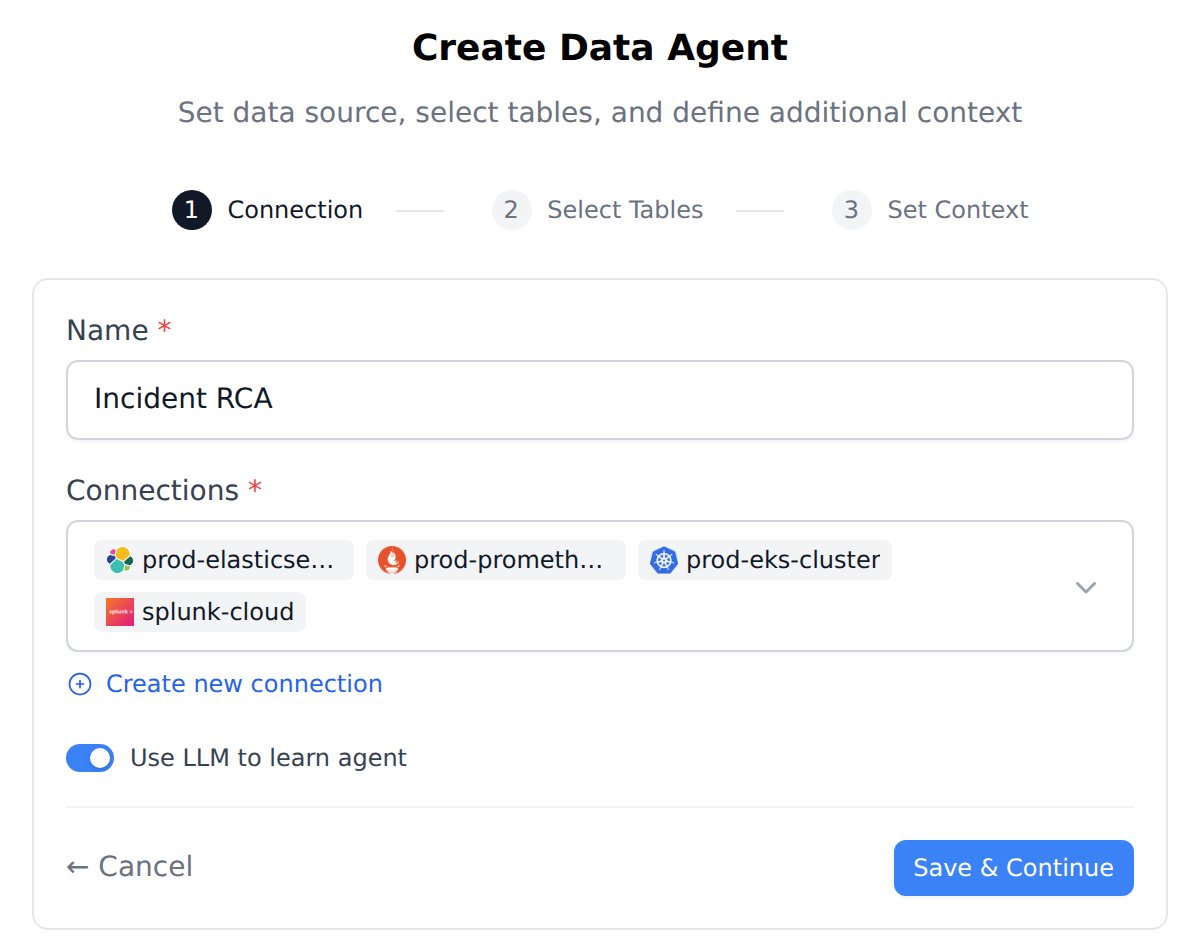 Click **Save & Continue**. On **Select tables**, enable only what an investigation needs. Observability tools expose far more than that: here, Prometheus alone listed over 300 metrics, most of them its own internals.
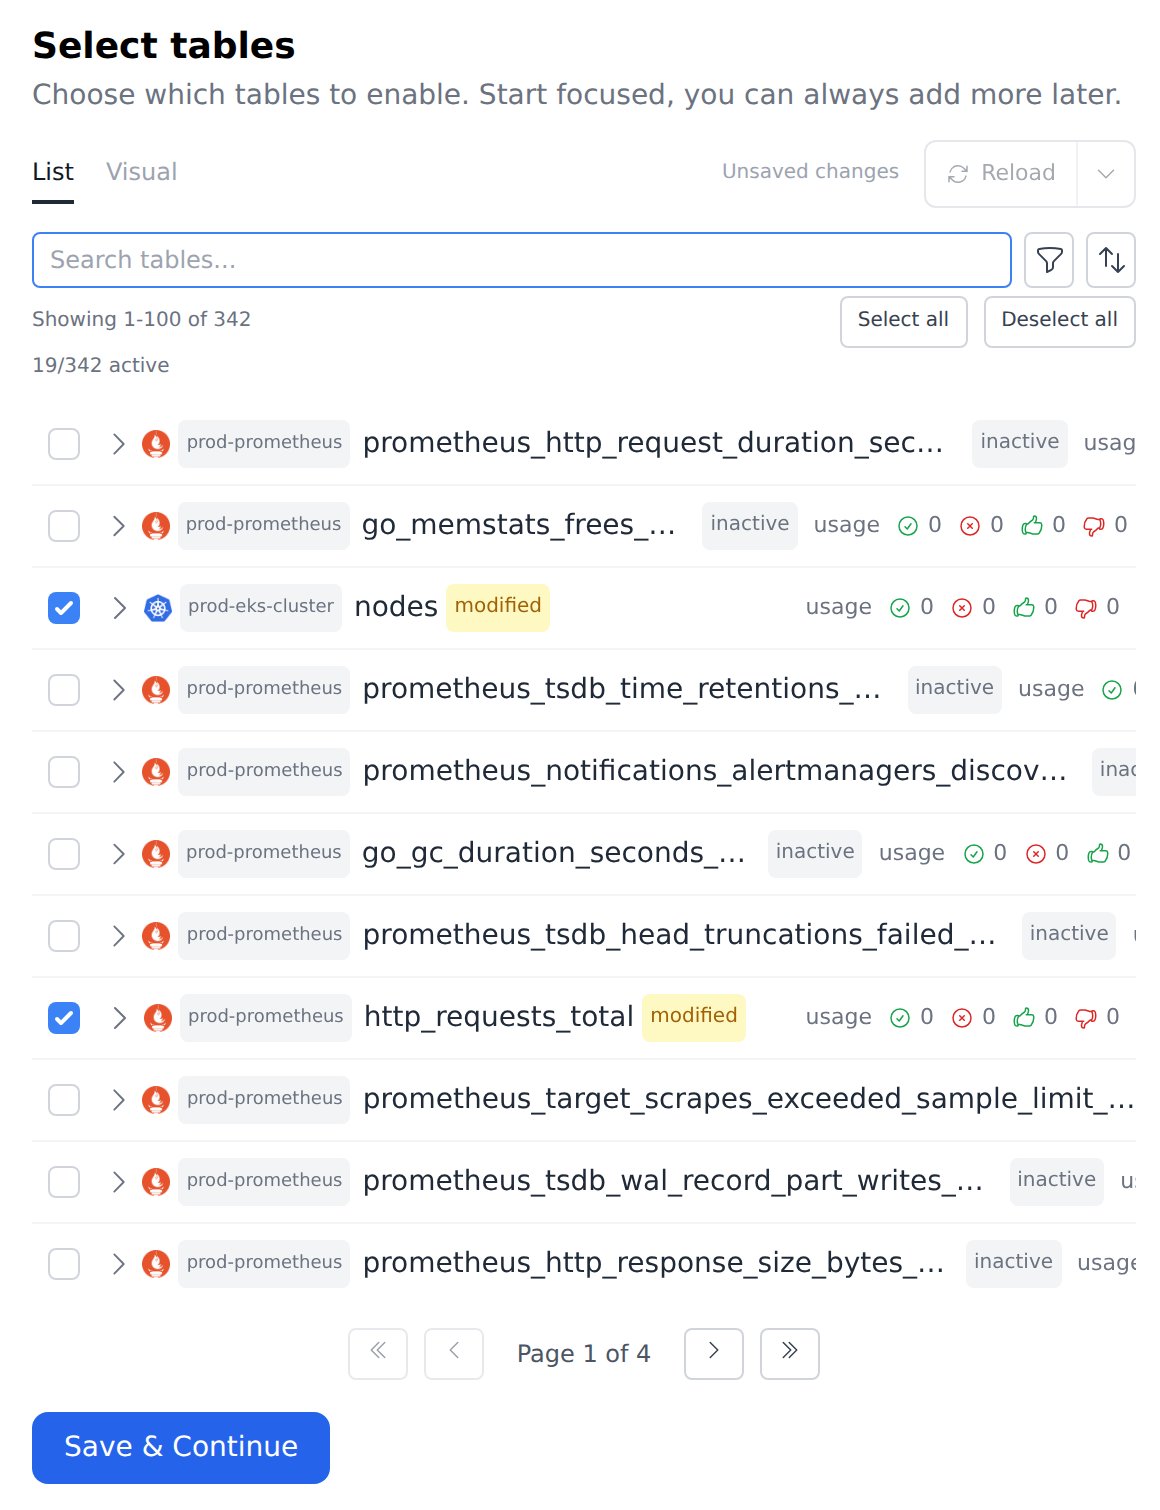 What to enable in each source:
| Source | Enable |
| - | - |
| Elasticsearch | Your application log indices. Daily indices such as `logs-shop-2026.10.06` are collected into one table when more than one day exists. |
| Prometheus | Request counters and latency histograms (`http_requests_total`, `http_request_duration_seconds_*`), container memory and limits, restarts and OOM counters, available replicas. |
| Kubernetes | `pods`, `containers`, `deployments`, `replicasets`, `events`, `services`, `nodes` and `logs`. |
| Splunk | The ingress or access-log sourcetype and the deploy audit sourcetype. |
Click **Save & Continue**. On **Set Context**, BOW drafts an overview from samples of your data. Keep it to a short description of what the agent is for. The training session in Step 2 adds the details, with evidence.
## Step 2: Train the agent on how your data fits together
Start a new report with the agent and switch the mode from **Chat** to **Training**. Then ask the agent to inspect every source before it writes anything:
> Inspect each of the four sources before we write anything. For each one, sample recent data and tell me where things live (index, metric, table or sourcetype), how a service, a pod and a point in time are identified, and which fields matter for errors, latency, restarts and deploys. Then map how the same service and pod show up across all four sources, check that mapping against the actual data (for example, do the pod names and IPs match?), and propose instructions for what you learn.
The agent samples each source in parallel, checks the joins, and writes up what it found. In this run it confirmed that pod names match across Elasticsearch, Prometheus and Kubernetes. It found that the ingress logs only cover the frontend, and that the `upstream_addr` field is the frontend pod's IP with `:8080` added.
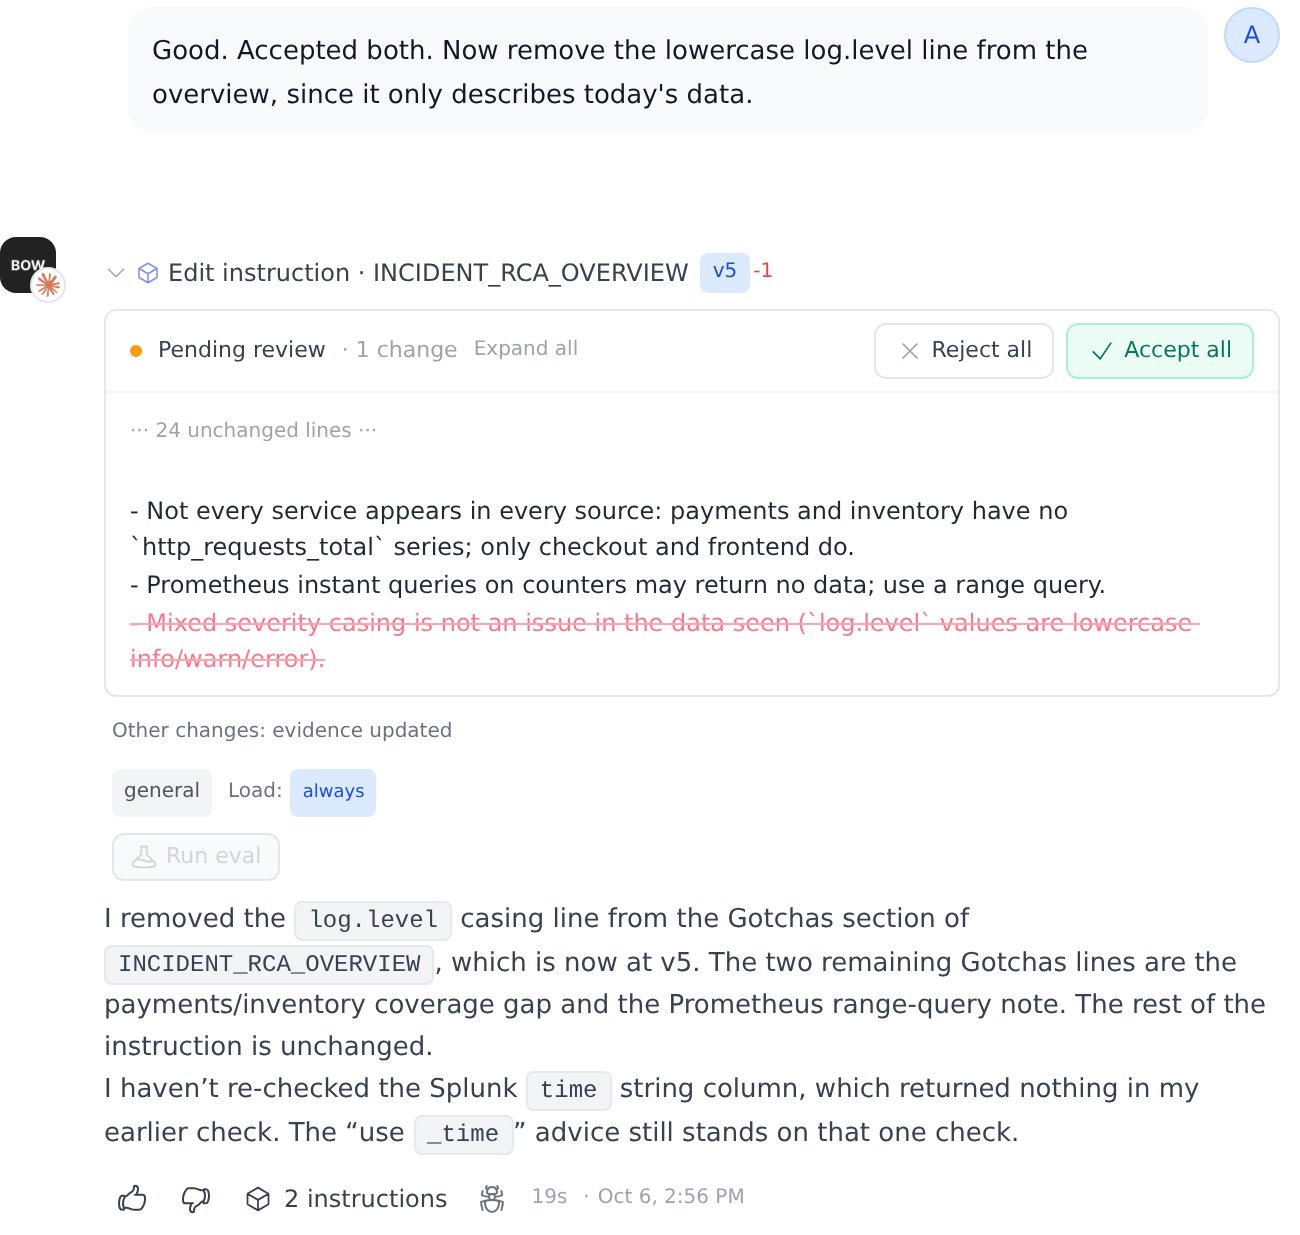
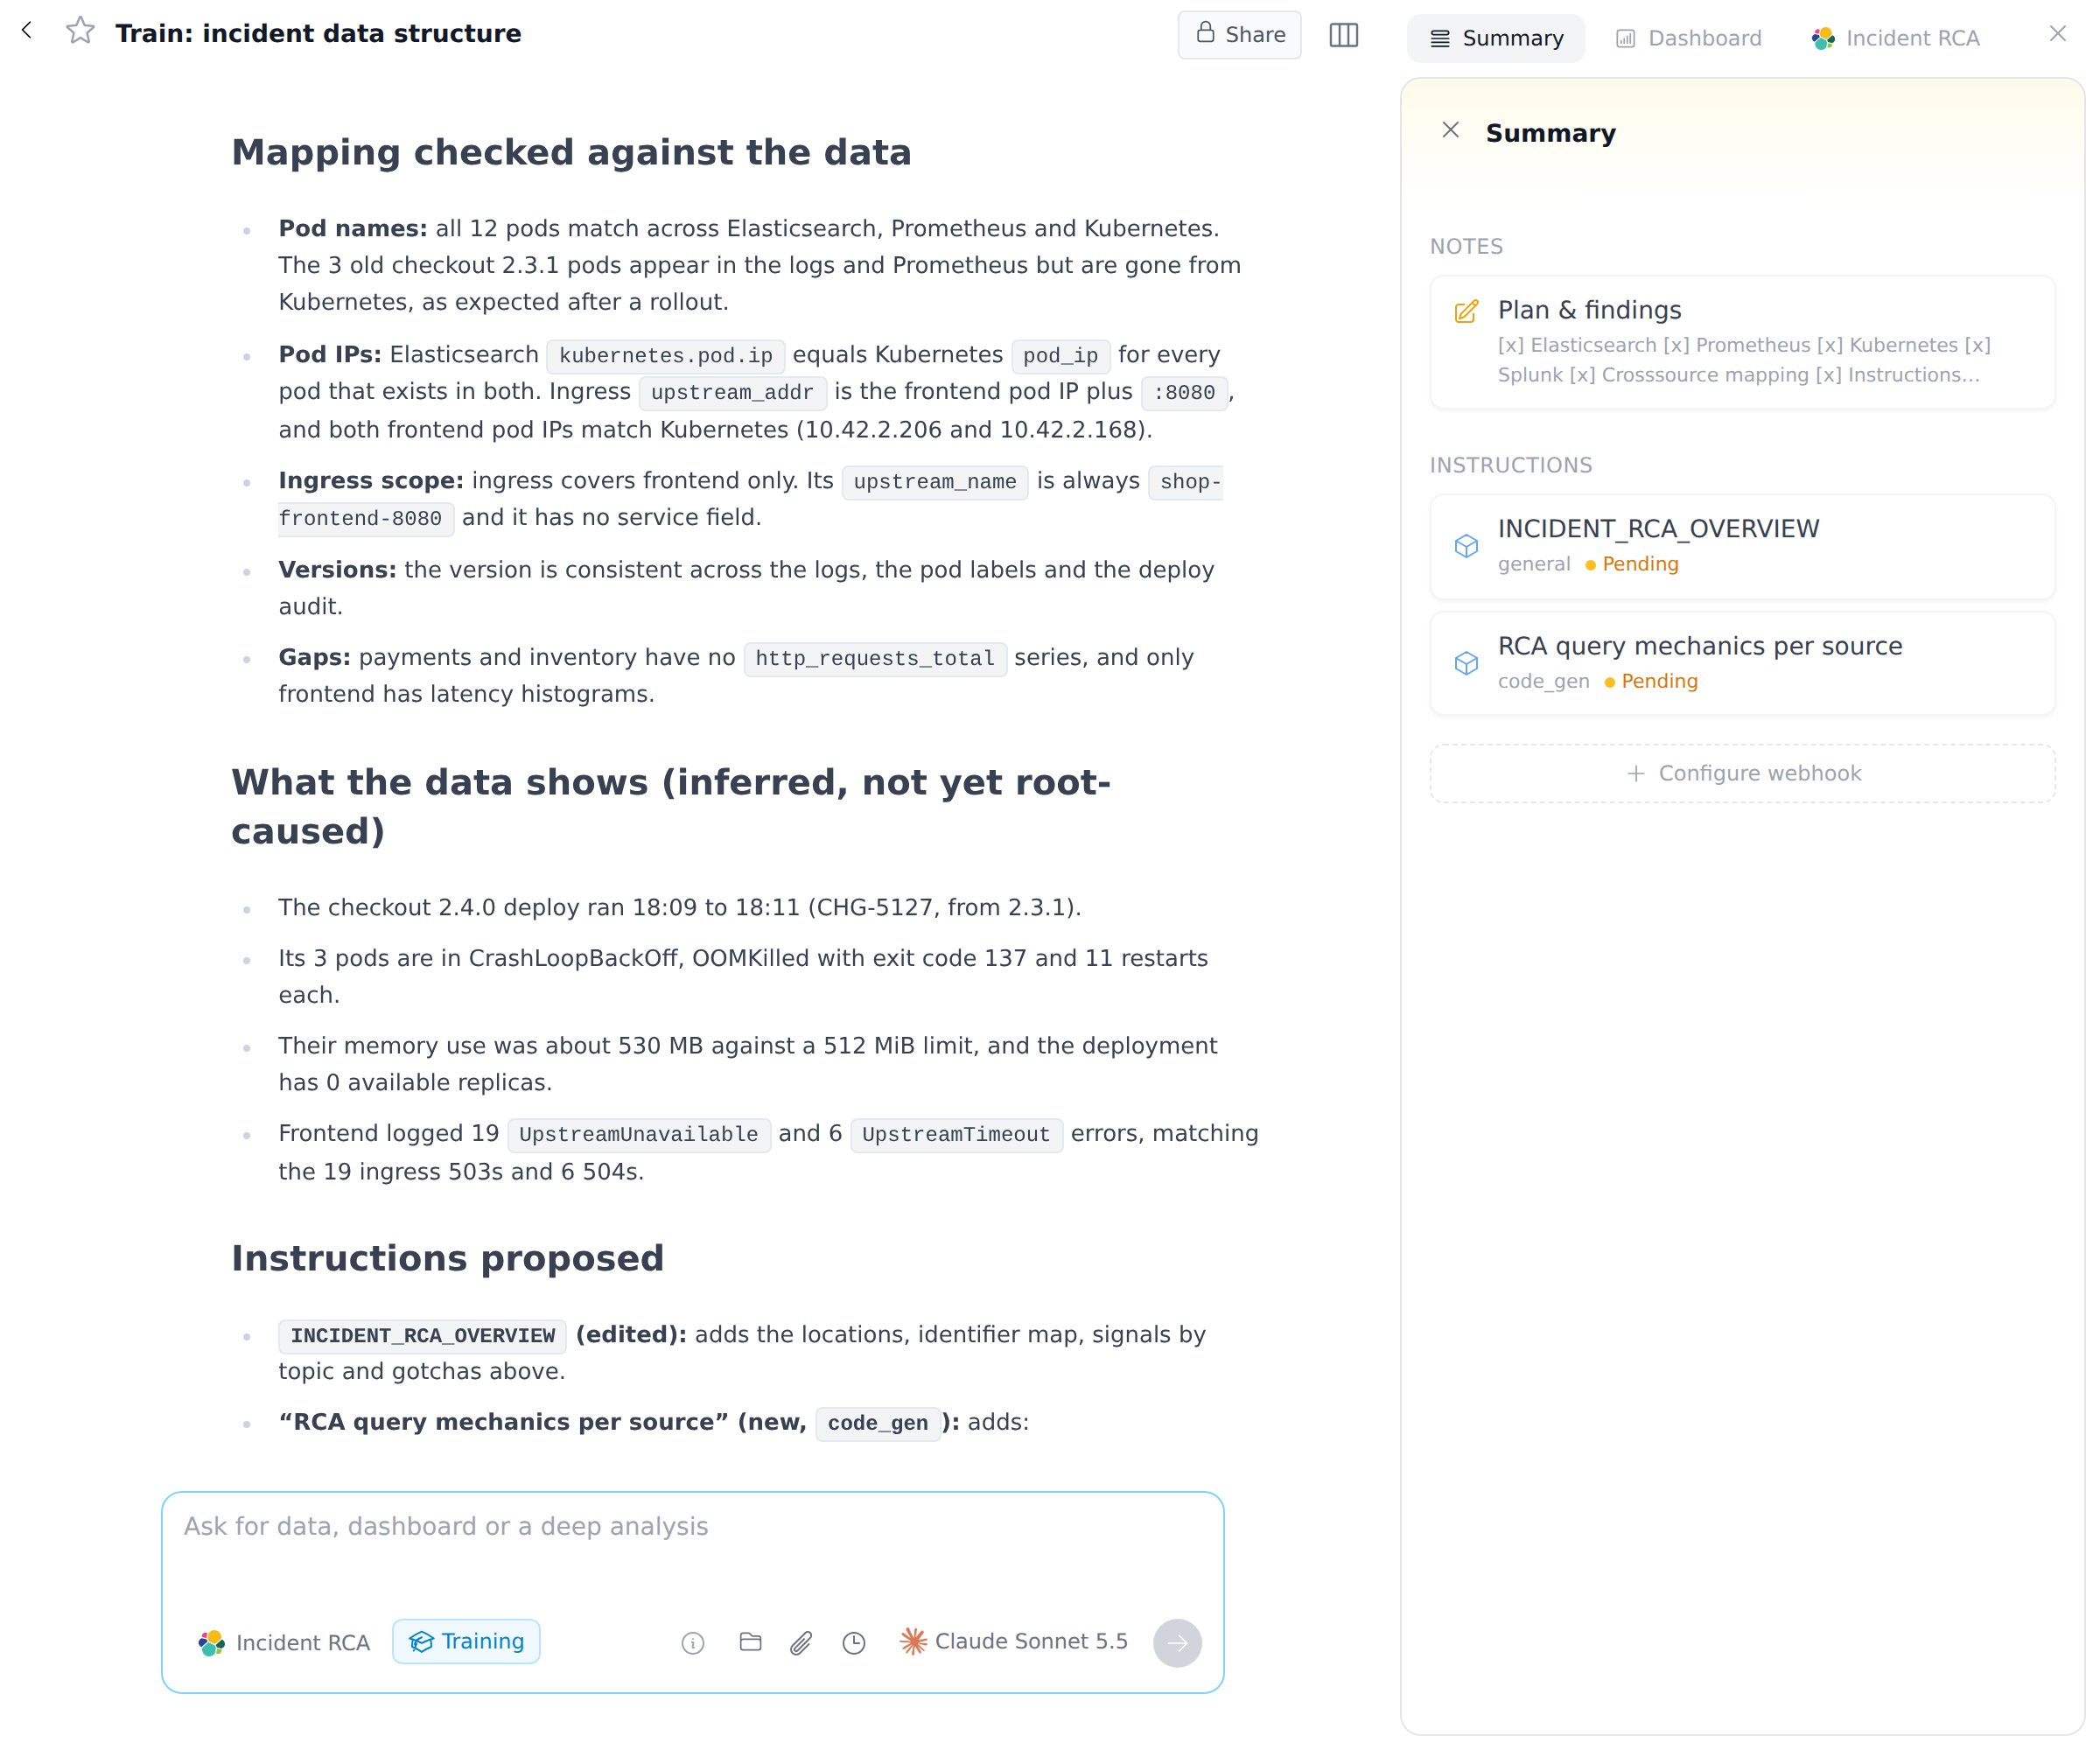 It proposed two changes: an edit to the agent's overview instruction with the identifier map, and a new instruction with query mechanics for each source, such as "use deltas for Prometheus counters" and "aggregate on `message.keyword`". Review each card and click **Accept all** or **Accept**. See [Train an agent](/agents/train-an-agent#step-5-review-and-accept-the-changes) for how review cards work.
Read the end of the answer too. The agent lists what it could not confirm, and flags rules that may only describe today's data. Here it pointed out that one line ("`log.level` values are lowercase") described one day of logs, not a rule. Ask it to fix that in the same session:
> Good. Accepted both. Now remove the lowercase log.level line from the overview, since it only describes today's data.
 Structure questions worth asking in any stack: "Which field links a log line to a pod?", "Are the timestamps all UTC?", "Which metrics are counters?", "Which sources cover which services?". Ask the agent to answer each one from the data, not from the field names.
## Step 3: Add conventions every agent follows
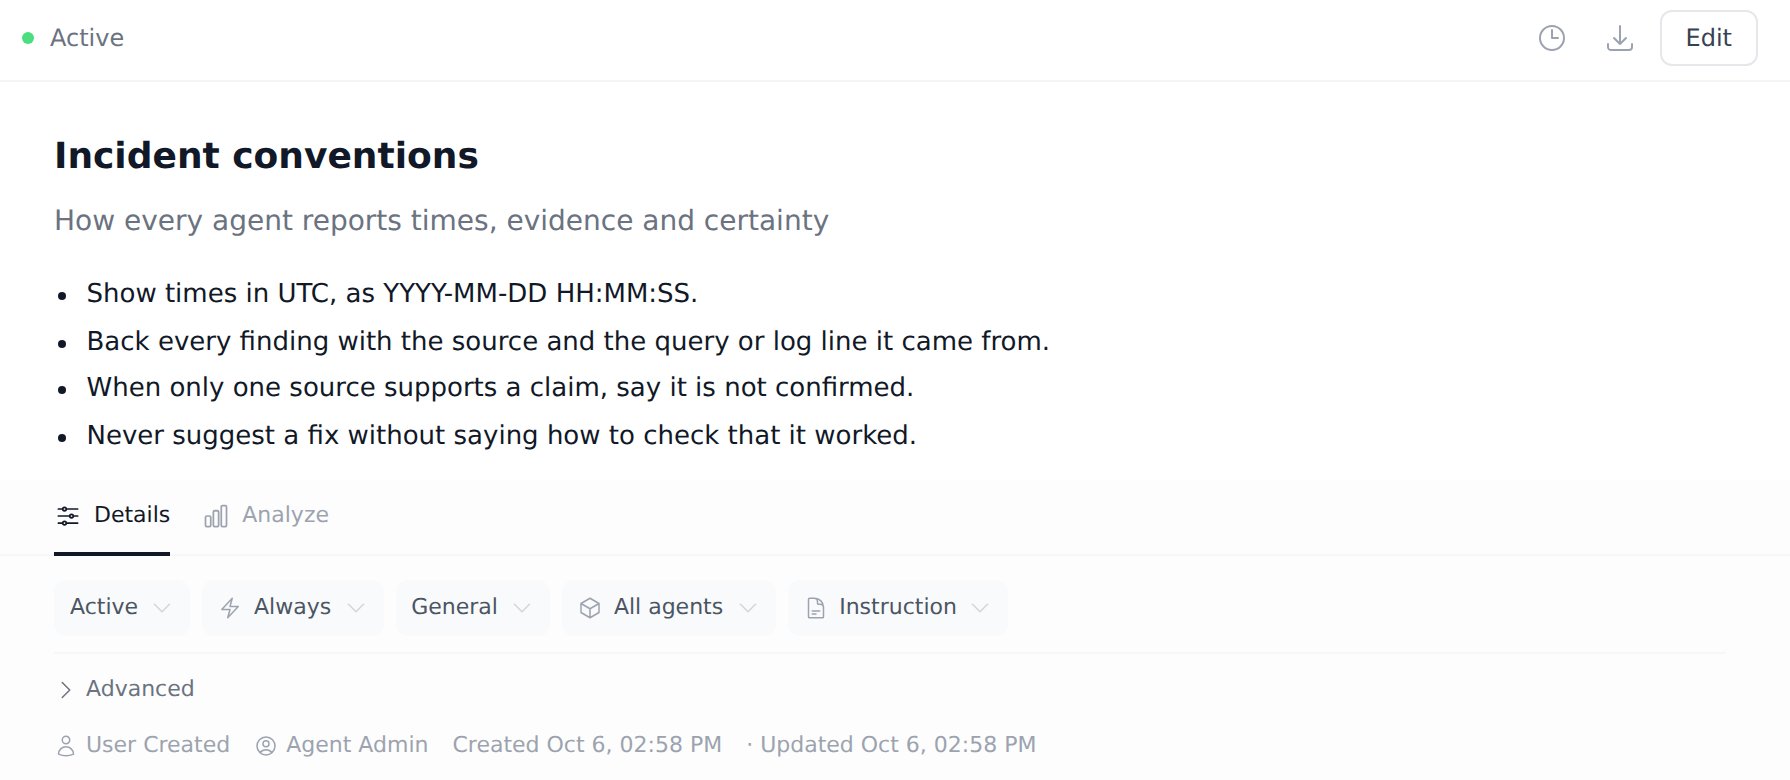
Some rules are not about one agent's data. They are how your team expects any investigation to be reported. Put these in a global instruction, so every agent follows them, including agents you add later.
Open **Agents → New → Instruction**. Leave **Agents** on **All agents**, keep **Load** on **Always**, and write the conventions:
```markdown wrap theme={null}
- Show times in UTC, as YYYY-MM-DD HH:MM:SS.
- Back every finding with the source and the query or log line it came from.
- When only one source supports a claim, say it is not confirmed.
- Never suggest a fix without saying how to check that it worked.
```
 ## Step 4: Write your RCA playbook as a skill
The data can't tell the agent what to check first when something breaks. That comes from your team's experience, so write it down as a playbook.
Create another instruction, set its type from **Instruction** to **Skill**, and leave **Agents** on **All agents**. A skill loads when it's relevant: the agent sees its title and description, and reads the full text when a task calls for it. The description decides when it gets used, so make it specific: *Use when investigating an alert, outage, error spike, latency spike or crash.*
Here is the playbook from this example. Copy it and change the sources and steps to match your stack:
```markdown wrap theme={null}
## 1. Pin the scope
- Take the service, namespace and start time from the alert.
- Search from 30 minutes before the alert started until now. Widen only if nothing turns up.
## 2. Check what changed
- Deploys: the deploy audit log in Splunk, and new ReplicaSets or rollouts in Kubernetes,
for the alerting service and the services it calls.
- A change that lands shortly before the symptom is the first suspect, not the answer. Confirm it in step 3.
## 3. Follow the symptom
- **5xx errors on a service:** group its error logs by message in Elasticsearch. Note which upstream
the errors name. Then check that upstream's pods in Kubernetes: restarts, last state, events.
- **Latency:** p99 for the route in Prometheus. Then CPU and memory of the upstream pods.
Then timeout or slow-query logs.
- **Pod restarts or crashes:** container last state and exit code, and BackOff events, in Kubernetes.
Memory against the limit in Prometheus. The last log lines before each restart in Elasticsearch.
- **Traffic drop:** ingress logs in Splunk by status and upstream.
## 4. Confirm before you name a cause
- The cause must start before the symptom.
- The timing must line up in at least two sources. If only one source supports it, say so.
## 5. Answer
1. One-line summary.
2. Timeline in UTC, one line per event, with the source of each line.
3. Root cause, and the evidence for it.
4. Impact: what failed, how much and for how long.
5. Suggested fix, and how to check that it worked.
```
Keep each step to what to check and in what order. Leave out query syntax: the agent already learned how to query each source in Step 2, so the playbook stays short and works across agents.
## Step 5: Investigate an alert
Start a new report with the agent in **Chat** mode and paste the alert:
> \[FIRING:1] HighErrorRate shop/frontend — 5xx ratio on POST /api/checkout is 63% (threshold 5%) for 5m. severity=P1 namespace=shop started=2026-10-06 18:14 UTC. What's the root cause?
The agent reads the playbook, then checks the deploy audit, the error logs and the pod state in parallel (shown at the top of this page). In under a minute it answered in the playbook's format:
* **Summary.** The checkout 2.4.0 deploy introduced an out-of-memory bug in the product cache warm-up. All three checkout pods are OOM-killed and restarting, so the frontend has no healthy checkout endpoints.
* **Timeline**, each line with its source. Deploy started at 18:09:20 (Splunk). New pods at 18:10:00 (Kubernetes). First `OutOfMemoryError` at 18:12:38 (Elasticsearch). First frontend "no healthy endpoints" error at 18:13:39 (Elasticsearch). Alert at 18:14.
* **Root cause and evidence.** OOM errors in the logs, `OOMKilled` with exit code 137 and 11 restarts on every new pod, and the cause comes before the symptom.
* **Fix.** Roll back to 2.3.1, and how to check that it worked.
Following the conventions, it also said what it had not checked: "I did not check Prometheus memory against the container limit." Ask it to close that gap:
> Confirm it in Prometheus. Chart checkout memory against its limit, and the 5xx ratio on /api/checkout, from 17:50 to 18:40 UTC.
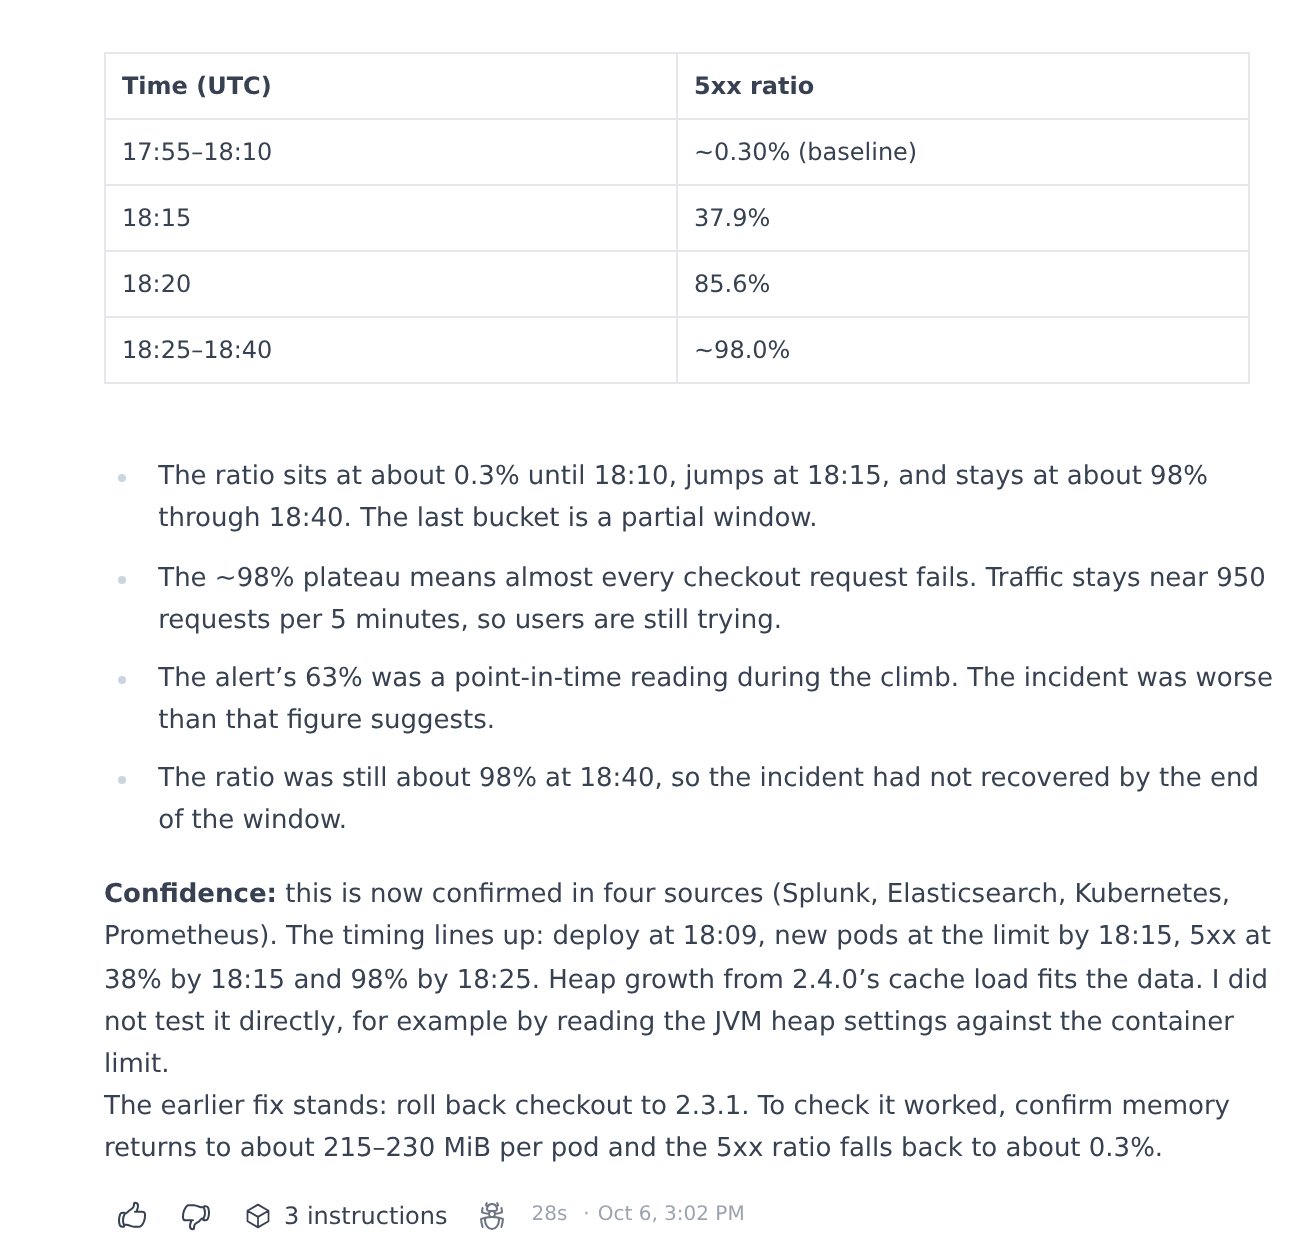 The 5xx ratio sat at 0.3% until 18:10, reached 38% at 18:15 and 98% at 18:25. The new pods ran at their memory limit. The cause is now confirmed in all four sources.
## Step 6: Improve the playbook from what you see
Each investigation shows you what to add. In this run the first answer skipped Prometheus, even though the playbook mentions it for crashes. If a step should never be skipped, say so in the playbook. Open the skill, click **Edit**, and add a line under **Confirm before you name a cause**:
```markdown wrap theme={null}
- Always include the Prometheus view: the error rate or latency for the alerting route,
and memory against the limit for any pod that restarted.
```
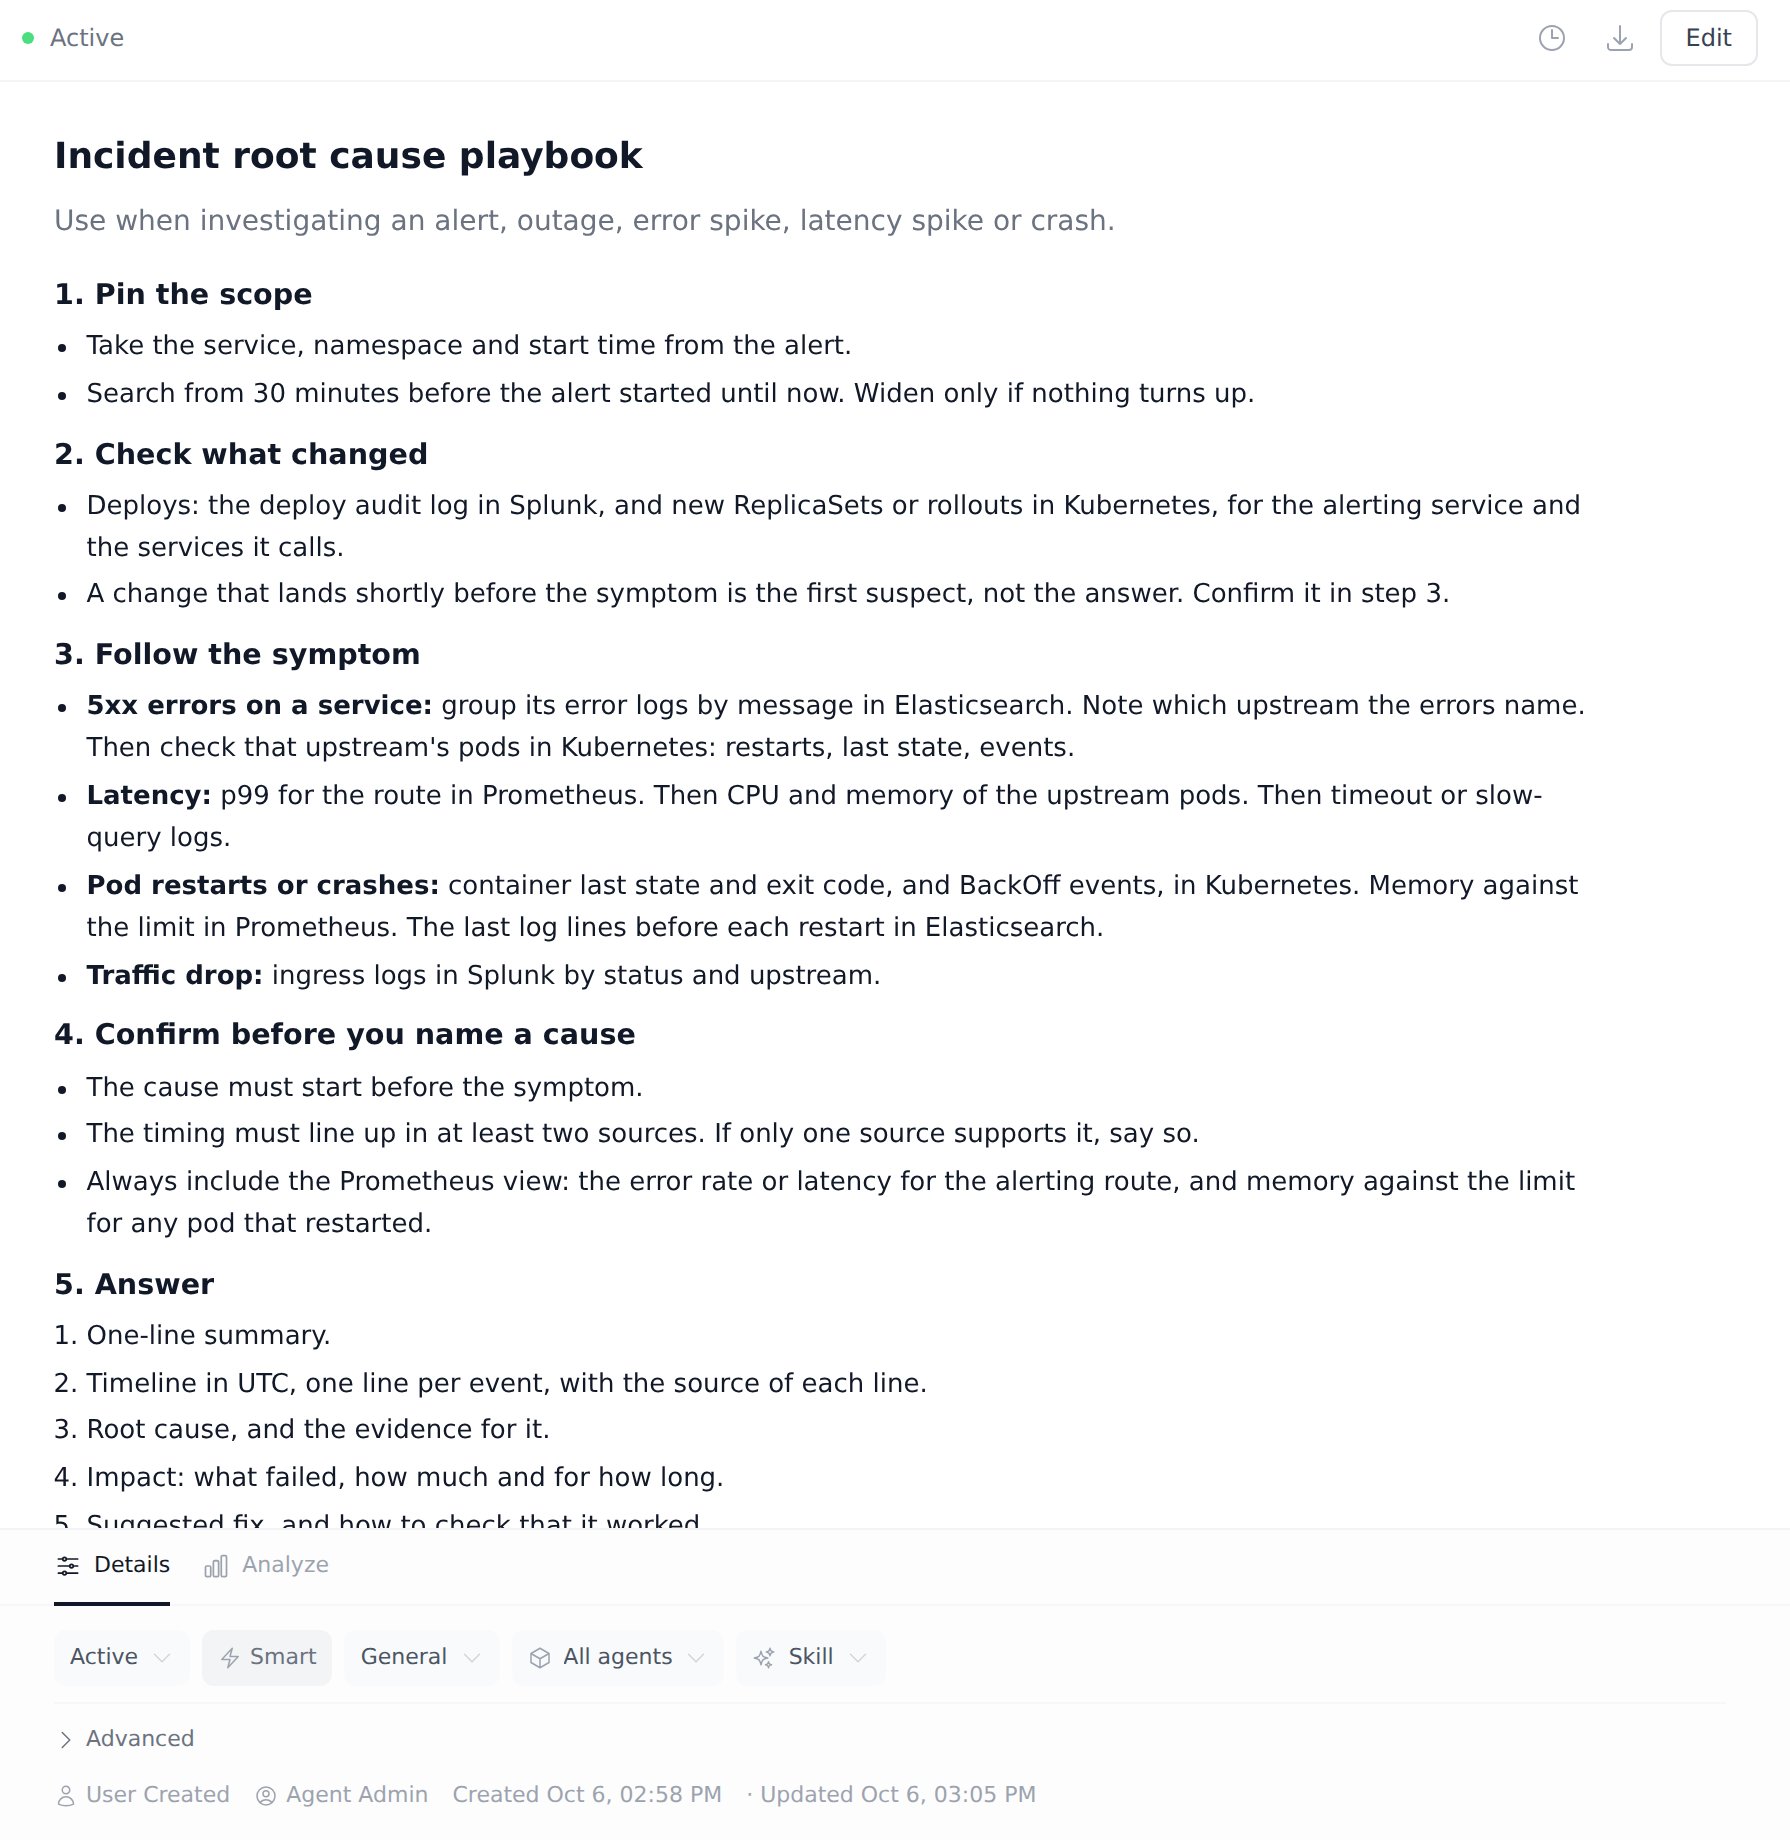 Run the same alert again in a new report. The agent now includes Prometheus queries in its first pass.
Use training for the other kind of gap: when the agent picks the wrong field, misreads units, or can't join two sources. Start a **Training** session, describe what went wrong, and review the instruction it proposes.
## Tips
* **Start from real alerts.** Replay two or three past incidents where you know the root cause. Check that the agent finds the same cause, from the same evidence.
* **Keep time windows tight.** Ask about a specific window. "Last hour" on a busy cluster returns more data than the agent needs.
* **Expect some variation.** The agent writes new queries each run, and one can come back empty. A clear playbook and the "say it is not confirmed" convention keep that visible instead of hidden.
* **Send alerts automatically.** Give your alerting tool a trigger URL, and each alert starts an investigation like the one above. See [Run an automated analysis from an external trigger](/guides/external-triggers).
* **Lock it in with evals.** Turn a past incident into an eval, so a later change that breaks the investigation shows up. See [Test an agent with evals](/guides/evals).
## Related
Run a training session and review every change.
What to teach, and where each rule belongs.
Connect Splunk, Elasticsearch and Prometheus.
Connect a cluster with a read-only service account.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.